We turned @karpathy's nanochat into a SWE-bench speedrun!
⚡ $60 of train compute → 5.0% pass@1 ≈ Claude 2 (2023 SOTA)
⚡ $1000 → 11.0% pass@1 > Claude 3 Haiku
From randomly initialized model weights!
How? 🧵👇
Come meet me at the last poster session at ICML if you are interested in chatting about LLM evaluation and pairwise comparisons! I will be presenting joint work with my advisor (Moritz Hardt).
Thu Jul 9, 5:00 PM – 6:45 PM KST, Hall A (#4411)
https://t.co/k7ySytdSzk
I'll be @NeurIPSConf presenting Strategic Hypothesis Testing (spotlight!)
tldr: Many high-stakes decisions (e.g., drug approval) rely on p-values, but people submitting evidence respond strategically even w/o p-hacking. Can we characterize this behavior & how policy shapes it?
We (Moritz Hardt, @walesalaudeen96,@joavanschoren) are organizing the Workshop on the Science of Benchmarking & Evaluating AI @EurIPSConf 2025 in Copenhagen!
📢 Call for Posters: https://t.co/jeXRNDexuX
📅 Deadline: Oct 10, 2025 (AoE)
🔗 More Info: https://t.co/zZmkGzGsRg
Had the most wonderful internship with the Social Foundations of Computation group at the Max Planck Institute for Intelligent Systems! Led by Moritz Hardt, this group has given me so much hope for what computer science can be, both in terms of research topics and group community
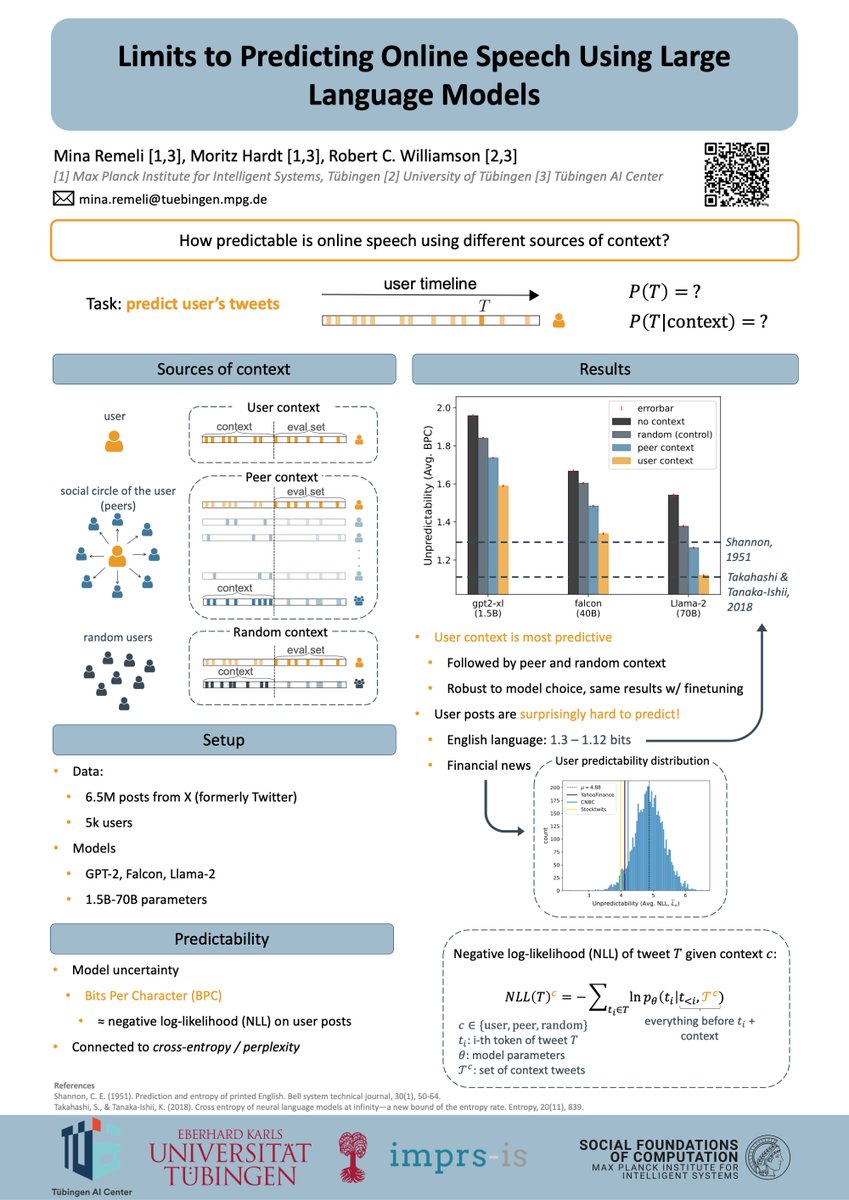
I'm proud to present a project that I've been working on a long time at the 'Humans, Algorithmic Decision-Making and Society' workshop on Saturday at #ICML24 🥳 It's about how predictable what we post online is using LLMs!
arxiv: https://t.co/cdkQtZ5HLr
To all *ML model builders* (esp if you're working on models outside academia! 👀)
We're looking for your input to help understand what kind of data-centric explanations are helpful and needed in the model development process. Please consider taking part: https://t.co/Qe9oRJUQaK
"Position: Considerations for Differentially Private Learning with Large-Scale Public Pretraining," with @florian_tramer & Nicholas Carlini got an #ICML2024 best paper award!
https://t.co/v02qYS2uJK
🧵: the personal side of this research, emotional high & lows, & more 👇 1/n
As a quick reminder: AI doomerism is also #AIhype. The idea that synthetic text extruding machines are harbingers of AGI that is on the verge of combusting into consciousness and then turning on humanity is unscientific nonsense. 2/
I don't understand how anyone can believe LLM+plugins won't be a security disaster.
Take a simple app: "GPT4, send emails to people I'm meeting today to say I'm sick"
Sounds useful!
For this, GPT4 needs the ability to read your calendar and send emails.
What could go wrong..?
📅 Are we working too much?
A major UK trial of the #4DayWeek suggests it boosts employee wellbeing, while maintaining productivity.
Delve into the latest research from @BrendanBurchell @_davidfrayne @_niamhbh@CamSociology 👇
Sorry for the confusion around the #TwitterAPI - the site I (and many others) linked seem to be older than Feb 2023 according to the Wayback Machine. Also, the pricing is for an older version of the API (Premium v1.1).
https://t.co/FGHS1oTPuC
@elonmusk this is really expensive. So far Twitter has been one of the most transparent platforms when it comes to research access, and it would be a huge step back if this will be cut off.
Here is what you can (probably) expect starting tomorrow regarding the #TwitterAPI:
- ONLY 2 API endpoints: 30-day Search and full archive Search
- what you can access for free: 25k tweets from the 30-day archive and 5k tweets from the full archive PER MONTH