Don't think of LLMs as entities but as simulators. For example, when exploring a topic, don't ask:
"What do you think about xyz"?
There is no "you". Next time try:
"What would be a good group of people to explore xyz? What would they say?"
The LLM can channel/simulate many perspectives but it hasn't "thought about" xyz for a while and over time and formed its own opinions in the way we're used to. If you force it via the use of "you", it will give you something by adopting a personality embedding vector implied by the statistics of its finetuning data and then simulate that. It's fine to do, but there is a lot less mystique to it than I find people naively attribute to "asking an AI".
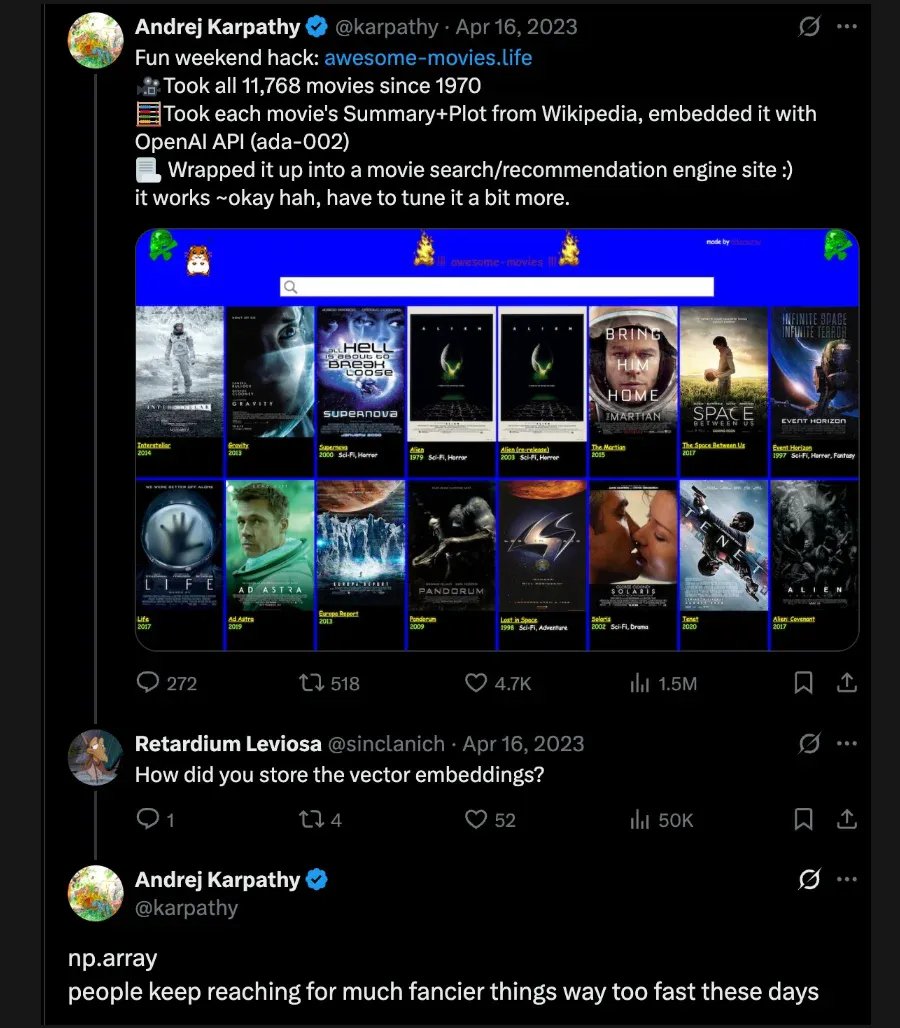
Every LLM course seems to push for the whole Vector DB, RAG pipleline, I get that they are going for scale but a weekend app which doesn't have more than 5MB of embeddings doesn't need a vector DB, a numpy array will do, is there anyone teaching from first principles like this?
Building apps on top of local LLMs makes you obsessively resource-conscious, optimizing RAM down to the last MB like my life depends on it lol
I am the server now and RAM is my AWS bill
@striver_79@cursor_ai You can try something like 'Taskmaster' on top of Cursor. It creates subtasks based on your requirements doc and then executes them one by one, so you're fully in control of what you want to build and review easily how cursor wants to execute a subtask and correct it