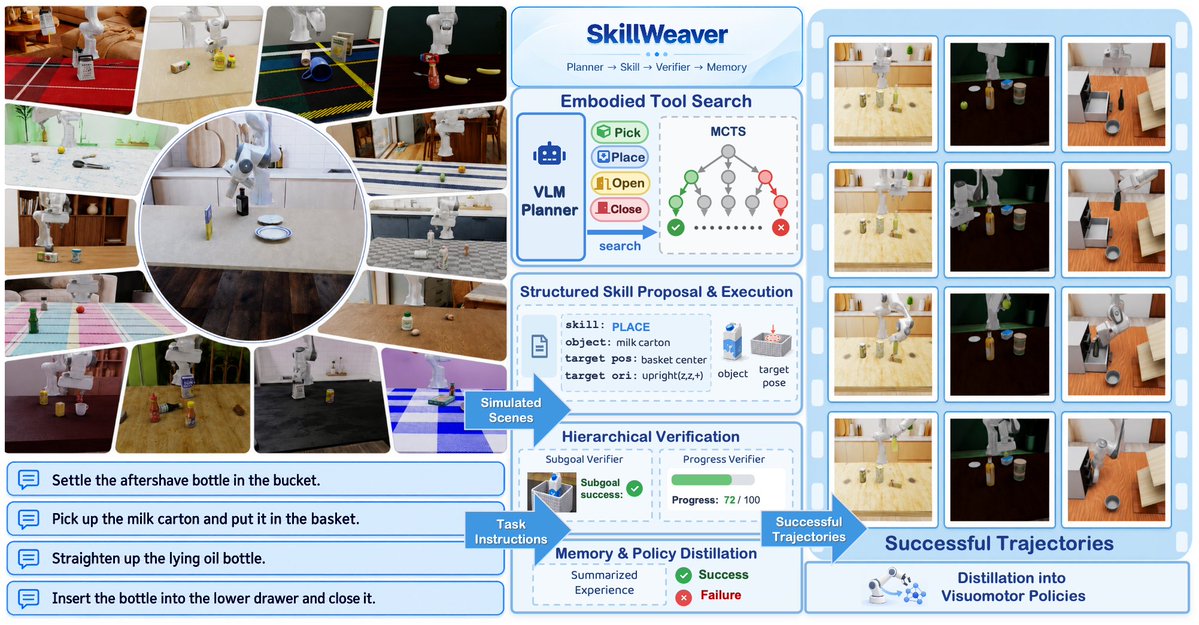
Can robots generate their own training data at scale? 🤖
Come check out SkillWeaver at #CoRL2026 tomorrow! We leverage agentic exploration over learned neural interaction skills to generate large-scale robot data in simulation, enabling stronger generalization and sim-to-real transfer.
📍 Poster #90 | Nov 11, 10:30 AM–12 PM
https://t.co/8i5NsmT4K4
https://t.co/6EoyJ2syoc
So happy to make my first post here!
Still remember how cool it was to hear “Kirov reporting” the first time our agent built a Kirov while I was checking the GEPA results.
I learned a lot from contributing to this project. My biggest takeaway is that harness design, post-training, and System 1/2 integration are interconnected. Improving one in isolation just shifts the bottleneck elsewhere. These different components need to co-evolve as one unified system.
Try it on https://t.co/Xmjb9TddPw and to play against one of our best models!
We gave open-source decision models two games. It did not go well. 🫠
🎮 Red Alert 2: the base model sold its own base. Then lost.
💥 Tank War: v1 spun in circles. v2 found the fire button… and shot itself.
So we let them keep learning: play → train → upgrade the harness → repeat. A few rounds later: model can evolve without human intervention
Then we put different models in one arena and let them fight it out. So far, no human has beaten the trained models. 😅
The lesson: a decision model isn't finished when it's released. Real environments keep throwing new situations at it, and a frozen model can't adapt. It needs continuous learning!
It's all open source: how we train these models to play, end to end. Next, we're turning it into training infra for any decision model.
⭐ Star it, fork it, or bring your own model to the arena:
GitHub: https://t.co/oAPAOkBRn0
RA2: https://t.co/xMv6VNaE11
Tank War: https://t.co/xttz2fjeWe
I also appreciate all the suggestions and feedback from: @b_vasilescu , Greg Ganger, @p0nk , @lateinteraction , @matei_zaharia , and @heathercmiller
And thanks to all the Contributors to the demo and the github repo!: @Jayzou3773, @brocoliman38951,
@ShangyinT , @Xuan04263449 , chenyang yang, tianyu chen , @AlexZhang152005, @Nickzz12138,@JasonWuzh, @Leow_sss730, @ChenMoneyQ , xingyuan ding, @JunchengLi , @LakshyAAAgrawal , @ao_qu18465
We built Hermit 🐚 to make RSI and CL more comparable, verifiable, and shareable.
For researchers: Most RSI and CL work follows the same loop: the agent acts, gets feedback, and updates itself. But each research ships its own benchmark setup and its own evolver, which makes results hard to compare. Hermit puts them behind one interface, so you can swap the evolver while keeping the tasks, judge, and evaluation fixed.
For users: Pick a state-of-the-art evolver, point it at your task, and let it improve your agent from feedback automatically.
Github:https://t.co/3BcLSUdqXX
More in our blog post 👇
#HarnessEvolution #ContinualLearning #RSI #Agent
Try it on https://t.co/Xmjb9TddPw and to play against one of our best models!
We gave open-source decision models two games. It did not go well. 🫠
🎮 Red Alert 2: the base model sold its own base. Then lost.
💥 Tank War: v1 spun in circles. v2 found the fire button… and shot itself.
So we let them keep learning: play → train → upgrade the harness → repeat. A few rounds later: model can evolve without human intervention
Then we put different models in one arena and let them fight it out. So far, no human has beaten the trained models. 😅
The lesson: a decision model isn't finished when it's released. Real environments keep throwing new situations at it, and a frozen model can't adapt. It needs continuous learning!
It's all open source: how we train these models to play, end to end. Next, we're turning it into training infra for any decision model.
⭐ Star it, fork it, or bring your own model to the arena:
GitHub: https://t.co/oAPAOkBRn0
RA2: https://t.co/xMv6VNaE11
Tank War: https://t.co/xttz2fjeWe
I also appreciate all the suggestions and feedback from: @b_vasilescu , Greg Ganger, @p0nk , @lateinteraction , @matei_zaharia , and @heathercmiller
And thanks to all the Contributors to the demo and the github repo!: @Jayzou3773, @brocoliman38951,
@ShangyinT , @Xuan04263449 , chenyang yang, tianyu chen , @AlexZhang152005, @Nickzz12138,@JasonWuzh, @Leow_sss730, @ChenMoneyQ , xingyuan ding, @JunchengLi , @LakshyAAAgrawal , @ao_qu18465