We opensource OPSD-V, a method for long video generation.
🚀 We propose on-policy self-distillation for few-step AR video generators, using real long-video context to reduce long-horizon degradation while preserving fast inference.
https://t.co/JIHAPLNLAE
Excited to share OPSD-V! 🚀
We propose on-policy self-distillation for few-step AR video generators, using real long-video context to reduce long-horizon degradation while preserving fast inference.
Project: https://t.co/sOMQJTL5MV
Code: https://t.co/KeldaSA2gW
Introducing LongCat-2.0 🐱
1.6T parameters · MoE with ~48B active · 1M context
The full model behind Owl Alpha on @OpenRouter — now available.
Built for agentic coding from the ground up:
◆ LongCat Sparse Attention (LSA) — scales efficiently for 1M-context tokens
◆ Zero-Compute Experts — dynamic activation 33B–56B per token, zero wasted compute
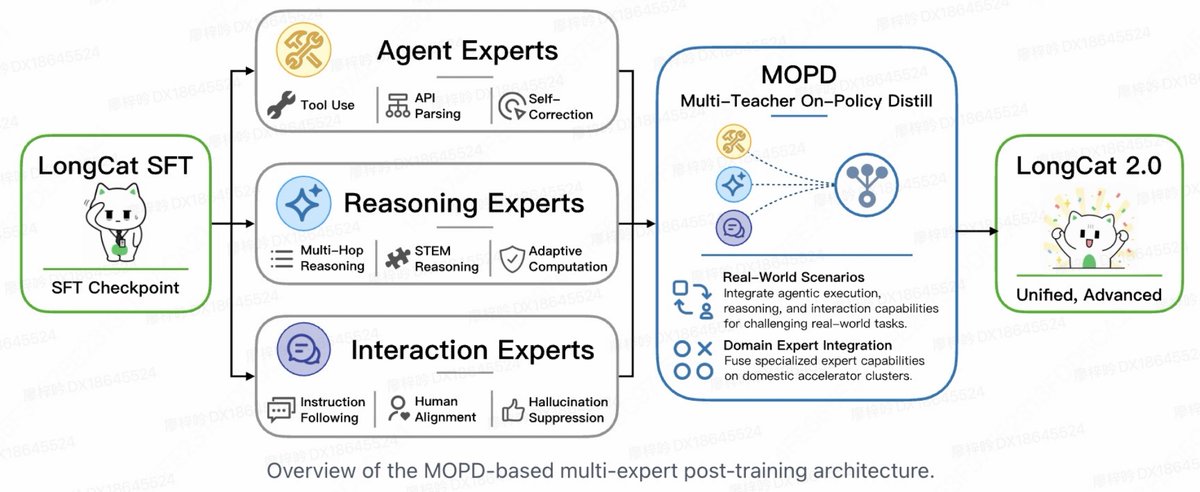
◆ MOPD — three specialized expert groups (Agent / Reasoning / Interaction), gate-routed per task
How it stacks up:
→ Terminal-Bench 2.1: 70.8
→ SWE-bench Pro: 59.5 (GPT-5.5: 58.6)
→ SWE-bench Multilingual: 77.3
→ FORTE: 73.2 · RWSearch: 78.8 · BrowseComp: 79.9
📖 Tech Blog: https://t.co/4KrjyKiDBn
Try it across different scenarios 🧵👇
Meet LongCat-Video-Avatar 1.5🐱—our upgraded, open-source digital human framework.
Built for real production, not just short demos.
What's New:
🔹 Upgraded Audio Encoder: Replaces Wav2Vec2 with Whisper-Large, yielding significantly smoother and more natural lip dynamics.
🔹 Production-Ready Stability: Achieves accurate lip-synchronization, full-body temporal stability, and robust long-video generation with strict identity consistency.
🔹 Stylized Domain Generalization: Robustly generalizes to anime, animals, and complex real-world conditions such as multi-person interactions and object handling.
🔹 Efficient 8-Step Inference: Advanced step distillation accelerates inference to 8 NFE, balancing cost-effective serving with exceptional visual fidelity.
📊 LongCat-Video-Avatar 1.5 performs strongly in realism, naturalness, and stability, outperforming leading open-source models and closed systems.
🐱 Avatar 1.5 framework is now open source:
🔗 Weights & Code:https://t.co/b9fVxTLaPs
🔗 HuggingFace: https://t.co/s4GjqxuAA2
🔗 Tech Report: https://t.co/noSnB7aFCh
🔗 Project Page: https://t.co/CCeRcWgRpl
🔥 New on ModelScope: LongCat-Video-Avatar!
We are thrilled to welcome this unified model for expressive, audio-driven character animation to our community. 🚀
Why you should try it:
✨ Versatile: Handles AT2V, Image-to-Video, & Video Continuation.
✨ Natural Dynamics: Decouples speech from motion for realistic results.
✨ High Quality: Uses "Reference Skip Attention" to preserve identity.
✨ Long Sequences: Minimal pixel degradation via innovative stitching.
👉 Download & Try it here: https://t.co/xFPBFuAZM8
Meet LongCat-Video-Avatar: a robust audio-driven avatar model that pushes the boundaries of long-form video generation.
Compared with the previous InfiniteTalk, LongCat-Video-Avatar delivers far better long-sequence stability and realism.
New highlights:
⚙ Built on the LongCat-Video architecture, now supporting Audio-Text-to-Video (AT2V), Audio-Text-Image-to-Video (ATI2V), and Video Continuation modes.
🎭 Open-source SOTA Realism: Ranked 1st in overall anthropomorphism scores for both single and multi-subject scenarios in EvalTalker evaluations (492 participants, 3 independent raters per video).
♾ High-quality long videos: Cross-Chunk Latent Stitching prevents pixel degradation and error accumulation over time, ensuring seamless stitching quality.
🔒 Long-term consistency: Reference Skip Attention maintains ID consistency while eliminating rigid copy-paste artifacts.
🪄 Supports multi-person and infinite-length video generation.
🔗Open-sourced
Code: https://t.co/b9fVxTLaPs
Hugging Face: https://t.co/TI7miIswgI
Project: https://t.co/tkUpZKSKhU
Paper: https://t.co/SO8YBXcNzm
AI video isn’t a clip anymore. It’s a scene.
LTX-2 now generates 20-second continuous, synchronized audio and video. One cinematic take from a single prompt.
Available now on LTX API Playground!
Examples with prompts + a link to try it now in the thread >>
Say goodbye to 8 second AI videos.
LTX-2 can create full 20-second movies from just one sentence, with matching sound, clear faces, and movie-like timing.
I tried it and felt like I was watching a real movie.
Here are 10 most impressive examples:
🚨 RIP ElevenLabs
Sonic 3's AI voice so natural, even Elon Musk noticed.
-40ms response (ElevenLabs: 130ms)
-Native accents, 42 languages
-Real-time speed + volume control
First voice AI that works on enterprise scale.
What makes it insane:👇
🚀 LongCat-Video Now Open-Source: Text/Image-to-Video + Video Continuation in One Model
🏆 Text/Image-to-Video Performance Hits Open-Source SOTA
🎬 Minutes-Long High-Quality Videos: No Color Drift/Quality Loss (Industry-Standout)
⚙ 13.6B Params | Strong Open-Source DiT-Based Unified Multitask Video Base Model
⚡ C2F Pipeline + Block Sparse Attention: 720p/30fps Video in Minutes
🤗 Open-Source Links:
GitHub:https://t.co/b9fVxTLaPs
Hugging Face:https://t.co/TX1k7hmcZg
Project Page:https://t.co/aRrGjchQAh
Chinese doordash dropping MIT license foundation video models???
“We introduce LongCat-Video, a foundational video generation model with 13.6B parameters, delivering strong performance across Text-to-Video, Image-to-Video, and Video-Continuation generation tasks.”
https://t.co/jPTY2Uac1S
🚀 Models BATTLE!
🎬 Infinitetalk vs. Kling-v1 vs. Omnihuman, who is the BEST AI Avatar model?
I tested Infinitetalk, Kling-v1, and Omnihuman using the same video. Here's how they compare:
✨ Infinitetalk shines with crystal-clear, natural-sounding voices.
💥 Kling-v1 impresses with avatar creation.
⚡ Omnihuman excels in avatar design.
👉 https://t.co/TeUW6tjPCE
👉 https://t.co/v4M9AWSDzN
👉 https://t.co/76riZxkSP8
#AIAvatars #VoiceGeneration #Infinitetalk #AItools #KlingV1 #Omnihuman #AIrevolution