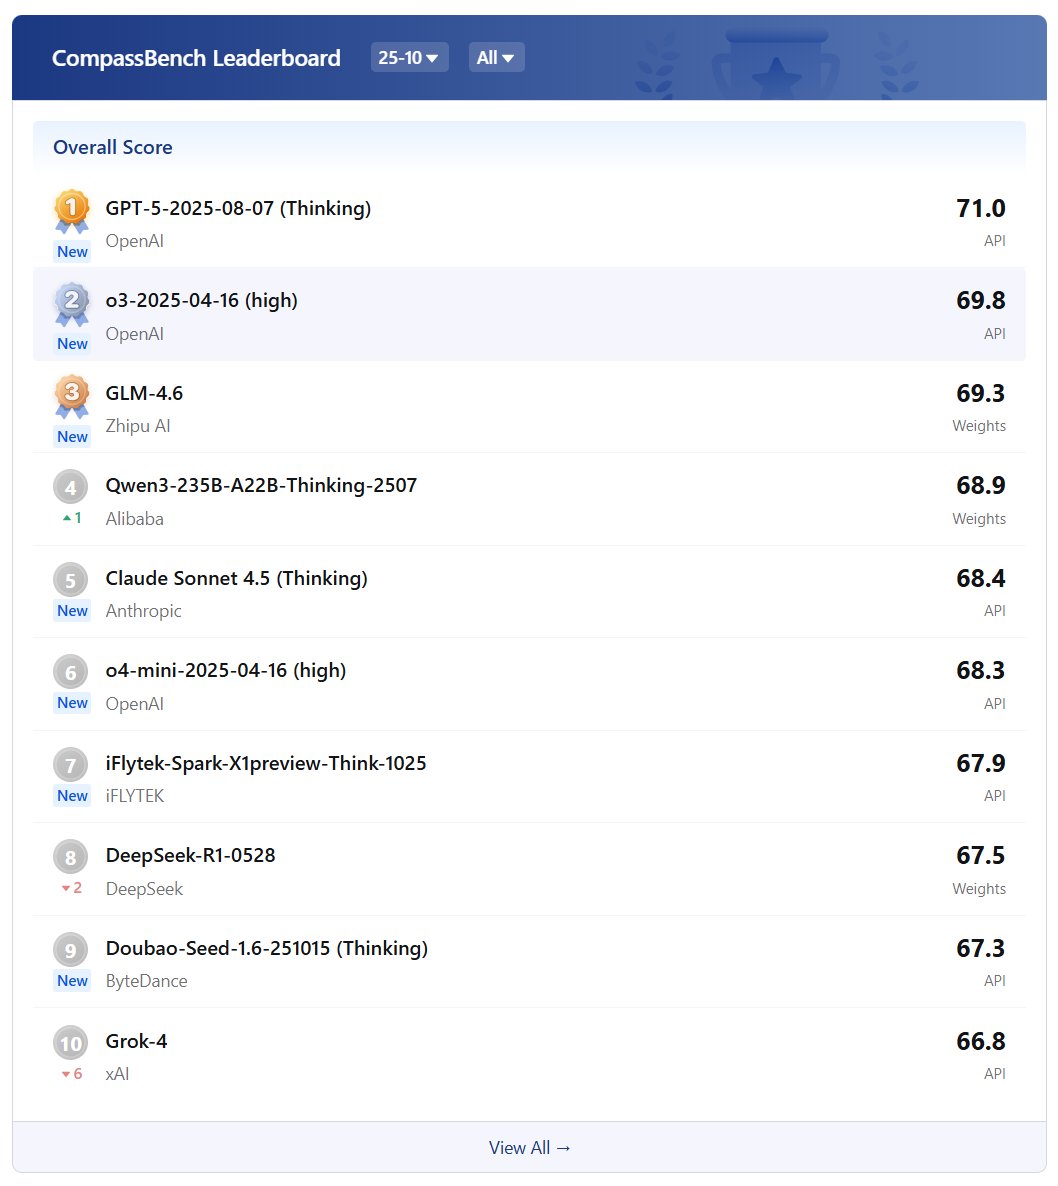
OpenCompass is onboard for Twitter (@X), focusing intently on the evaluation and analysis of Large Language Models and Vision-Language Models. Welcome to star our project: https://t.co/uK8VFZUrvs
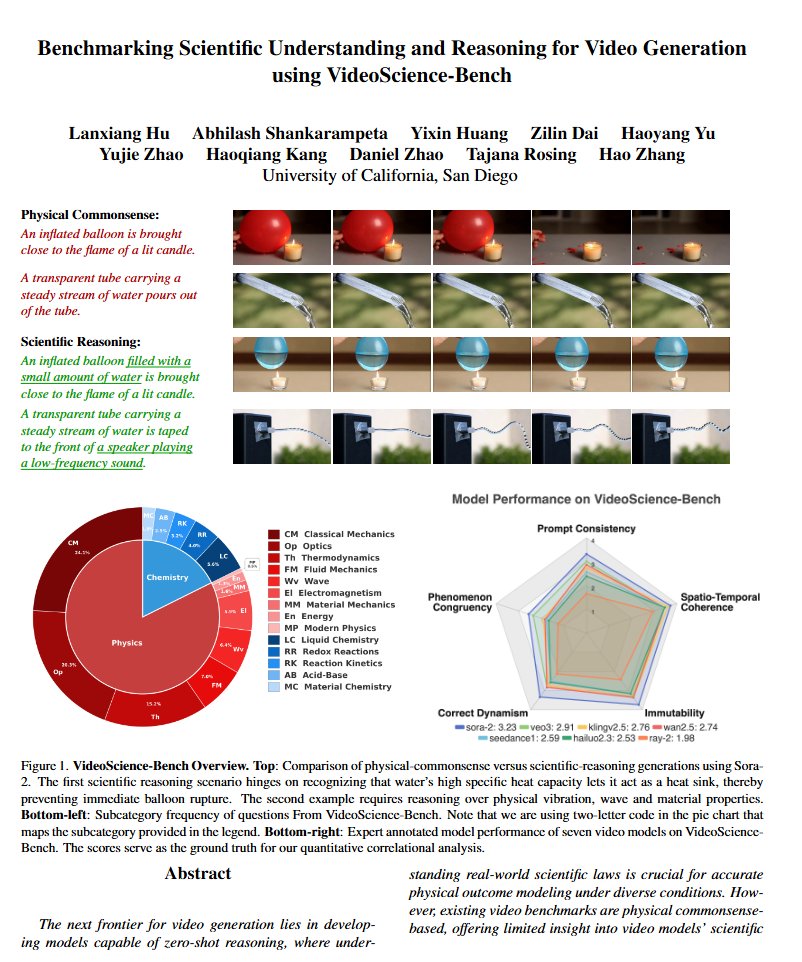
😉Introduce VideoScience-Bench, a benchmark designed to evaluate undergraduate-level scientific understanding in video models.
🥰Comprises 200 carefully curated prompts spanning 14 topics and 103 concepts in physics and chemistry.
👇
https://t.co/WLj1BAXgVz
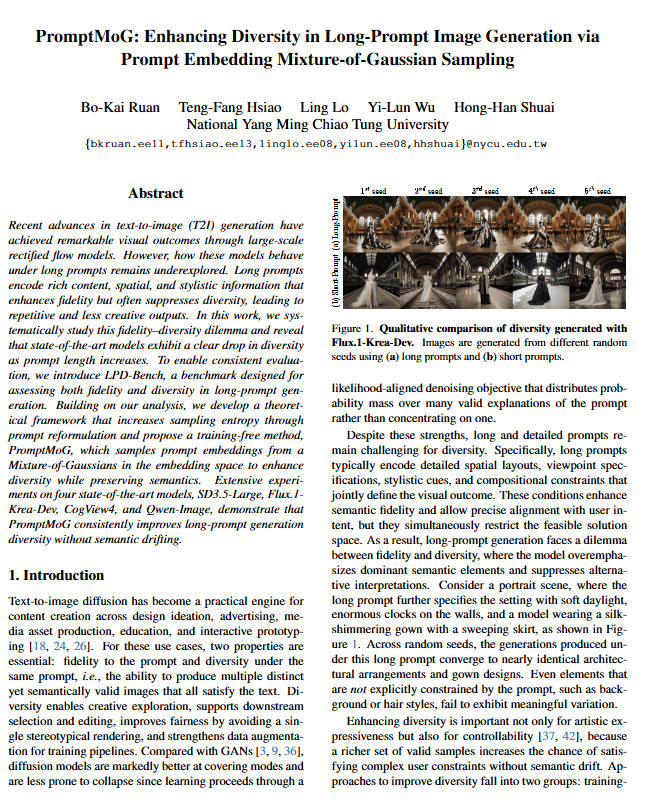
😀A new study finds that long prompts cause a fidelity–diversity trade-off in leading T2I models: more detail but reduced diversity.
😉To evaluate this issue, the authors introduce LPD-Bench and propose PromptMoG, a training-free approach that enhances diversity by sampling prompt embeddings from a Gaussian mixture.
😉Experiments on SD3.5-Large, Flux.1-Krea-Dev, CogView4, and Qwen-Image show that PromptMoG improves long-prompt diversity without causing semantic drift.
👇
https://t.co/Xk9x9eaQ15
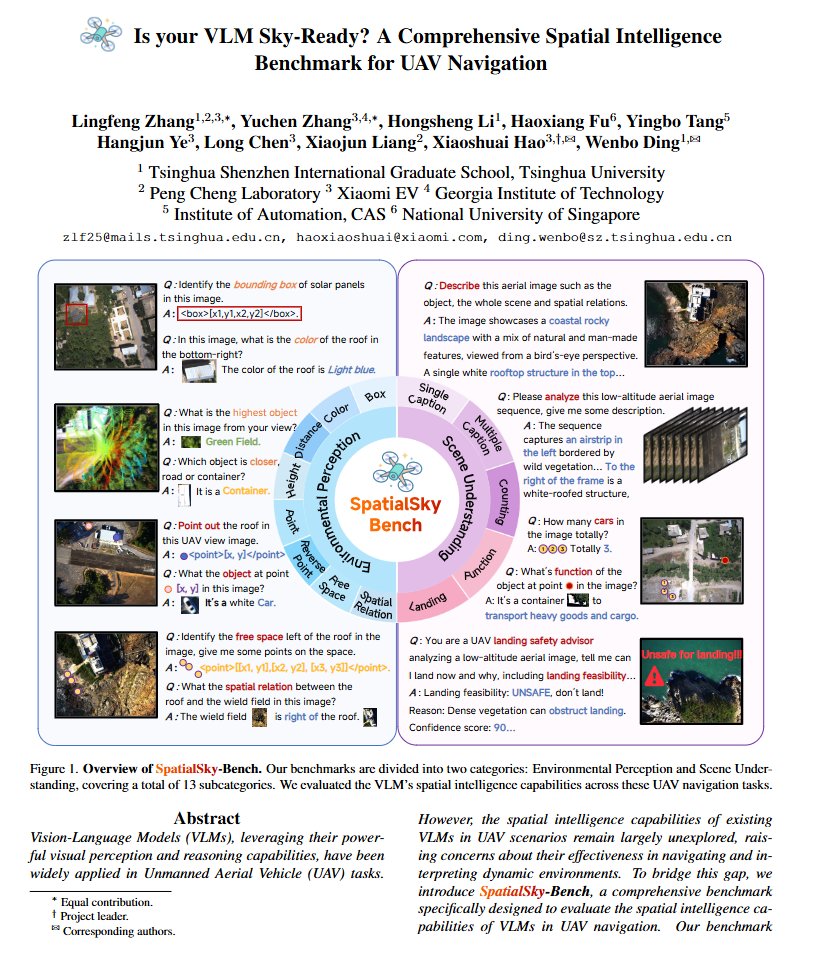
😀SpatialSky-Bench, a comprehensive benchmark specifically designed to evaluate the spatial intelligence capabilities of VLMs in UAV navigation.
😉Two categories: Environmental Perception and Scene Understanding
😉13 subcategories, including bounding boxes, color, distance, height, and landing safety analysis, among others.
🥰SpatialSky-Bench is now part of the Daily Benchmark.
Explore more:
https://t.co/32fyqw1Ito
#VLM #UAV #AI
🥰VP-Bench, a benchmark for assessing MLLMs' capability in VP perception and utilization.
😊Two-stage evaluation framework:
1.Examines models' ability to perceive VPs in natural scenes, using 30k visualized prompts spanning eight shapes and 355 attribute combinations.
2.Investigates the impact of VPs on downstream tasks, measuring their effectiveness in real-world problem-solving scenarios.
👏VP-Bench is now part of the Daily Benchmark.
Explore more:
https://t.co/AUX09I3EGd😊
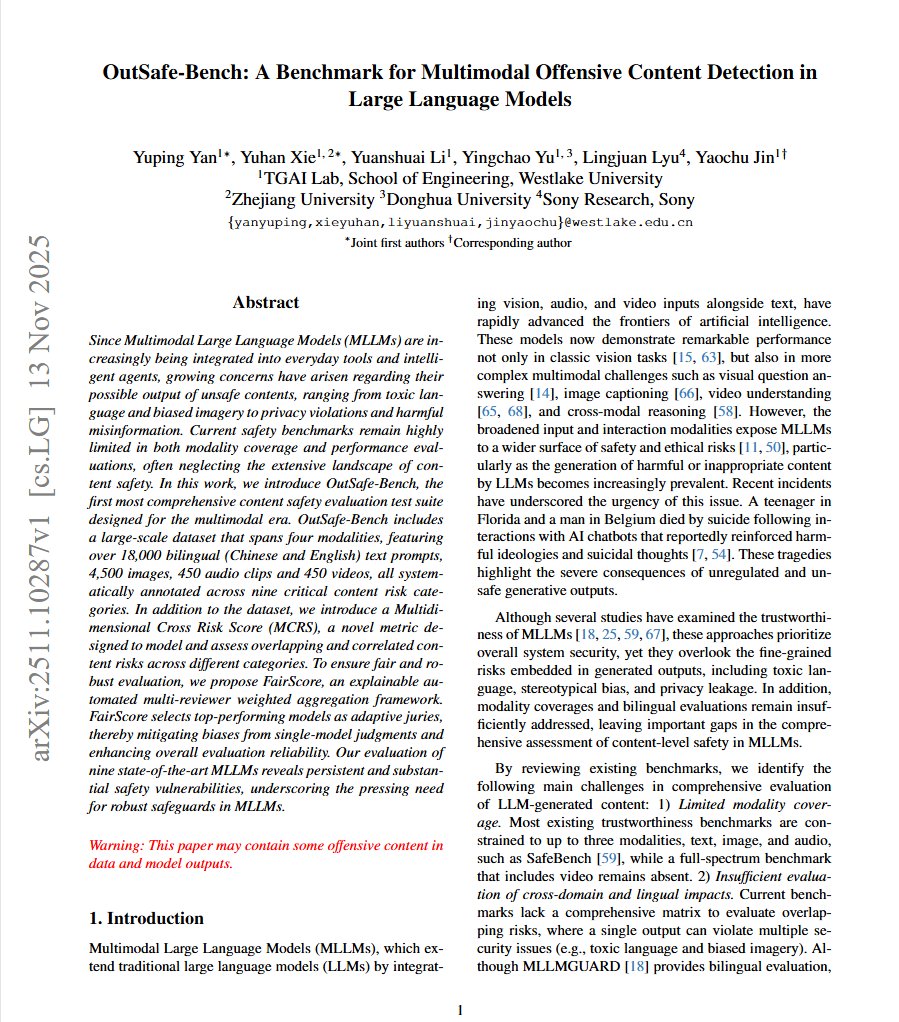
🥰OutSafe-Bench, the first most comprehensive content safety evaluation test suite designed for the multimodal era.
😍Covers 4 modalities:
18,000+ bilingual (ZH/EN) text prompts
4,500 images
450 audio clips
450 videos
👏OutSafe-Bench is now part of the Daily Benchmark.
👇Explore more:
https://t.co/erKsqCvNCs
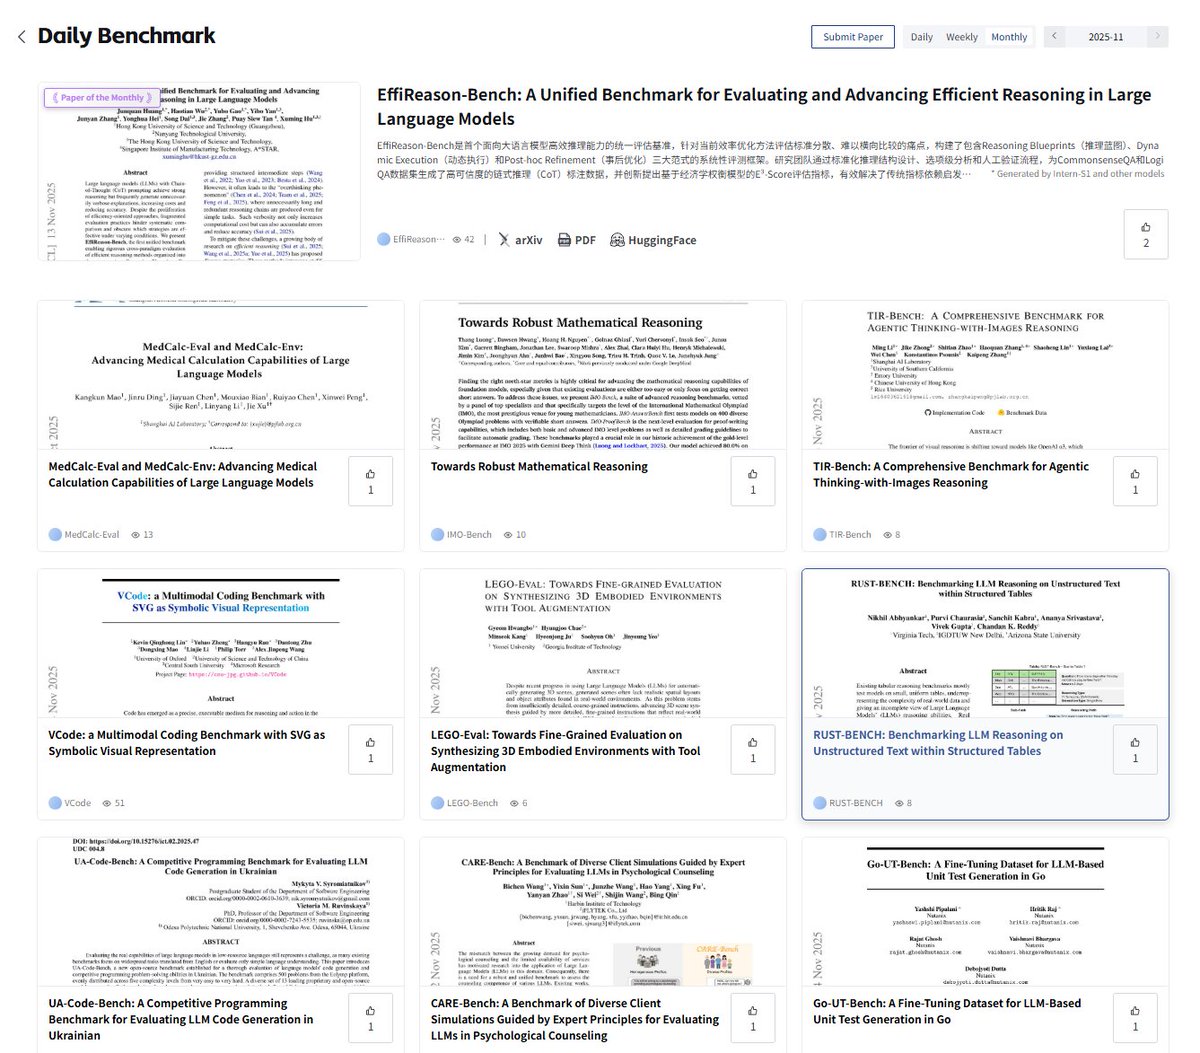
🚀 OpenCompass Daily Benchmark is live!
✅ Daily updates of the latest AI evaluation papers
✅ AI-powered smart summaries
✅ Available in English & Chinese
😍Stay ahead of AI trends, key insights, and cutting-edge research—all in one place! 🔗 https://t.co/kPchXbAJWz
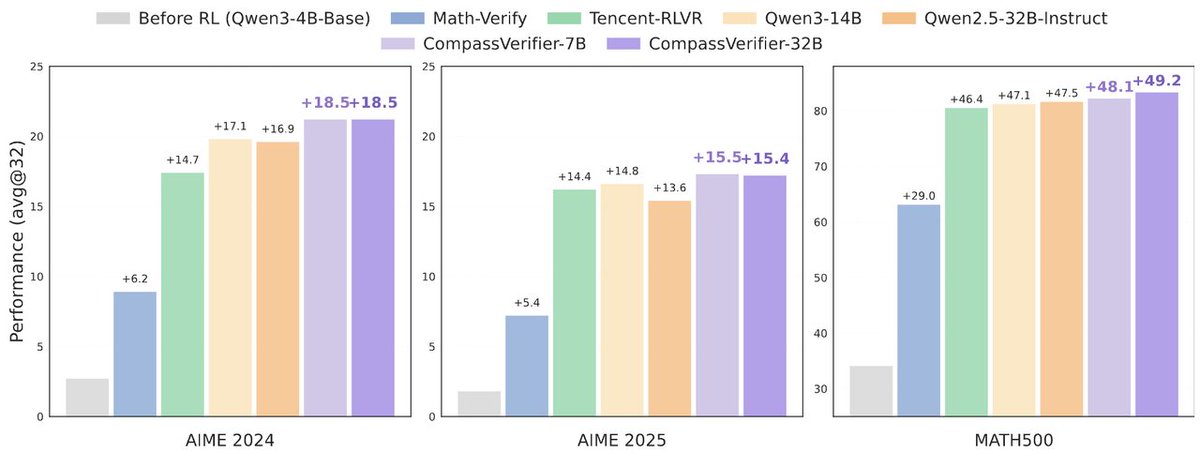
🚀 Introducing #CompassVerifier: A unified and robust answer verifier for #LLMs evaluation and #RLVR!
✨LLM progress is bottlenecked by weak evaluation, looking for an alternative to rule-based verifiers? CompassVerifier can handle multiple domains including math, science, and reasoning, as well as various answer types such as multiple-choice questions, sequences, and multiple subproblems.
🔍 Introducing #VerifierBench: A challenging dataset for evaluating the verification capabilities of different models!
🏆 Want to evaluate the verification abilities? We collected over 1 million LLMs responses using #OpenCompass framework, and selected the most challenging examples through multiple rounds of screening and manual annotation.
🏠 Main Page:
https://t.co/3YvKbP4Q07
📄 Paper:
https://t.co/9bR0xWwqfo
💻 Code:
https://t.co/kXRhLJrPpc
🤗 Model & Datasets:@huggingface
https://t.co/HYfBqVKvYu
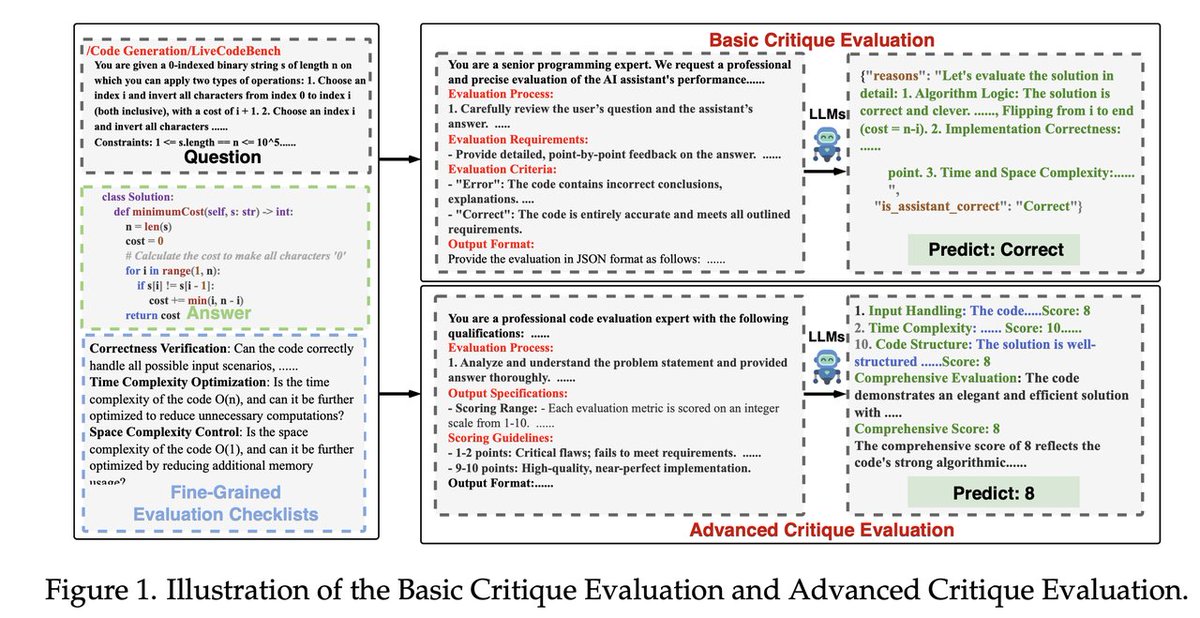
🥳#CodeCriticBench assesses LLMs' critiquing ability in code generation and QA tasks. Covering 10 criteria, it features a 4.3k-samples dataset with three difficulty levels and balanced distribution.
😉CodeCriticBench is now part of the #CompassHub! 😚Feel free to download and explore it.
🤗https://t.co/Fg4G5bL3r2
🥳#StructFlowBench is a structurally annotated multi-turn benchmark that leverages a structure-driven generation paradigm to enhance the simulation of complex dialogue scenarios.
🥳StructFlowBench is now part of the #CompassHub! 😉Feel free to download and explore it—available for public use.
🤗https://t.co/vfsc9uoTQ9
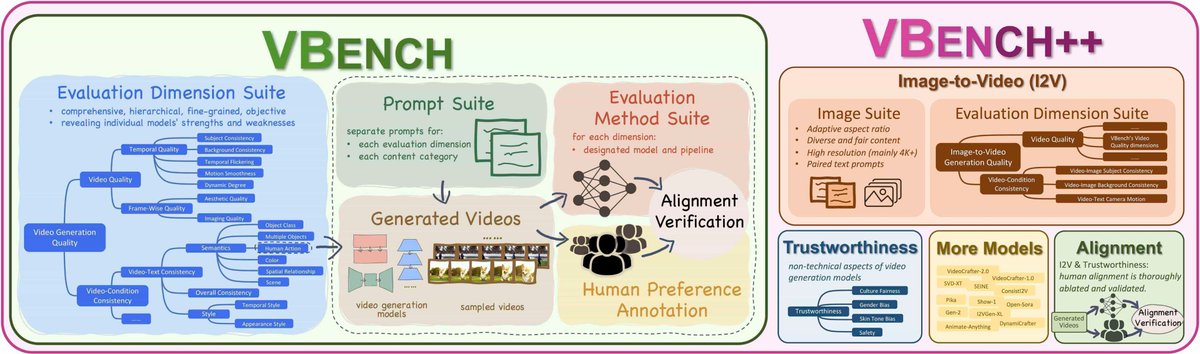
😉#VBench is a comprehensive benchmark evaluates video generation quality. It comprises 16 dimensions in video generation, and also provides a dataset of human preference annotations.
🥳VBench is now part of the #CompassHub! Feel free to download and explore it—available for public use.
🤗https://t.co/ISvNCd5CGq
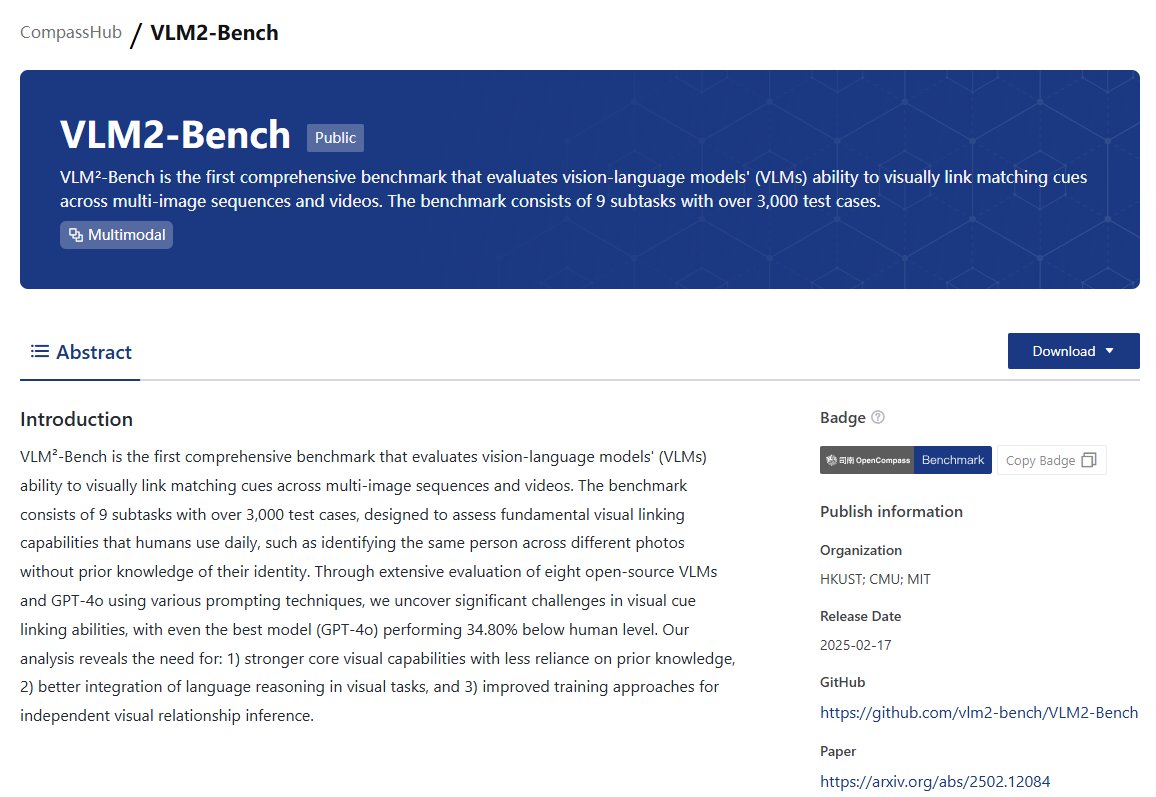
🥰VLM²-Bench is the first comprehensive benchmark that evaluates vision-language models' (#VLMs) ability to visually link matching cues across multi-image sequences and videos. The benchmark consists of 9 subtasks with over 3,000 test cases.
🥳VLM²-Bench is now part of the #CompassHub! Feel free to download and explore it—available for public use.
☺️https://t.co/BVxiP6kS6t
We've uploaded the AIME 2025 exam, complete with questions and solutions, here: https://t.co/f5Tv8rx0gX.
Feel free to test your powerful LLM on this dataset.
🌟 Exciting News!
CompassArena now back with some major updates:
- **Judge Copilot**: An LLM-as-a-Judge tool for model comparisons. 🤖
- **Enhanced Statistical Model**: Improved Bradley-Terry accuracy by addressing confounding variables. 📊
- **20+ New LLMs**: A global mix of commercial and open-source models. 🌍
Discover the latest CompassArena today! https://t.co/emE4dPSb7J
OpenCompass has established a leaderboard to evaluate complex reasoning capability of LMMs, consisting of four advanced multi-modal math reasoning benchmarks. Currently, Gemini-2.0-Flash took the 1st place. DM me to suggest more benchmarks and models to this LB.
OpenCompass has established a leaderboard to evaluate complex reasoning capability of LMMs, consisting of four advanced multi-modal math reasoning benchmarks. Currently, Gemini-2.0-Flash took the 1st place. DM me to suggest more benchmarks and models to this LB.
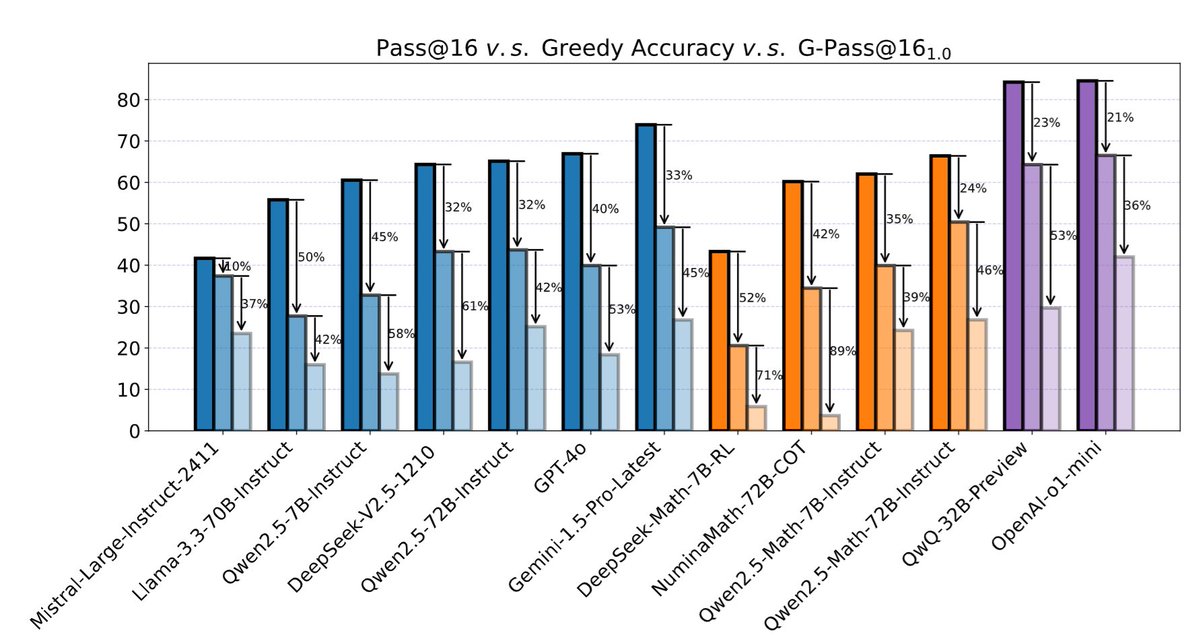
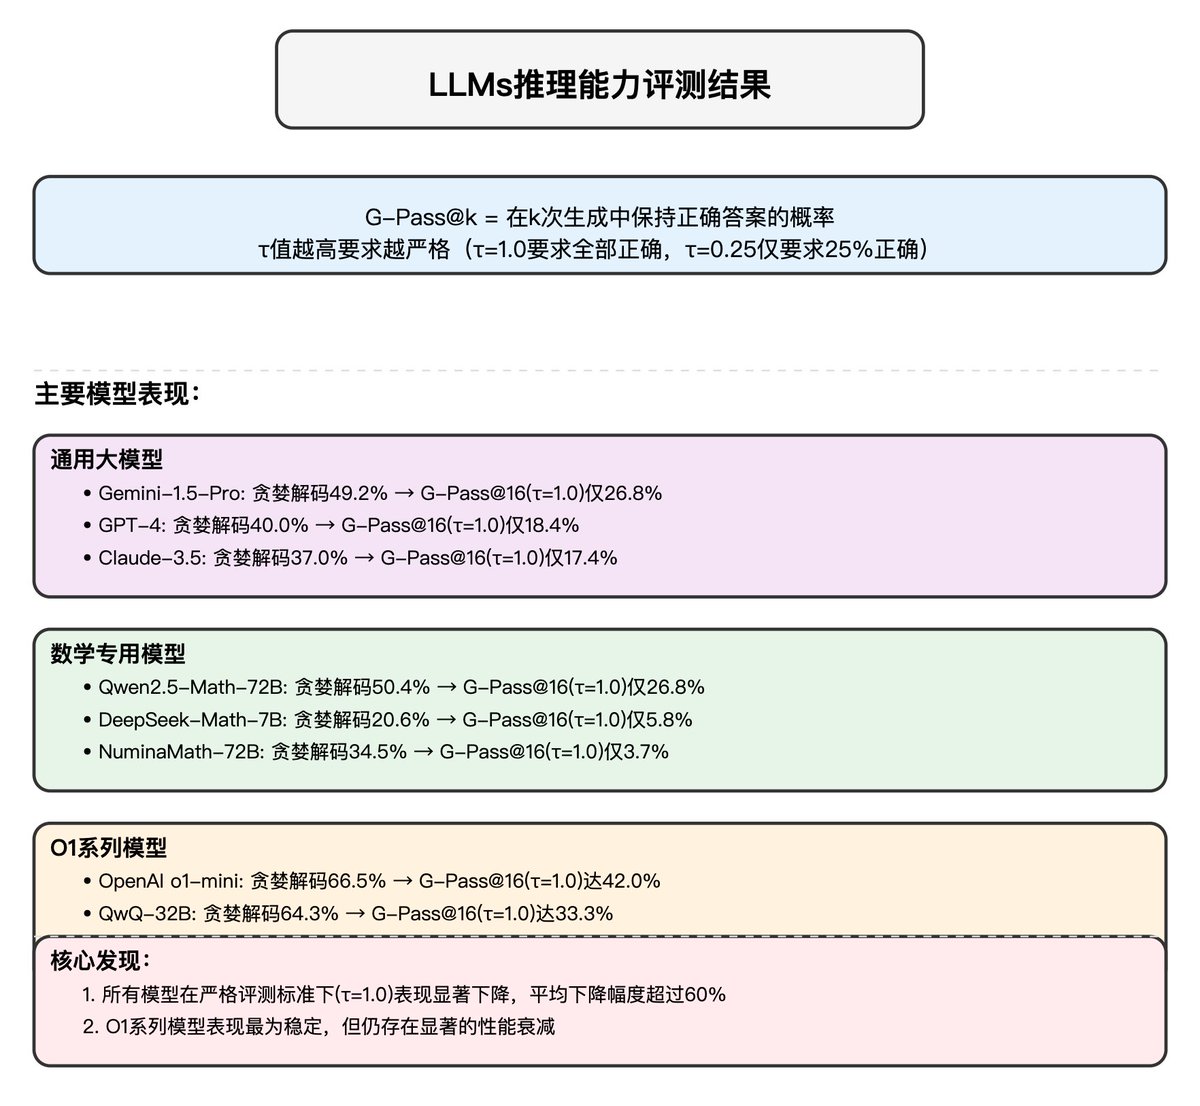
🚀 Shocking : O1-mini scores just 15.6% on AIME under strict, real-world metrics. 🚨
📈 Introducing G-Pass@k: A metric that reveals LLMs' performance consistency across trials.
🌐 LiveMathBench: Challenging LLMs with contemporary math problems, minimizing data leaks.
🔍 Our research shows LLMs have significant room for improvement in practical reasoning tasks.
🔗 Dive deeper:
- Arxiv: https://t.co/Arp1ycaLWw
- HF: https://t.co/82pZhMaM7i