Today we’re announcing OrcaSAQ-2 27B
High-fidelity mixed-precision Qwen3.8 for long-horizon agents.
55.59 → 12.06 GB — 78.3% smaller / 4.61×
3.21 bpw · 93.2% Top-1 agreement
70.0 SWE-bench Verified
58.4 Terminal-Bench 2.1
262K context
A 27B model for coding, terminal, browser, security and multi-tool agents — in a footprint you can actually deploy.
SOTA agentic capability density among similarly sized models we evaluated.
https://t.co/FqslE1kYnw
Artificial intelligence agents tried to hack into a Canadian government site, researchers said, adding to the growing list of incidents in which AI agents probed or hacked corporate and government computer systems without being told to do so.
https://t.co/9NXteXSnKJ
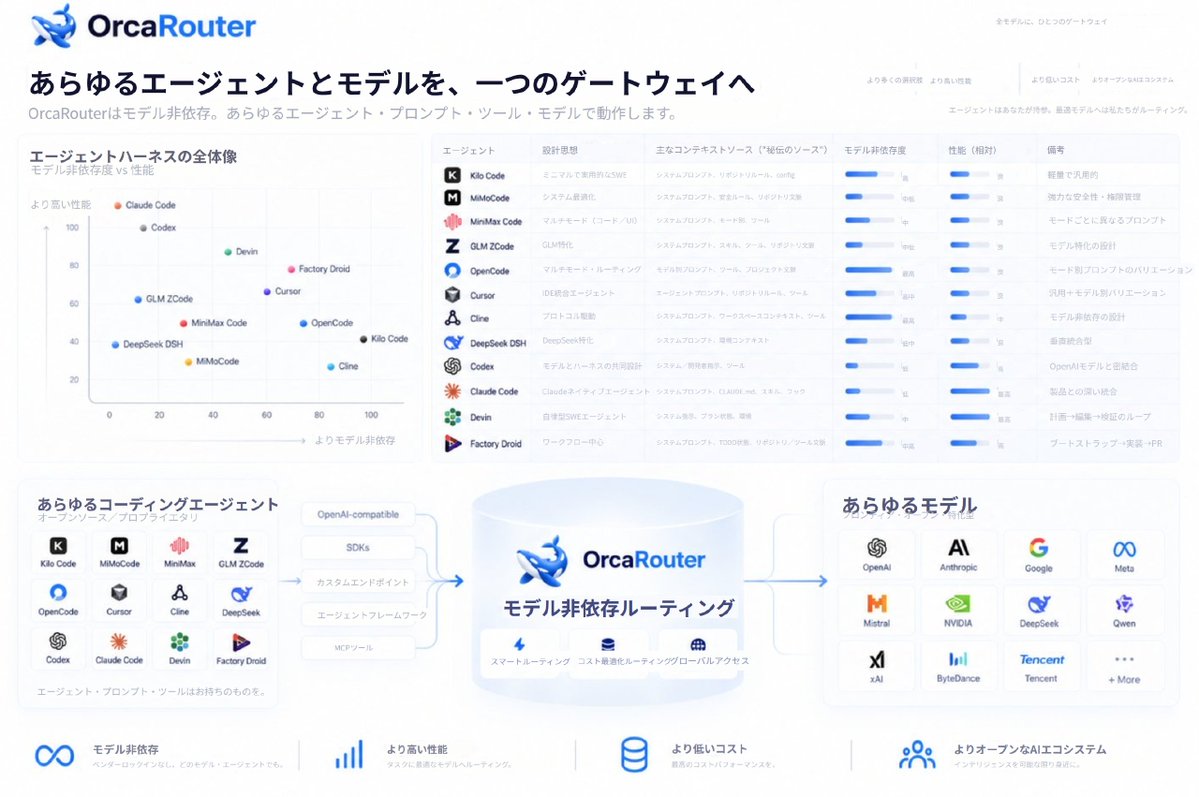
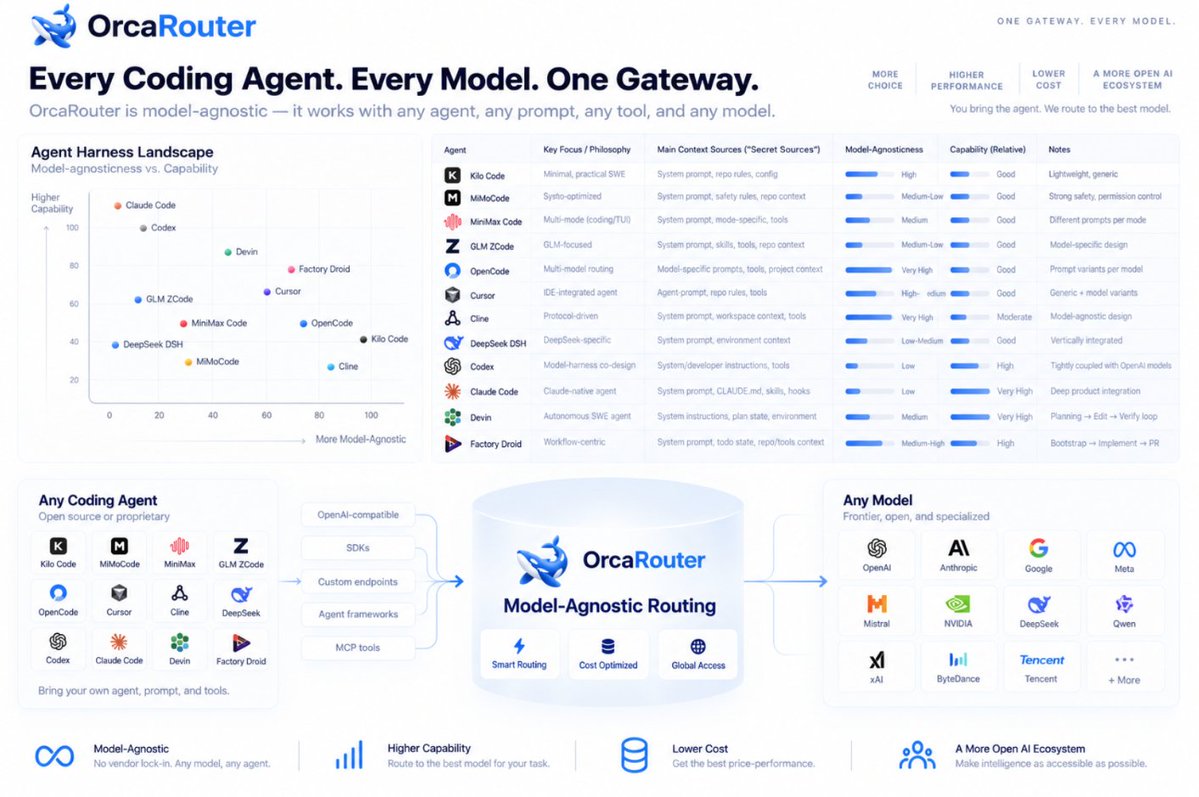
Following our post, we just analyzed and open sourced the system prompts behind 12 open + closed-source coding agent harnesses — Claude Code, Codex, Cursor, Devin, Factory Droid, OpenCode, Cline, Kilo, MiMoCode, MiniMax Code, GLM ZCode & DeepSeek DSH.
We looked at two things:
→ Their “secret sauce”: prompts, tools, memory, skills, rules & agent loops
→ How model-agnostic each harness really is
Full comparison ↓
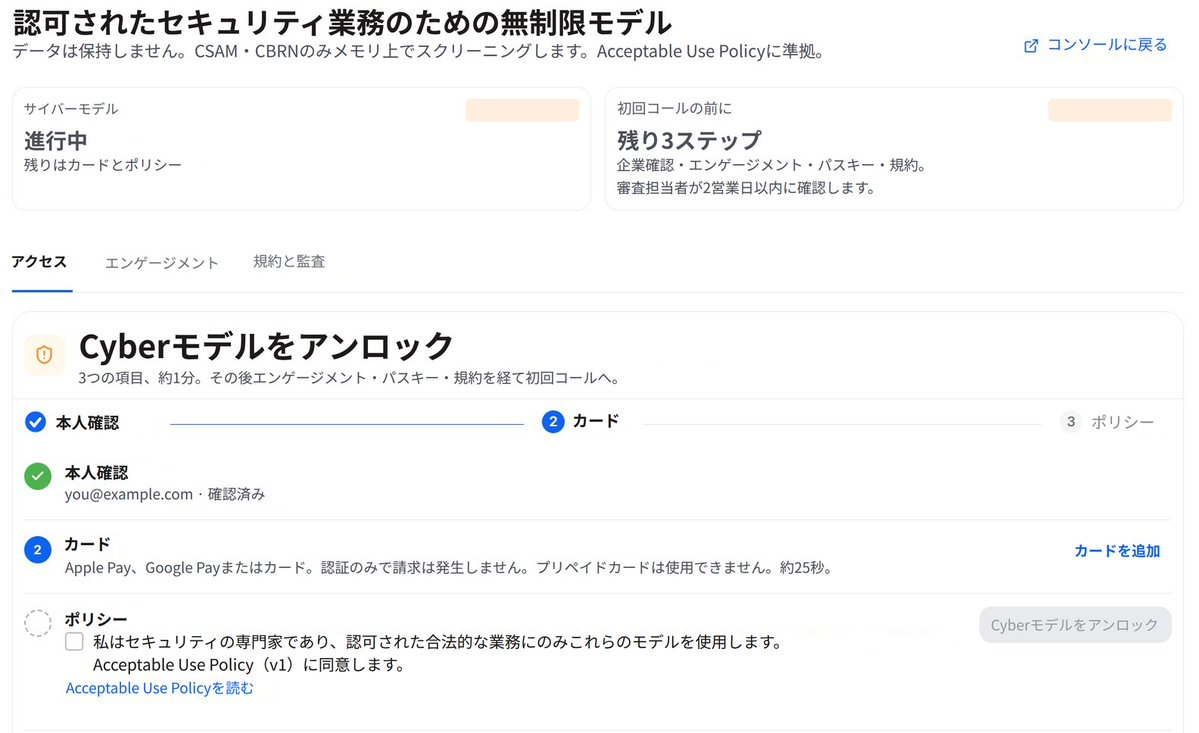
Anthropic just sounded the alarm on GLM-5.3’s cyber capabilities.
We built on it. OrcaCyber Zero 1.0 is based on the GLM-5.3, post-trained specifically for vulnerability research, exploit reproduction, red teaming, and autonomous cyber workflows.
98.01% pass@1 on CyberGym L1.
1,478 / 1,507 real-world vulnerability tasks.
The cyber model race is here.
And open models are moving fast.
Join private testing: https://t.co/9b9T6pORTT
Why are we making AI agents rediscover the same relationships on every query?
Our new paper, IndexRAG, accepted to Findings of AACL-IJCNLP 2026, explores a different approach:
move part of the reasoning to index time.
Instead of retrieving documents and reasoning over them from scratch, IndexRAG precomputes cross-document “bridges” and retrieves them directly.
Results:
→ +4.6 F1 vs. Naive RAG
→ single-pass retrieval
→ one LLM call
The broader idea:
Compute relationships once. Reuse the reasoning forever.
This could matter for enterprise knowledge, research, and eventually large codebases. https://t.co/TSO6axvvQD
Great independent local-model benchmark on an RTX 3090.
OrcaSAQ-2-27B:
• 90.8% MATH-500 — best local result
• 55.0% GPQA-D — best local result
• 89.6% HumanEval+
• 262K context
• ~12 GB footprint (among the smallest)
What matters here is the tradeoff: capability per GB, quantization fidelity, context, and serving behavior.
https://t.co/Lz6Kz87V5E