We’ve all run into the data monster before… slow processes, late insights, bottlenecks everywhere. See how Confluent helps put your data monster to work. Learn more here ➡️ https://t.co/fOexXgGuX7
Got a data monster slowing your business down?
Move from batch to real-time with The World’s Data Streaming Platform. Get the right data. Right where you need it. Right now.
Learn how to put your data monster to work ➡️ https://t.co/T2chu6KoVD
📢📢The #ApacheFlink community is very happy to announce the release of #Flink 1.17, which contains a number of exciting improvements. Please checkout out the release announcement for details.
https://t.co/CCkFvoyaay
Thank all contributors who made this release possible!
👏👏
@1996fanrui@Xintong_Song Because of that I had to change my presentation for the Big Data Technology Warsaw Summit 2023 2h before the scheduled recording 😅
🎉 We’re excited to share our intent to acquire @Immerokcom!
Together, we’ll build a cloud-native service for @apacheflink that delivers the same simplicity, security, & scalability that you expect from Confluent for Kafka.
Learn more → https://t.co/49h9maz1pT
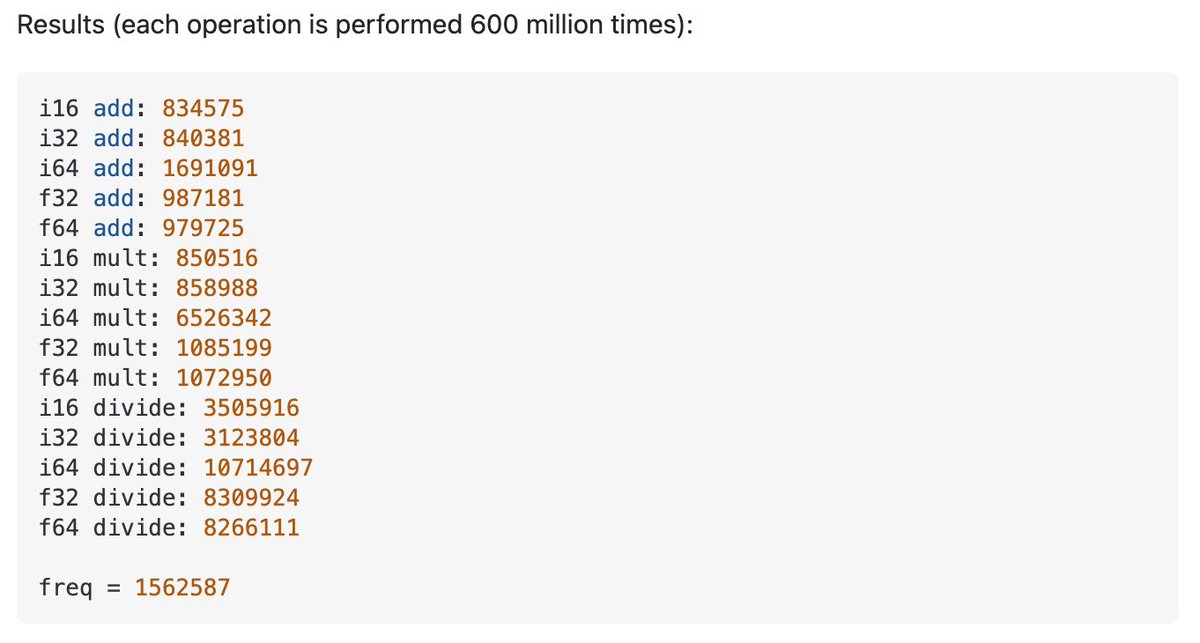
Over and over again I'm forgetting and being surprised how slow 64 bits integers are slow. Multiplication is 6x slower compared to 64 bits floating point numbers! https://t.co/XinilYrbtD
@joemoeAT I’m clearly not keeping up. I know that Instagram it’s that place where you have to share a picture from your every meal. TikTok is that surveillance app, right? But what’s mastodon?
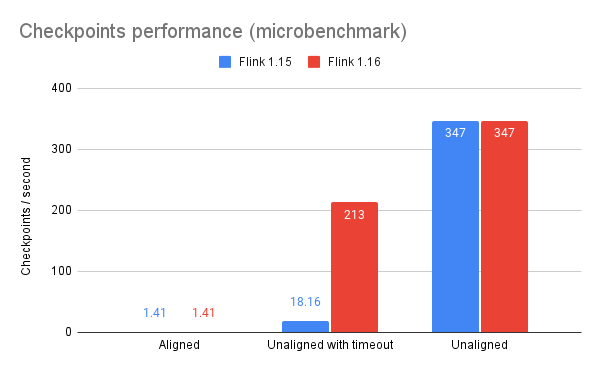
Big thanks to @1996fanrui for the unaligned checkpoints improvements in @ApacheFlink 1.16. I would recommend switching away from the (default) aligned checkpoints to unaligned checkpoints with some timeout.
https://t.co/V3E33Oq6zC
📢The #ApacheFlink community is happy to announce the release of #Flink 1.16, which contains a number of exciting changes. Please checkout out the release announcement for details.
https://t.co/wBIRKXQXuD
Big thanks to the community for all the contributions! 👏👏👏
@GergelyOrosz 🤷♂️it's quite common that big corporations can not capitalise on an opportunity that they have lying in front of them in the plain sight, while smaller companies/startups can. I personally was involved in at least two such situations.
@MarkCallaghanDB Can you elaborate what does it mean
> for read-only + CPU-bound workloads (CPU-bound matters more than read-only)
What if the workload is mixed half reads, half writes, but indeed it's heavily CPU-bound?