Potluck is live.
Run open AI models on hardware you already own. Pair your machines into one private mesh and run models bigger than any single one. Your machines, a trusted circle, or the open pool.
Mac, Windows, Linux. Free → https://t.co/V3gofVIZ52
An example in a draft shouldn’t become company policy.
We’re building Potluck’s Company Brain to preserve dates, conditions and exceptions, cite its sources, and say when something isn’t established.
Company intelligence running on hardware you own.
A useful company answer often needs more than one document.
We fixed a case where Company Brain missed the second source. The updated build passed all 19 questions in our six-document internal test, running locally.
Next: unseen documents and real workflow review.
Building Company Brain on hardware you control.
Our latest local tests check whether answers retain policy conditions and exceptions. Review jobs can now resume interrupted validation without regenerating the answer.
Company Brain progress: inspectable calculations.
Our development build can apply a cited formula, show the inputs and arithmetic, and keep that evidence through review and export.
Tested on our own hardware. Now checking fresh documents before wider use.
@doom_scroller__@truthnotliberal@jun_song Yep, this is a use case for Potluck. We’ve already run one model across two machines, each holding part of the weights. That lets you spread the memory requirements. Thanks for the tag!
Potluck’s updated website is live.
Company AI on infrastructure you control: see the Company Brain preview, use cases and pricing.
Core stays free and open source. Company and Enterprise offerings are in development.
https://t.co/V3gofVJwUA
Next for Potluck: AI that knows your company’s work, runs on infrastructure you control, and improves from reviewed outcomes.
We’re starting with engineering investigations and handoffs.
Interested in helping test this direction? Reply or DM us.
More room for code. Less clutter from error logs.
In development: accurate token budgeting, focused failure feedback and clearer edit recovery for Potluck's local coding agent.
6,606 software tests passing. Next: turn better context into verified fixes on real codebases.
Building toward better local coding agents.
We fixed a model/CLI compatibility issue; 1,156 CLI tests pass.
Fresh coding trials pinpointed our next targets: native tool calls and a separate reasoning budget, leaving room for actual edits.
Work in progress.
Two consumer GPUs. One 27B model.
Our latest placement fix cut an 8-turn Qwen3.8-27B IQ4_XS test through Potluck from 85.6s to 65.4s.
RTX 2080 Ti + RX 6600 XT, over Wi-Fi. All model layers stayed on the GPUs.
Now in main:
https://t.co/VFwjvgEmBY
Potluck research: making local coding more reliable.
More room to finish took our compressed Qwen3-4B prototype from 53/68 to 54/68 correct answers. Mean time: 6.05s → 6.08s.
Small step. Next: stronger checks, targeted repairs, and real repo-edit tests.
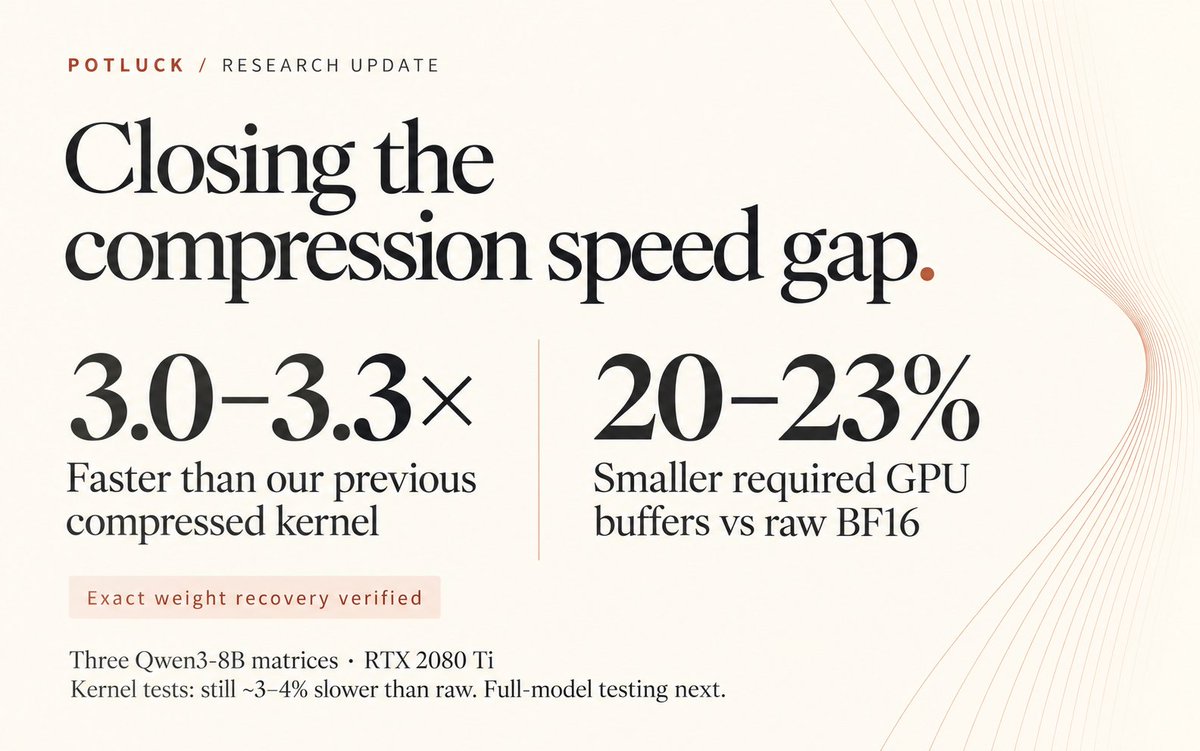
We’re closing the speed gap on Potluck’s lossless compression prototype.
~3× faster than our previous compressed kernel. 20–23% smaller GPU buffers vs raw BF16.
Three matrix tests; still ~3–4% slower than raw. Exact weights recovered.
Next: full-model generation.
We’re working toward more model choice for coding on your own hardware.
First step: experimental llama-server support, with tool calls and cancellation tested locally.
Next: model/hardware qualification and real coding tasks.
In development. Not released yet.