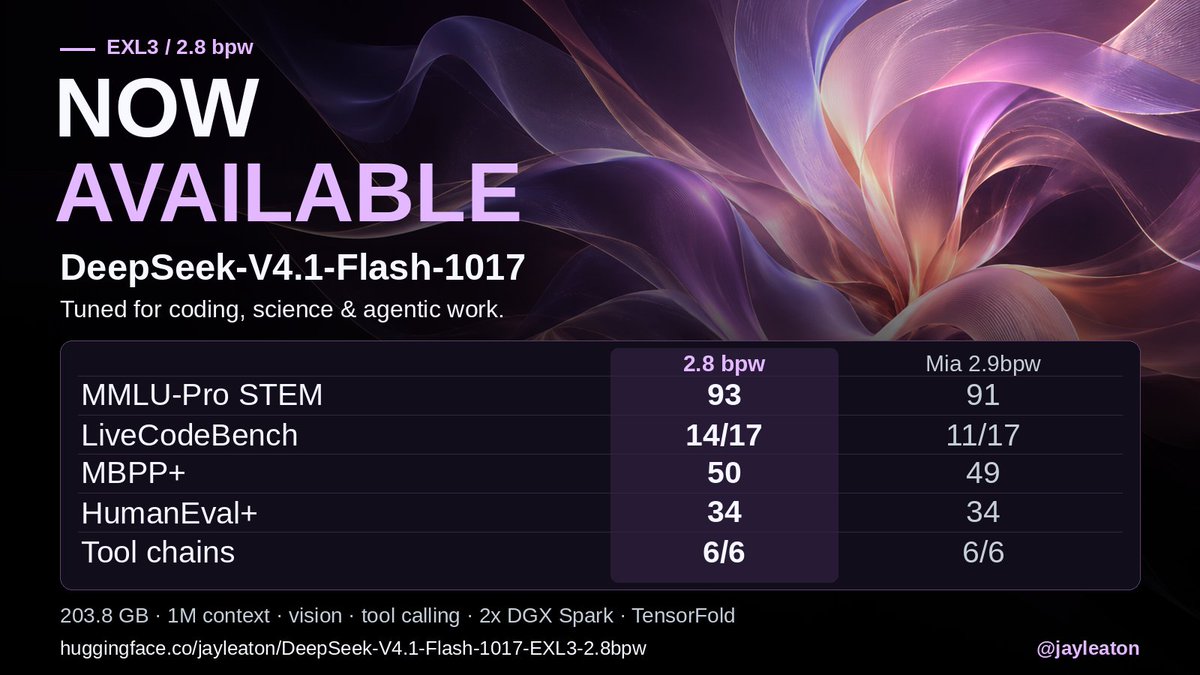
My DeepSeek-V4.1-Flash-1017 quant is NOW LIVE for TP=2 DGX Sparks.
Same 353 questions for all three packs:
new / Mia 2.9 / my old q28-v2
MMLU-Pro STEM: 93 / 91 / 90 (of 100)
LiveCodeBench: 14 / 11 / 11 (of 17)
MBPP+: 50 / 49 / 50 (of 60)
HumanEval+: 34 / 34 / 33 (of 40)
SciCode: 6 / 6 / 5 (of 10)
MATH-500: 36 / 36 / 36 (of 40)
MGSM: 40 / 40 / 40
BFCL tool calls: 39 / 39 / 39 (of 40)
Multi-step tool chains: 6/6, 6/6, 4/6
These are small samples, so I read it as "at least as good, in a smaller pack". It's not a blowout.
The gaps I care about are LiveCodeBench and the tool chains, which my old quant kept dropping. Calibrated it for coding, science and agent work.
Weights/Recipe are in the comments. Recipe has been updated with my current config but is mostly unchanged.
@MiaAI_lab I still don't know how you get them so good. I can't wait to use your Engine Aware Quant (EAQ) system when it's ready.
2.8 BPW, EXL3, 203.8 GB, running on two DGX Sparks with @ashxhart TensorFold.
- 1M context
- image input
- 2.1M-token cache total with NVMe offload.
As usual, if you have any issues, please let me know or submit a PR.
What will you throw at it first?
This was a very good model to use, and I tried to get early access ☹️
Now working on a quant and will have a recipe coming with TensorFold. Please give me a few days.
MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token.
Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym.
Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency.
Hugging Face:
https://t.co/JDYA1zZh54
ModelScope:
https://t.co/DQcmOjTwhO
API: https://t.co/fHRdSV7BwZ
M Plan: https://t.co/LYnYZcsesu
MCode for desktop: https://t.co/SGmLTI3fFU
LocalRouter AI assistant. One DGX Spark. Full duplex.
This actually feels like Jarvis in a box! Built on @ashxhart TensorFold
🧠 Qwen 27B
🗣️ Drama 3 with streaming (Thanks @plotarmordev )
🖼️ Qwen Image Turbo 2.1
🎬 MiniMax H3 video
👂 Whisper STT
~0.5s after I stop talking, it starts with its first word. Interrupt it anytime. Set the delay as you please for responses.
Normal models stay loaded and can be swapped as needed.
Want a video model up? Then Whisper and Drama will make space. Once the video is generated, start voice back up when the video is finished.
The goal is actually fully modular, so consider this a super early version of what it could be. MCP by default, but also ships with a simple UI you can extend as you please.
Thin by design, so everyone can make it their own.
What features do people want next? What about TP=2 or Mac Studio versions?
Quick reminder to store database backups and preferably externally of the core system.
Most people won’t want to pay for snapshots but would you rather lose 95% of your data or pay $20 per month.
Also @lockpickapp can help protect you in the first place.
@daradoescode@boatdotdev I tried it. 60 starts per day isn’t anywhere near enough I hit that in 1 hour and I’m not about to pay another $100+ sub.
Iv instead ported it and built an opensource version i intend to run on a spare pc in my rack.
@LionFMN@ThePrimeagen I think Prime understands how quants work. He is a very smart guy, especially when it comes to math and science.
I just think everyone is oblivious to what local AI can do because they dont want to risk trying.
Here are some of the people that I have learned from over the last few months/years.
This isn't everyone, but it's a great starting point if you are interested in AI, software engineering, or local hardware.
Later, I want to share more underrated people I missed. Please comment anyone you think I can learn from, and I will be sure to follow them! 🙂
Software Engineers (Super technical)
@webdevcody (Super technical in-the-weeds engineer)
@poteto (Unlimited AI usage but very cool skills)
@mattpocockuk (Very technical engineer and architect)
General AI knowledge and amazing tips
@MarkKashef (Amazing skills, tools and workflows)
@MatthewBerman (Very consumer AI tips but no BS)
@BetterStackHQ (More software than AI but some very good lessons)
Local Hardware and AI engines
@0xSero (Pushing local hardware)
@ashxhart (TensorFold)
@RaidOwlTweets (Homelab and networking)
Local AI
@bertholomusai (Very underrated local recipes)
@plotarmordev (Very cool niche models and config)
@MiaAI_lab (The Local AI Goddess)
@JimRatVideo@ashxhart@plotarmordev It's very hard. I have been working on voice agents for a while, but Grokbot basically made my voice app redundant, so I pivoted to this.