Memory is the bottleneck for LLM agents.
Fixed memory pipelines waste compute on irrelevant information while potentially discarding what a specific query actually needs.
This new research introduces BudgetMem, a runtime agent memory framework that extracts memory on-demand with explicit, controllable performance-cost trade-offs.
As agents scale to longer interactions and more complex tasks, memory cost becomes a first-class concern. BudgetMem provides a systematic framework for explicit performance-cost control in runtime agent memory.
Instead of treating memory as a monolithic pipeline, BudgetMem structures extraction into modular stages, each offered in three budget tiers (Low/Mid/High).
A lightweight neural router, trained with reinforcement learning, selects the right tier per module based on the current query and intermediate context.
They study three complementary strategies for realizing budget tiers: implementation tiering (varying method complexity), reasoning tiering (varying inference behavior like direct vs. reflection), and capacity tiering (varying model size).
On LongMemEval with LLaMA-3.3-70B, BudgetMem-CAP achieves a Judge score of 60.50, surpassing the strongest baseline LightMem (48.51) by a wide margin. On HotpotQA with Qwen3-Next-80B, BudgetMem-CAP scores 72.08 at just $0.22 cost, while BudgetMem-REA reaches 70.83 at an even lower $0.17. The trained router also transfers across model backbones without retraining.
The analysis reveals that implementation and capacity tiering span broader cost ranges for exploring budget extremes, while reasoning tiering acts as a fine-grained quality knob within a tighter cost band.
Paper: https://t.co/qkKmawVNrk
Learn to build effective AI agents in our academy: https://t.co/LRnpZN7deE
🧠 Introducing BudgetMem: Runtime Agent Memory with explicit performance–cost control.
Runtime memory utilization is powerful but often expensive, and most systems offer little control beyond fixed pipelines.
BudgetMem turns memory extraction into budget-tier routing across modular memory operations, so you can trade off quality vs cost on demand.
📄 Paper: https://t.co/zKR1GjqvwD
💻 Code: https://t.co/mf0JxPdqSS
#LLM #Agents #AgentMemory #LongContext #ReinforcementLearning #EfficientAI
@dair_ai Thanks for sharing our work! For readers interested in self-evolving agent memory, our another project MemSkill may be of interest: https://t.co/GGswfWw3D7
and https://t.co/8PDl9SE9I5
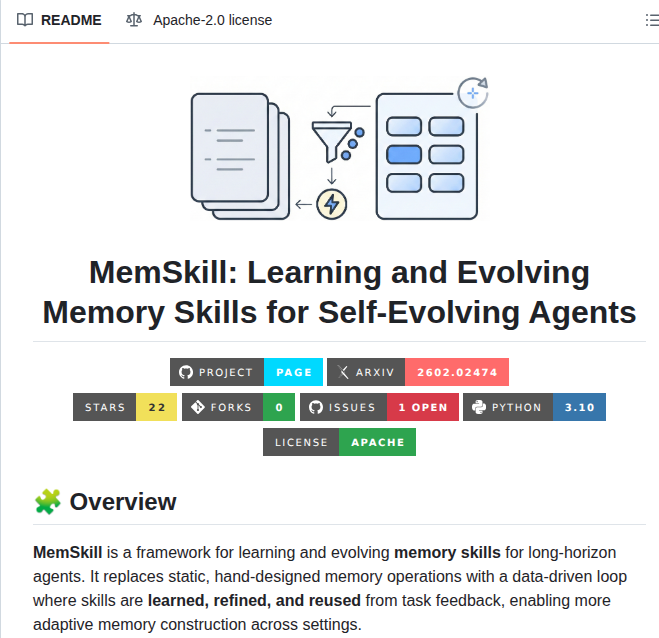
📚 Introducing MemSkill, turning static memory pipelines into a trainable, upgradable capability for more reliable long-horizon agents.
❓Handcrafted memory operations are often brittle and hard to scale.
✨Inspired by agent skills, we rethink memory construction as skill-conditioned generation over an evolving skill bank, learning skill selection with RL and evolving skills from failures over time.
📄 Paper: https://t.co/4TvdeSi39n
💻 Code: https://t.co/GcZ8a9AvaO
#LLM #Agents #AgentMemory #AgentSkill #ClaudeSkills #ReinforcementLearning
Excited to share that I'll be hosting some of the world's best AI researchers and engineers for our @GoogleDeepMind Gemini event next week in Singapore 🇸🇬!
Join @JeffDean, @quocleix, @benoitschilling, @melvinjohnsonp and @denny_zhou for a day of technical conversations, panels and talks about AI, reasoning and our mission to build a world class AI frontier lab in Singapore.
If you're in town and would like to attend, please check the RSVP link below👇. Note, subject to capacity constraints and you'll need to be approved to join.
🚀 Excited to present our paper “Reinforcing Compositional Retrieval: Retrieving Step-by-Step for Composing Informative Contexts” at #ACL2025!
How can we construct an informative set of context examples for LLMs?
We propose a tri-encoder retriever + RL framework for compositional, step-by-step retrieval — tailored for tasks that require multiple examples.
📍 Hall 4/5, Session 10: IP-Posters
🗓️ Tuesday, July 29
🕓 16:00–17:30
📄 Paper: https://t.co/nRZPjPg7U7
💻 Code: https://t.co/x73VLTKSDE
#ACL2025 #LLMs #ReinforcementLearning #Retrieval
Reinforcing Compositional Retrieval: Retrieving Step-by-Step for Composing Informative Contexts
@QuanyuLoong et al. present a tri-encoder sequential retriever that models retrieval as a Markov Decision Process.
📝https://t.co/aUQe6YcuvL
👨🏽💻https://t.co/xgSS931NW9
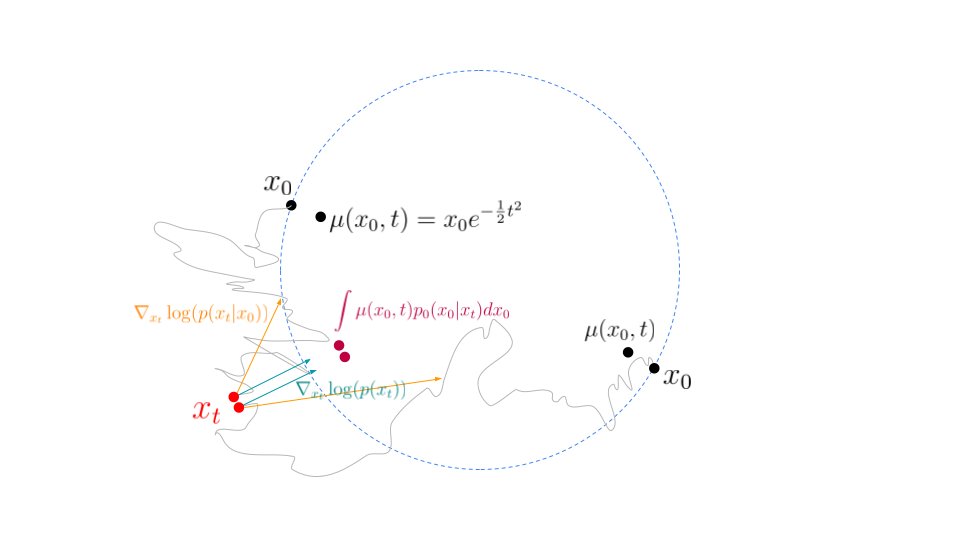
Diffusion Without Tears is our attempt to make the score-matching + SDE interpretation of diffusion geometrically intuitive. If you're interested in our upcoming interview with @DrYangSong, I recommend reading this first! Link below.
Excited to announce that I've officially joined @AlibabaGroup to lead the AI team for the AI-to-Consumer business group. There are massive amounts of opportunities in developing foundation models and AI Agents applications for consumer markets in the coming decade!!
DeepSeek-R1 is very hot, but the idea of LLM+RL framework is not entirely novel. In 2022, my Salesforce AI team was among the pioneers to propose the LLM + RL framework for joint training and inference, which was a couple years earlier than OpenAI O1 and DeepSeek-R1 works. We published a NeurIPS paper called CodeRL (https://t.co/Oc0zTIoBuk) that achieved open-source SOTA in code generation with less than 1B code LLM model (beating 10x larger models). Our idea was to apply the similar principles and methodologies of AlphaGo/AlphaZero to train and improve LLM in a self-play/self-taught manner, but the base LLM model size & performance was not strong enough (ChatGPT was not yet released).
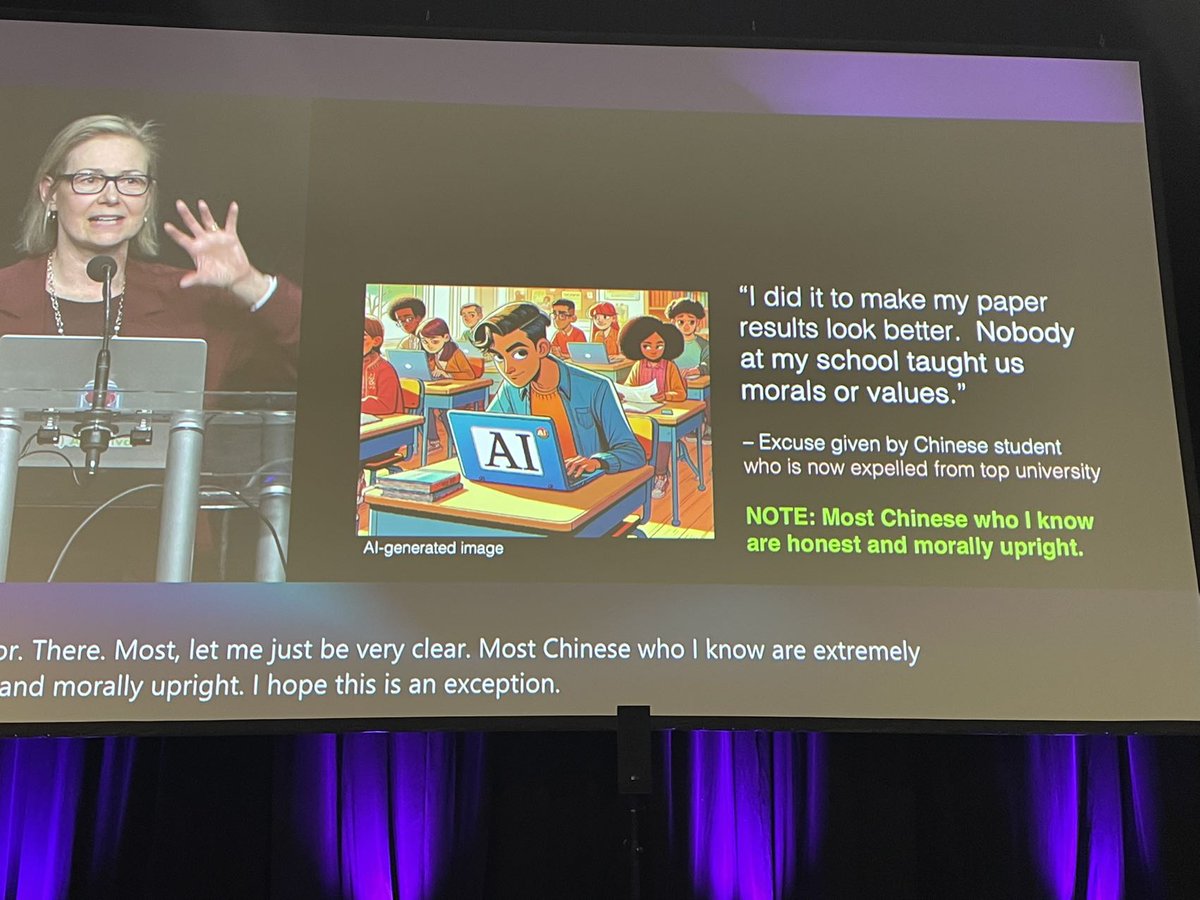
Mitigating racial bias from LLMs is a lot easier than removing it from humans!
Can’t believe this happened at the best AI conference @NeurIPSConf
We have ethical reviews for authors, but missed it for invited speakers? 😡
NeurIPS acknowledges that the cultural generalization made by the keynote speaker today reinforces implicit biases by making generalisations about Chinese scholars. This is not what NeurIPS stands for. NeurIPS is dedicated to being a safe space for all of us. We want to address the comment made during the invited talk this afternoon, as it is something that NeurIPS does not condone and it doesn't align with our code of conduct. We are addressing this issue with the speaker directly.
NeurIPS is dedicated to being a diverse and inclusive place where everyone is treated equally.
I'm shocked to see racism happening in academia again, at the best AI conference @NeurIPSConf. Targeting specific ethnic groups to describe misconduct is inappropriate and unacceptable. @NeurIPSConf must take a stand. We call on Rosalind Picard @MIT@medialab to retract and apologize for her statement.
today we are announcing reinforcement finetuning, which makes it really easy to create expert models in specific domains with very little training data.
livestream going now: https://t.co/ABHFV8NiKc
alpha program starting now, launching publicly in q1
Excited to share our paper "Not All Tokens Are What You Need for Pretraining" received the #NeurIPS2024 Best Paper Runner-up award. I’ll be attending the conference from Wed to Sat. Feel free to reach out if you'd like to connect or attend our talk.
https://t.co/81YTbRoppy