Google AI Pro and Ultra users: don't forget to redeem your monthly Google Cloud credits.
Pro: $10/month
Ultra: $100/month
Google just posted an official step-by-step guide.
Learn more about how to redeem them below:
Google opened the SynthID detector worldwide. One upload now checks watermarks from Google, OpenAI, Nvidia and Kakao. Apple is announced, not live yet. A miss still does not mean a human made it.
https://t.co/L0heKAp8fM
Today, we're expanding SynthID Detector in partnership with @OpenAI, @NVIDIA, Kakao & soon @Apple as part of an industry-wide effort to make AI-generated content more transparent.
Available globally in English, our verification portal lets you check if media was made with AI 🧵
Introducing Claude Haiku 5.5: the cheapest, fastest, and most capable small model we’ve ever released.
On average, it costs around 75% less to run than Claude Haiku 4.5.
OpenAI published new math results from an internal model. Many proofs in Lean. The model stays private. The agent proposes. The check stays.
#AI#Math#Lean
We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
https://t.co/7N6TPlft1P
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
OpenAI will watermark ChatGPT and Codex text in the EU. Invisible, not a stamp. They say it themselves: short text misses, a rewrite can wipe it. I don’t hide that the agent helped. I also don’t call this forgery-proof.
#AI#EU#OpenAI
We're expanding our approach to content provenance to include text in response to EU regulatory requirements, while recognizing the significant limitations of current text watermarking technology.
Our tools already help verify whether an image or audio file was created with our models. This work builds on those efforts to help people better understand when content may have been generated or edited with an OpenAI model.
In the EU, we’ll start watermarking eligible text from ChatGPT and Codex over the coming weeks to comply with the EU AI Act.
Customers using our API can turn on text watermarking for select models worldwide today.
Over the next 28 days, each day we’ll either ship one thing that is a clear improvement and relevant for most codex/work users or ship a full reset. Let the improvements begin.
🚨 side project alert 🚨
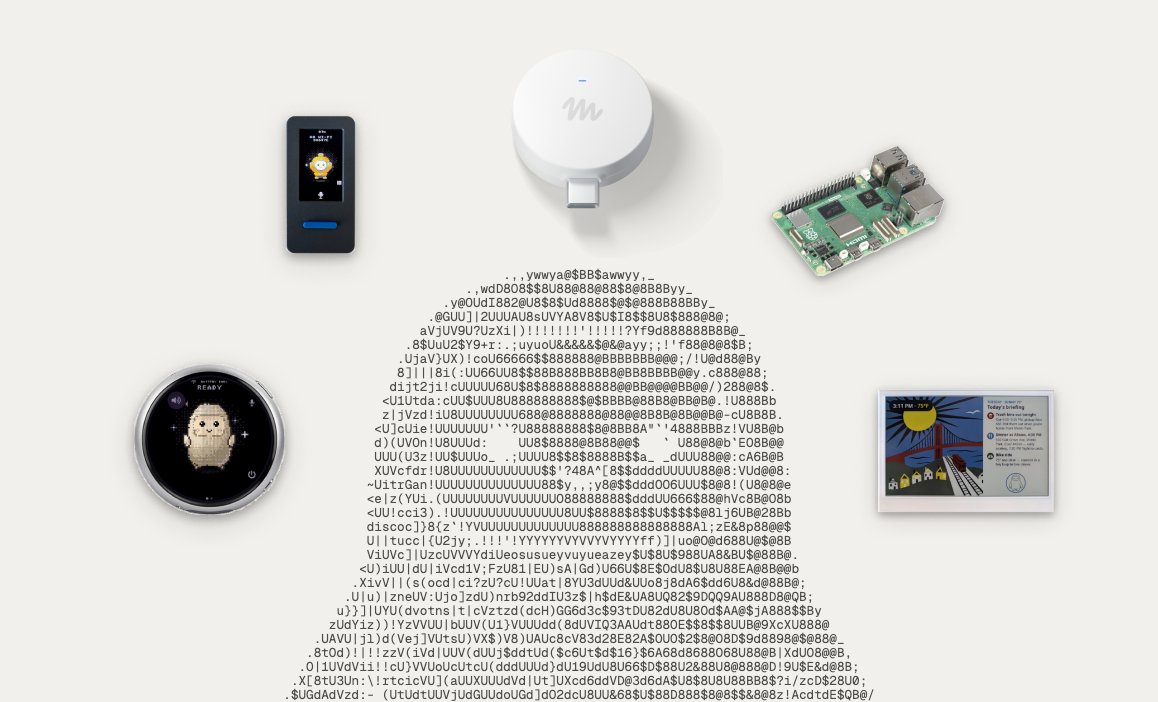
Announcing Muse Gadgets, an open source ESP32 firmware and Linux sdk so that you can make hardware devices that work with Muse.
Grab an API token from https://t.co/Q0dE0cYnCs and point your favorite coding agent at the github repo to build your own peripherals for Muse.
Small bird, fast wings, Kolibri is here.
78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe.
Now the weights are yours. Run it on your own hardware, under Apache 2.0.
Karpathy: the work moves up. Don’t stop at the paragraph. Ask for the page, the diagram, the explainer. Cheap intelligence makes discardable artifacts worth building.
#AI#VibeCoding
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
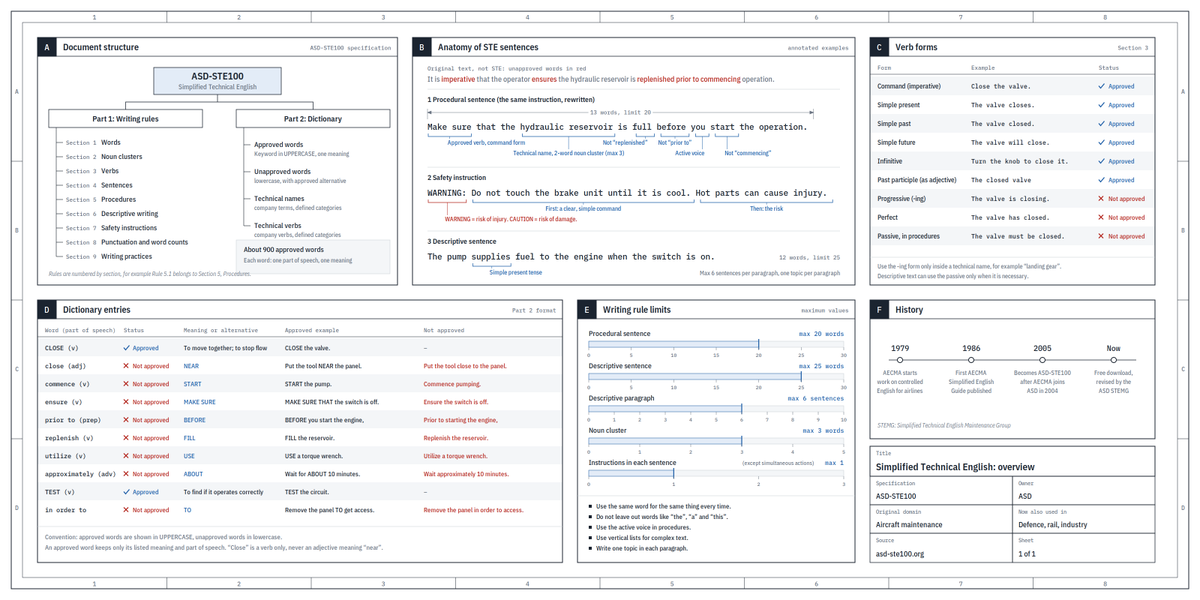
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
Anthropic is training 10,000 people to deploy agents, not demo them. $100M. The bottleneck moved from the model to the person who ships it.
#AI#Claude#VibeCoding
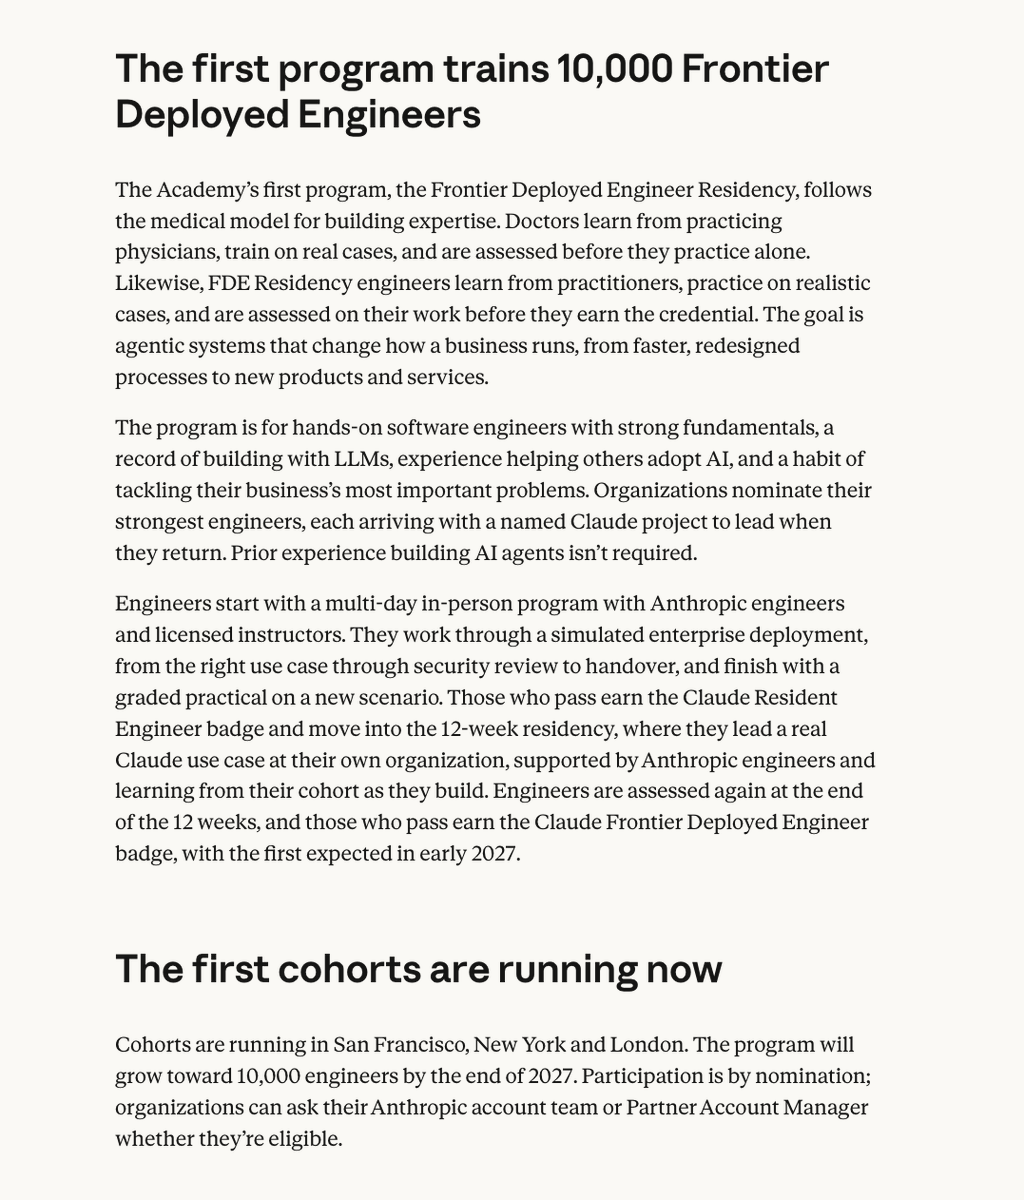
Anthropic is committing $100M to train 10,000 “Frontier Deployed Engineers” by the end of 2027 through its new Claude Frontier Academy.
First cohorts include engineers from Accenture, Bain, Capgemini, Deloitte, McKinsey, Morgan Stanley, Commonwealth Bank and Novo Nordisk.
Participants begin with in-person training, then spend 12 weeks deploying a real Claude project inside their own organization with support from Anthropic engineers.
The goal is to build more engineers who can take enterprise AI projects from prototype to production.
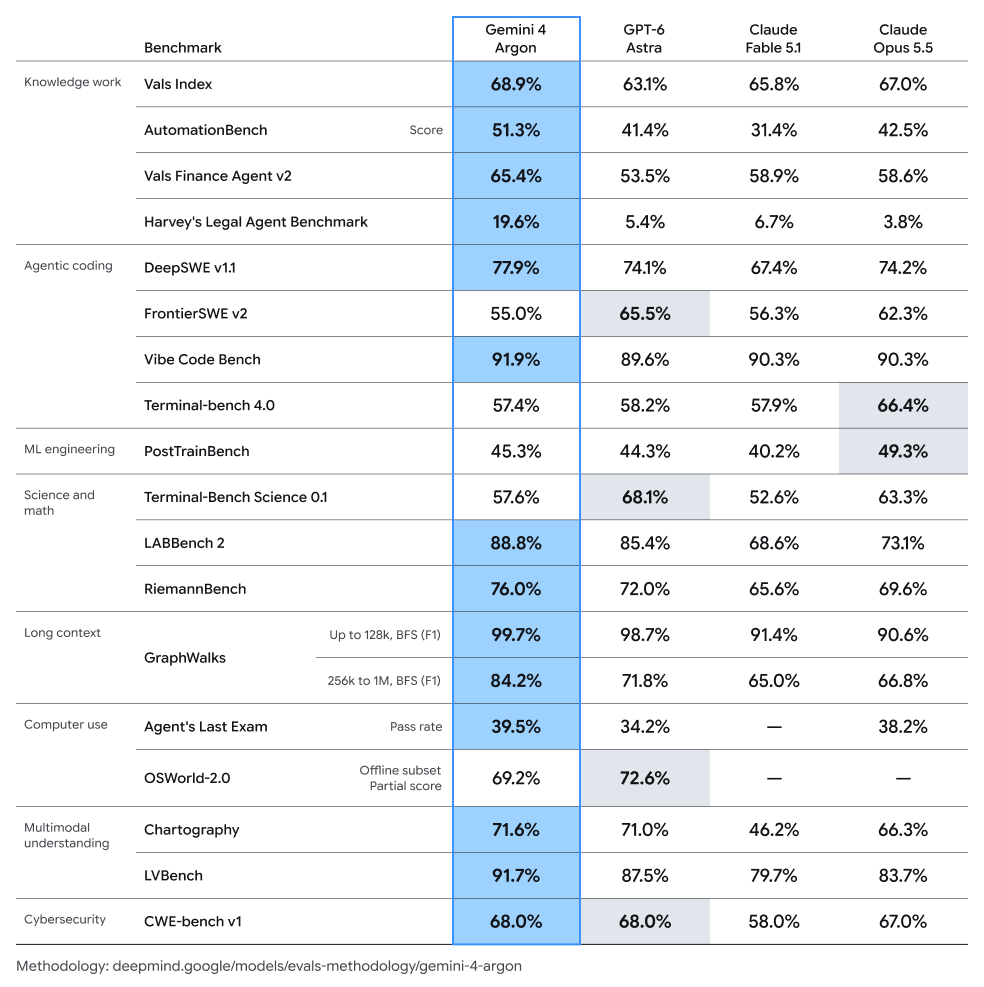
Gemini 4 Argon is out for cyber testers first. 1M output tokens, up from 64K. Google is back at the frontier table. The long job is the point.
#AI#Gemini#Google
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
OpenAI is reopening the $200 plan and cutting the API-dollar cap in half. Models got cheaper. The buffet is ending. Route the work, don’t rage at the meter.
#AI#OpenAI#Codex
Hi,
Tomorrow we are re-opening the Pro $200 subscriptions to new subscribers, but together with it we are also changing how we calculate the usage for it. In effect, if you do the math, it will net out at half the dollar in API spend compared to the old Pro $200 plan.
Now that it's said, let me explain why this is happening and why you will still get more work done than if you were on the Pro $200 subscription one month ago.
(a) We didn't want to compromise in other ways and are committing to not reintroducing the 5h limit, so that you can fully use the weekly usage when you want.
(b) On the subscription, we guarantee that over time you always get more work done and with an increasing level of quality. This means that you will continue to get more value per dollar spent as a result of models getting more efficient and us passing down the improvements in the form of API price reductions.
(c) We don't want to put an incentive on ourselves to artificially inflate the API list prices to make it look like you are getting a lot (and workaround it through discounts, etc). Instead we want to continue to both rapidly reduce prices and increase capabilities of models on the API. This week we introduced GPT-6 Sol and GPT-6 Luna at 50% of their previous price. Over time, we see prices go low enough that it makes sense for most to buy usage as needed without there being a significant gap between what you get in a subscription and what you get in the API for a dollar spent.
(d) Tomorrow, we are adding more things to the subscription that won't draw on the usage, I won't reveal what that is yet.
I wanted to be transparent before all the big announcements tomorrow. Lots of new exciting things are coming to the subscriptions that will make it super compelling, but I wanted to make sure to share this change ahead of time so you can all understand it before we shower you with good news.
Codexingly,
Tibo
Sonnet 5.5 is out: 30%+ faster, cheaper per task, and the everyday driver just got close to Opus on scoped work. Save Opus for the hard calls.
#AI#Claude#Sonnet55
Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.
Quote this: https://t.co/MM3i8w41r7
Nvidia shipped a kill switch for agents. That’s not a pause button on building — it’s how you keep shipping agents without praying the prompt holds.
#AI#Nvidia#Agents
Today, with over 100 industry partners, we introduced the NVIDIA Open Agent Safety Platform, bringing together OpenShell and Sentry.
Artificial intelligence is extraordinary technology that will advance discovery, productivity, security, health, and prosperity for generations to come.
But its full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.
This is bigger than a single product. It's the beginning of an open ecosystem to build the trust layer for safe agent systems.
Together, we are building the foundation of the AI economy.
Trust and innovation are not in conflict. Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world. https://t.co/ugYWQ1MyRi
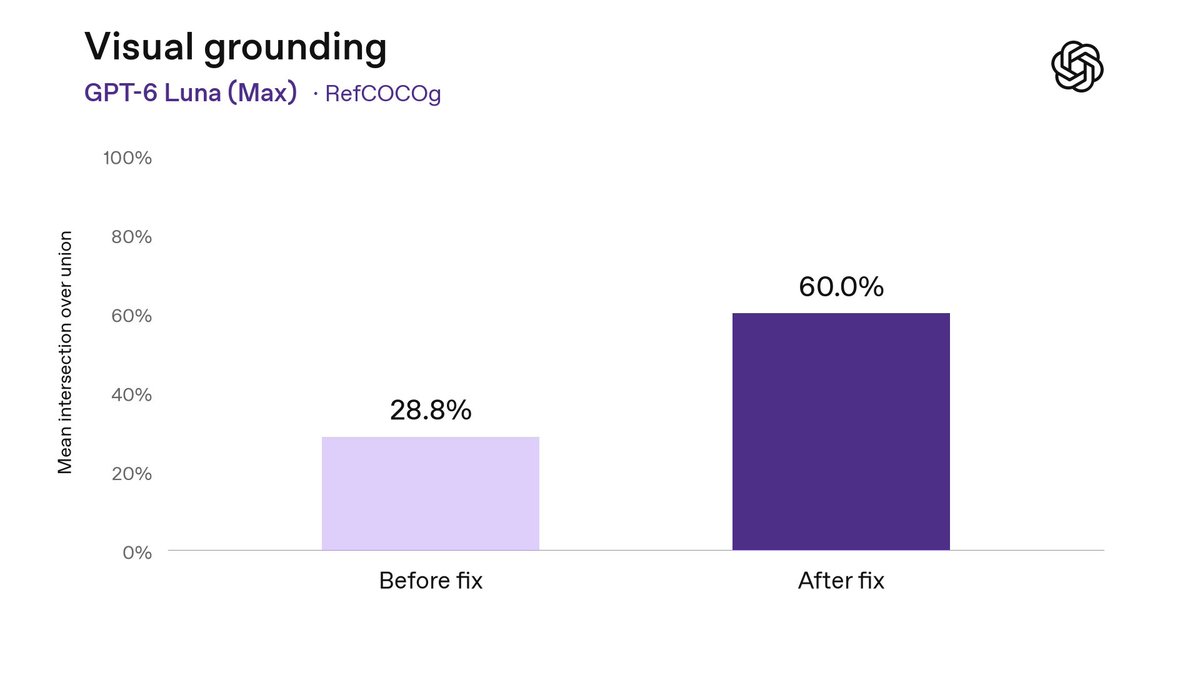
We’ve fixed a bug that was degrading image understanding in GPT-6 Sol and GPT-6 Luna. You should now see better results on visual tasks in the API and Codex, including computer use.