wonderful to see everything about AI is accelerating,
Bloomberg just reported Baseten is set to raise about $2B at valuations up to $30B, more than doubling its June valuation.
Inferencing demand has moved fast, with Baseten��s annualized revenue reportedly tripling from $200M to $600M in the first quarter of 2026.
A $30B price, about 50 times that reported run rate, assumes inference spending keeps outgrowing training as agents burn more compute per task.
Its closest rival, Fireworks AI, raised $1.5B at a $17.5B valuation in July.
Excited to announce our collaboration with @Supermicro, the perfect partner to build and support inference racks powered by SambaNova SN50.
Our racks join Supermicro's Data Center Building Block Solutions portfolio. They fit the air-cooled data centers customers already run, next to the GPUs they already own. This first batch of SN50s is only phase one. Pumped for what comes next!
https://t.co/qTNaF3F3vF
Thank you @ClayMagouyrk for the shoutout at the Oracle AI World stage this morning!
We’re proud to bring fast, high-performance AI inference to @Oracle Cloud Infrastructure (OCI).
More on our partnership below ⬇️
LIVE from Oracle AI World!
SambaNova and @Oracle are collaborating to bring high-performance inference to Oracle Cloud Infrastructure (OCI).
“Our customers want the right infrastructure for every AI workload, and inference demand is growing fast. We plan to bring SambaNova’s RDU chips to OCI to give AI builders a high-performance, efficient way to run models at scale.” — @MThiagarajan_, President, OCI.
Full press release here: https://t.co/BEACDBXDwL
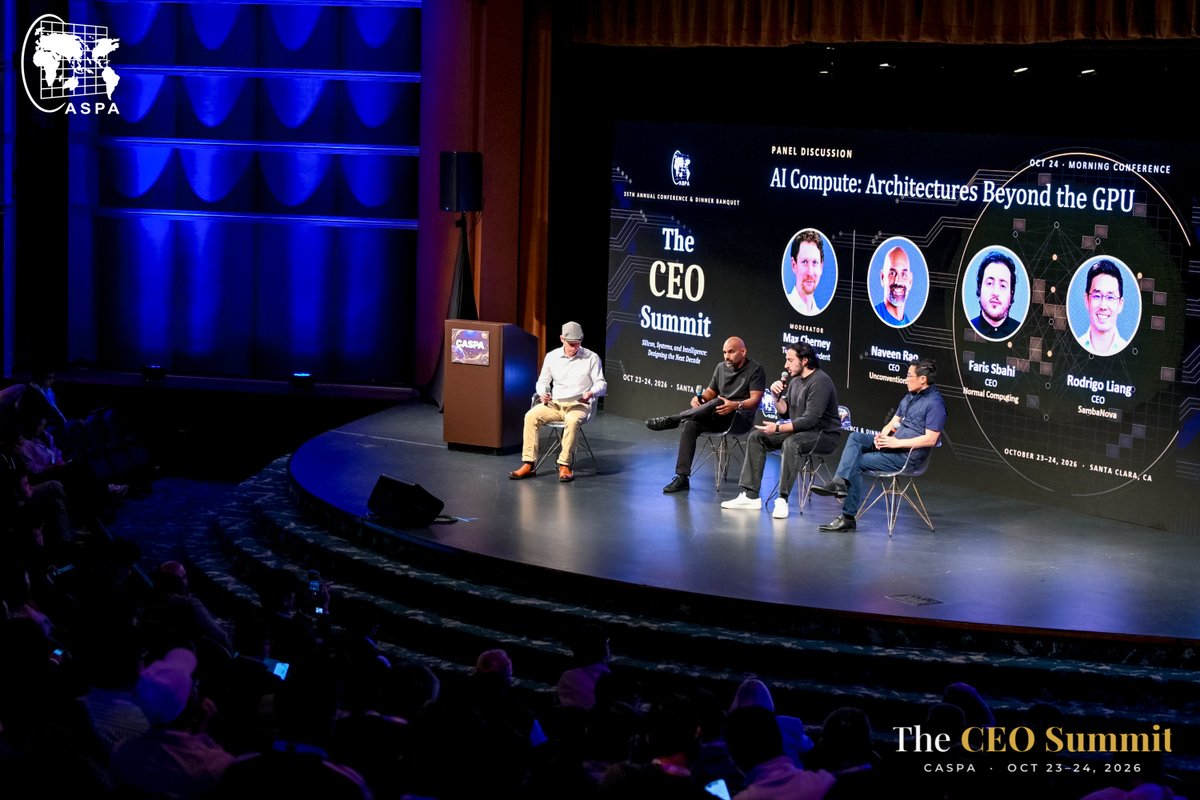
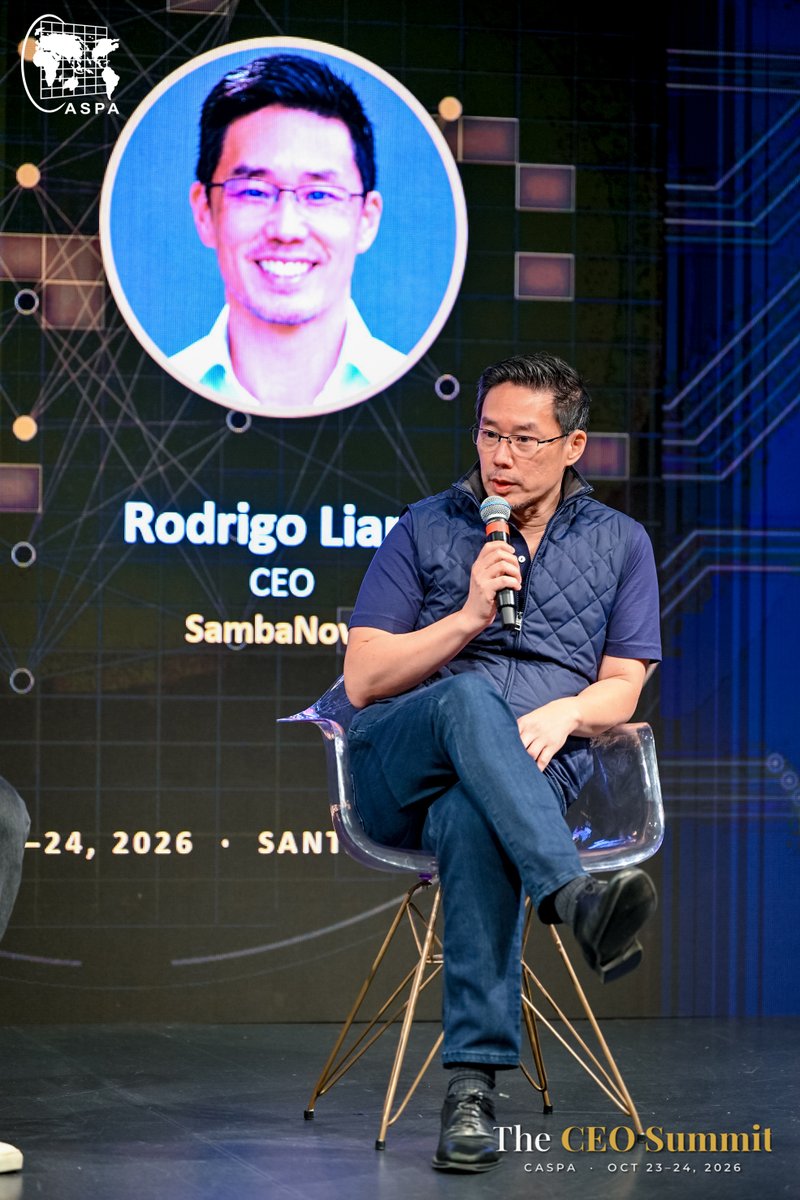
Some snaps from the weekend at CASPA!
@RodrigoLiang joined fellow CEOs @NaveenGRao, @unconvAI & @FarisSbahi, @NormalComputing for a panel moderated by @chernandburn, @Reuters. It was an incredible weekend full of insights from some of the most brilliant leaders of the world. Thanks to the CASPA team for bringing everyone together!
One big takeaway from @hotchipsorg: agents are changing the inference game.
More reasoning + more tool calls = a LOT more tokens. And across six frontier-model configs, decode made up 75–97% of inference time.
So bandwidth & data movement matter. A fast chip is great. A fast system is better.
Read the recap: https://t.co/p0B6uExvVX
Our mixer after this week's Hot Chips was a good time, so we're doing it again!
After AI Infra Summit, swing by the Hyatt Regency Santa Clara so you can meet the team, grab drinks, enjoy some food, and learn more about our open roles.
September 15 | 6–9 PM
Register here: https://t.co/ARdmTp1jMX
As models get smarter and agentic workloads get more demanding, users expect both intelligence and speed.
That’s why inference speed is becoming part of the AI experience, not just an infrastructure metric.
Premium inference is here. ⚡
More in our blog: https://t.co/l5btqlOrKm
Our squad just keeps getting stronger. 🦾 @mmoazami is joining SambaNova as Vice Chair of Global Strategy & Partnerships, reporting to @RodrigoLiang.
Mohsen has supported some of the world's hottest technology companies, enabling global expansion, forging strategic relationships, and navigating major industry shifts.
Welcome to SambaNova, Mohsen!
https://t.co/zvUwUw6heG
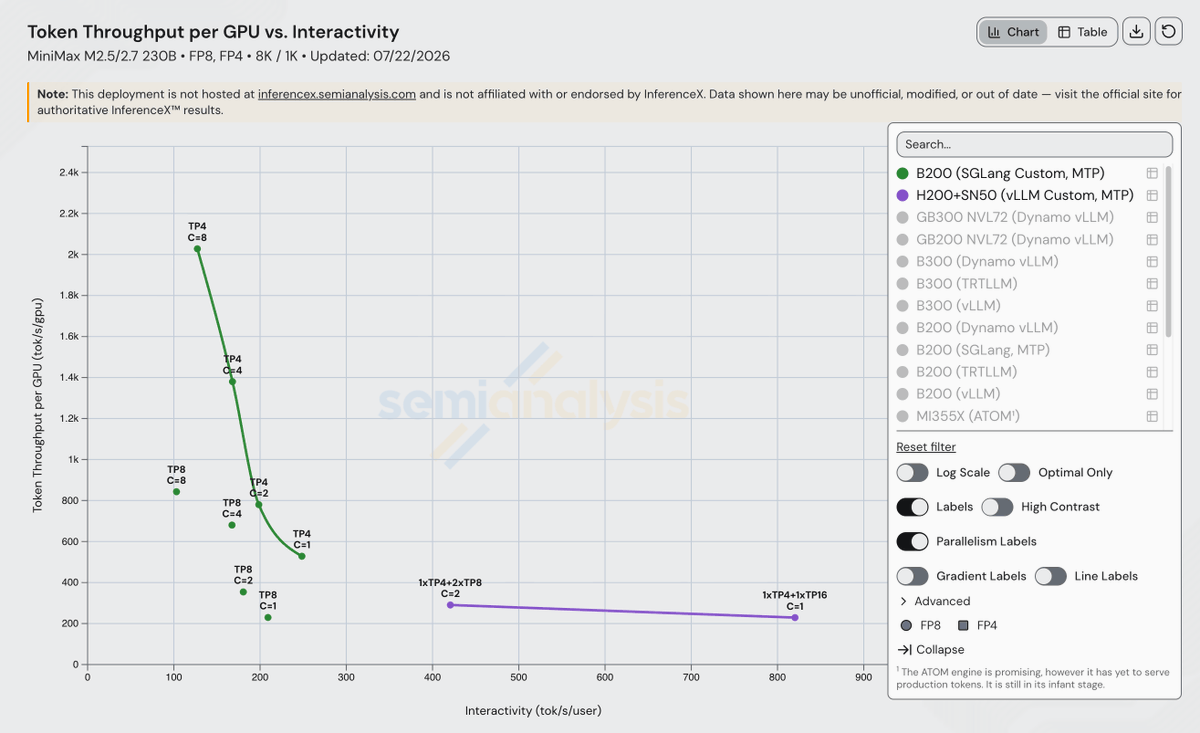
@dylan522p and the @SemiAnalysis_ team benchmarked the SN50 RDU running @MiniMax_AI M2.7 and the results confirm we’re over 3x faster decode than GPUs.
I'm so proud of the team. Third-party validation from SemiAnalysis is the highest stamp of approval!
Third-party verified by @SemiAnalysis_ ... speed you can REALLY see. ⚡️
@dylan522p and team have independently benchmarked the SN50 RDU running @MiniMax_AI M2.7. The results? Over 3x faster than GPUs.
Premium inference keeps getting faster and we’re the FASTEST! See for yourself.
Read the blog here: https://t.co/1sFrHkCxFu
“How do we solve the scaling problems as AI becomes a global problem?” — @RodrigoLiang
Thank you to @JonFortt for having our CEO on @CNBC Fortt Knox to discuss why enterprises are bringing AI on-prem and why we're the only proven premium AI chip inference.
We appreciate the chance to share our mission! 🚀
https://t.co/qrCkQcaxuE
My latest Bloomberg Interview, where I talked about AI technologies coming from China, including Kimi K3, and https://t.co/tq9WCFxkLe's TrueNorth and Boss AI. https://t.co/KCsQt12418
Great to see so many companies get behind open weights. Open models widen access, force competition, and let organizations own what they build instead of renting it back forever. Next comes performance: full precision, fast, at scale. The whole ecosystem gets stronger for it.
For my first post, I’m sharing a letter @NVIDIA signed on why open models matter.
AI will transform every industry, power every company, and be built by every country.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty.
The world needs both frontier closed models and frontier open models.
https://t.co/AUKzoQ5Ikb
AI training made GPUs the standard. AI inference is changing the equation. As Abhi shared with @FierceNetwork, minimizing data movement is the key to faster, more efficient inference—and our RDUs are purpose-built to deliver enterprise AI without requiring entirely new data centers.
Thanks to @DiaMariesbeat for the coverage!
https://t.co/PtgkxbqWYL
Same prompt. Same model. Two stacks.
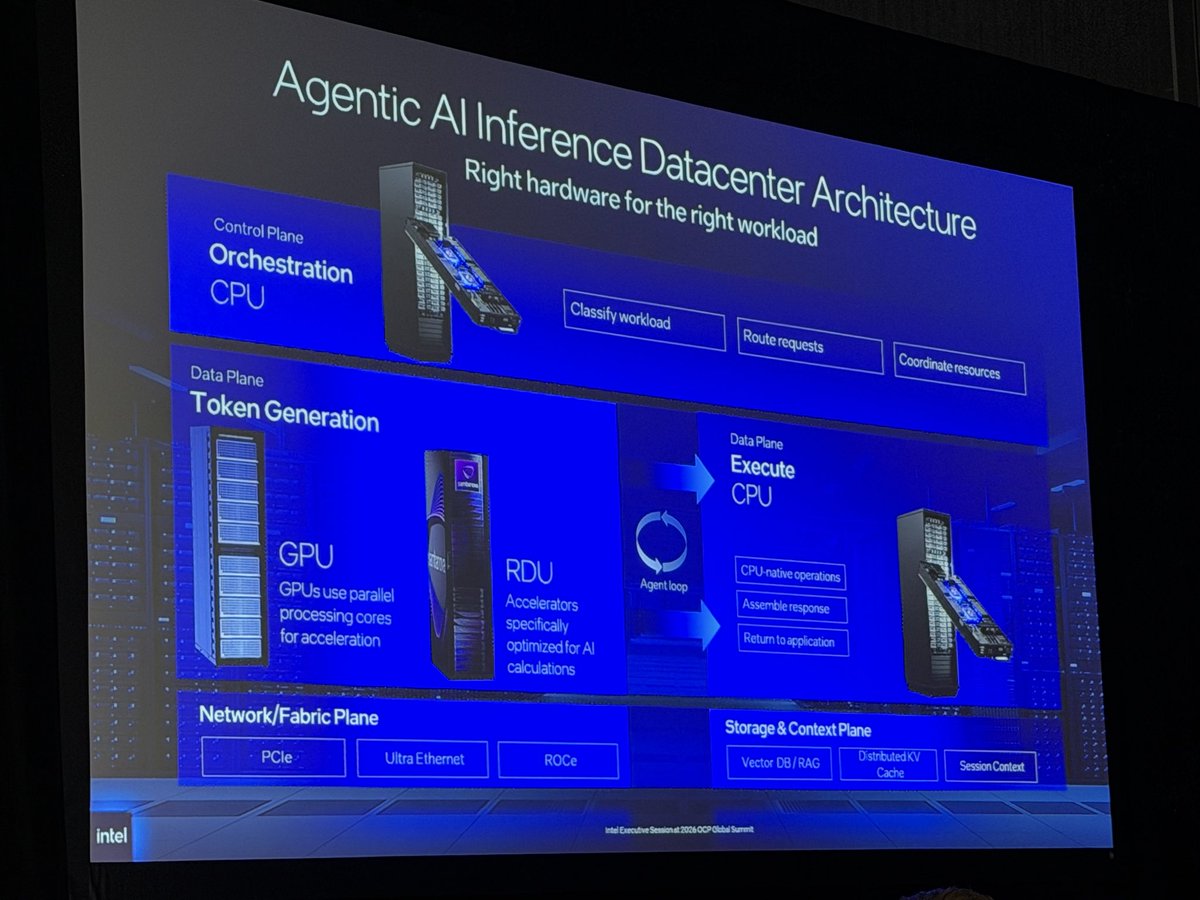
At #Computex, we demonstrated disaggregated inference live: GPUs handling prefill, SambaNova RDUs handling decode, and CPUs orchestrating agent execution.
The result? Up to 2X the speed of B200-only configurations 🦾
What actually happens during AI inference?
This video breaks down how RDUs, memory architecture, and multi-level parallelism work together to generate thousands of tokens in parallel across racks.
Built for scalable, real-world AI inference 🦾
Learn more: https://t.co/uo77Ere4ub