This year we managed to do the impossible. We launched the AI research department, and we launched it noticeably – with recognition from the world's leading AI conferences: ICML and NeurIPS (both spotlights). But I want to believe that this is just the beginning...
1/7 In-context learning (ICL) is poised to revolutionise NLP, but its success hinges on our ability to process long sequences. Recently, @simran_s_arora et al. showcased advancements in Linear Transformers and proposed Based. But what if we could push its boundaries further?
Our first stable release and full paper preprint for XLand-MiniGrid is done, check it out! Compared to the workshop version, we have significantly redesigned the library, multi-GPU baselines and standardized benchmarks with millions of unique tasks.
https://t.co/yvX36P4U0f
In-Context RL for Variable Action Spaces
ICRL is a promising direction to build Foundational Decision-Making Models. But adaptation to new action spaces is a problem.
We propose Headless Algorithm Distillation (@MishaLaskin) to address it.
https://t.co/Alzyu1HwXm
Which data-collection strategies enable In-Context Reinforcement Learning?
You need either RL training trajectories or supervision with optimal actions. But what if we had a demonstrator policy, could we use it to enable ICRL? We show the answer is yes
https://t.co/nMiVS971uB
🔥 Imagine if you could train Meta-RL agents for 1 TRILLION transitions under 40 hours?
We present XLand-MiniGrid — JAX-accelerated meta-reinforcement learning environments inspired by XLand (@FeryalMP) and MiniGrid (@Love2Code).
code: https://t.co/Wuvm8yw0OA
@kchonyc Curious about hyperparameters' impact in large-scale benchmarks? Check out our paper "Clean Offline Reinforcement Learning"! Fully open source, waiting for your ⭐️.
pdf: https://t.co/1dpWUNI5Oz
src: https://t.co/1nxyhEOwLz
NetHack is arguably one of the most challenging games for humans and even more for RL algorithms. Maybe, offline RL could help? Time will reveal.
To bootstrap the practitioners, we release Katakomba — Tools and Benchmarks for Data-Driven NetHack.
https://t.co/yOzzJqxnUO
📢 Exciting research from our team! We explored the power of seemingly minor design choices in offline RL by applying them to an established minimalistic baseline developed by @shaneguML. The outcome? Just follow this 🧵
There were a lot of algorithmic innovations in offline RL recently, along with a silent evolution of minor design choices.
What if we applied these seemingly minor modifications to an established minimalistic baseline by @shaneguML? Turns out, gains are enormous.
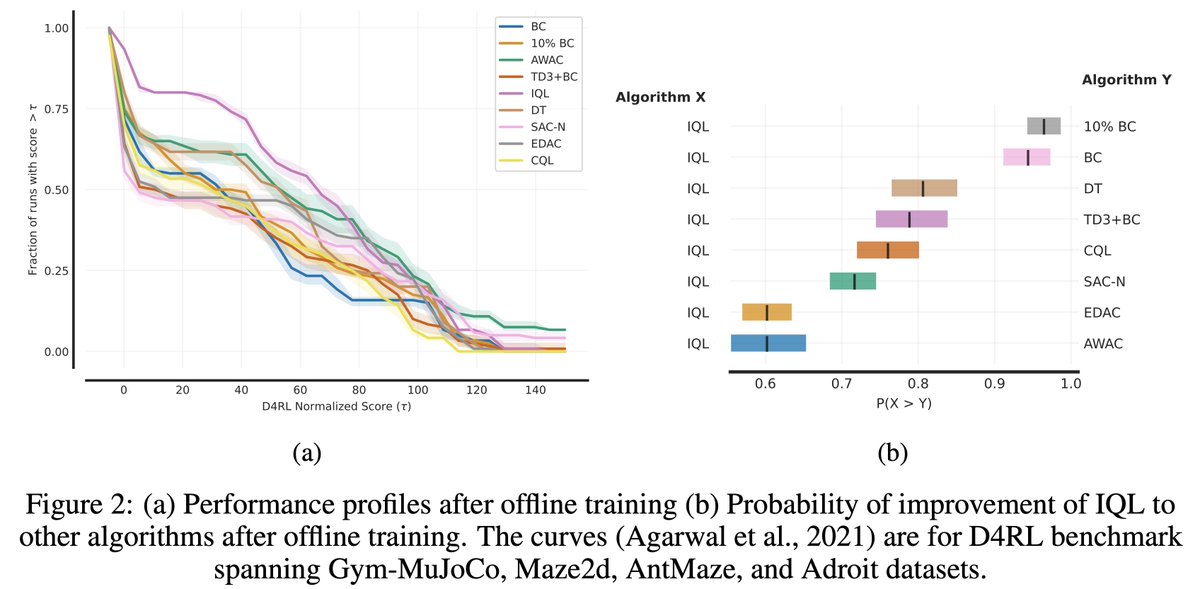
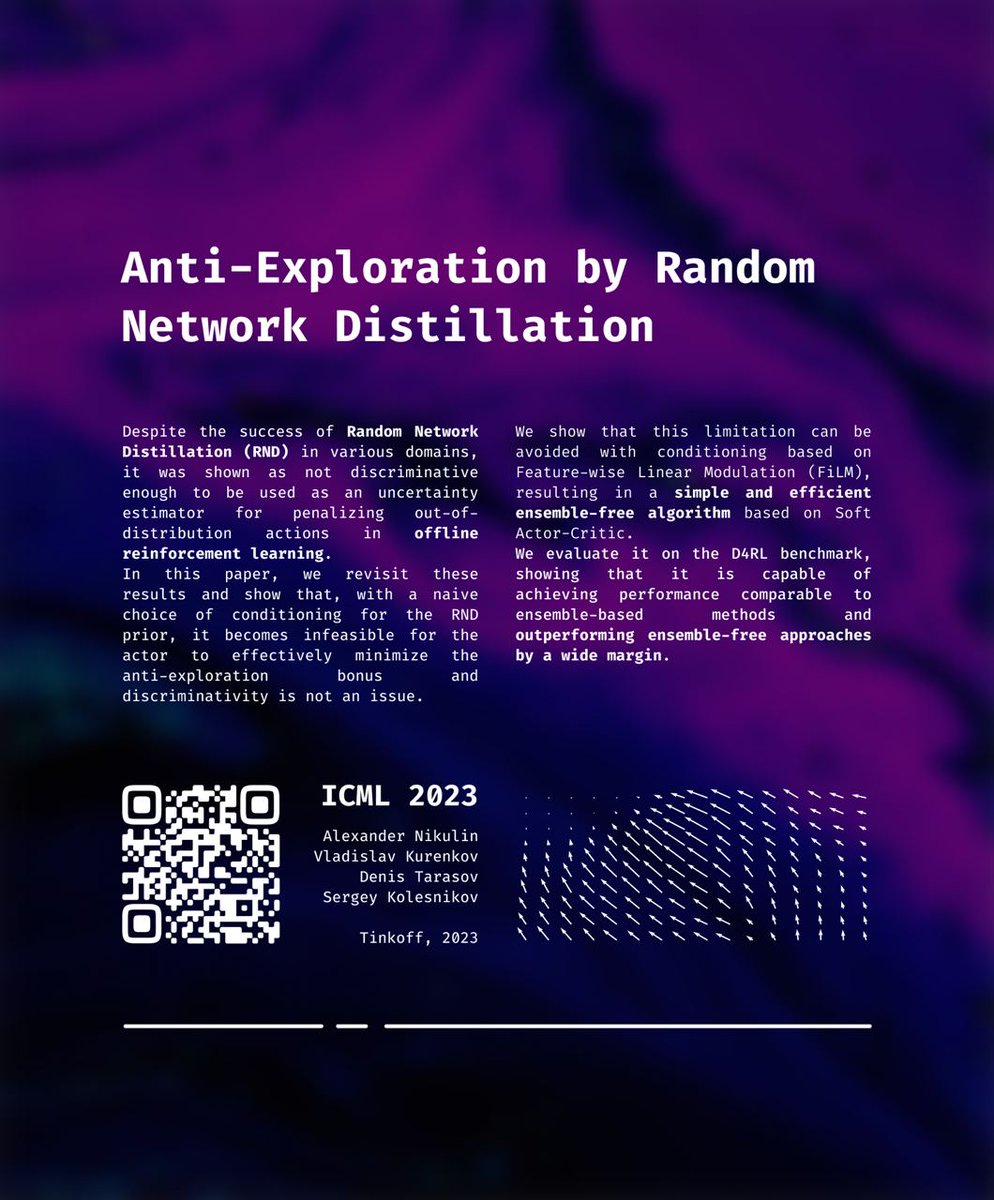
Exciting news: Our paper has been accepted at ICML! Our work focuses on improving the reliability of offline RL algorithms and tackling overfitting through an anti-exploration bonus. And the best part? SAC-RND challenges SOTA results with a single network, no ensembles required!
This year we managed to do the impossible. We launched the AI research department, and we launched it noticeably – with recognition from the world's leading AI conferences: ICML and NeurIPS (both spotlights). But I want to believe that this is just the beginning...
In our new paper 🚀 we optimize accuracy via gradient descent! The work, called "EXACT: How to Train Your Accuracy", will be presented at the TAG-ML workshop during #ICML2022 🙃
Paper: https://t.co/a3krceFB3r
Poster: https://t.co/ZrqdJtmrTY
Enjoy!)
Extremely pleased to announce that our paper “Showing Your Offline Reinforcement Learning Work: Online Evaluation Budget Matters” was accepted to ICML 2022 (Spotlight)!
https://t.co/hgaymrbSg4
(1/N)
If you're at ICLR now, check Generalizable Policy Learning in the Physical World workshop tomorrow. We will present Prompts and Pre-Trained Language Models for Offline Reinforcement Learning and will be happy to share its current improvements. We have some 😉