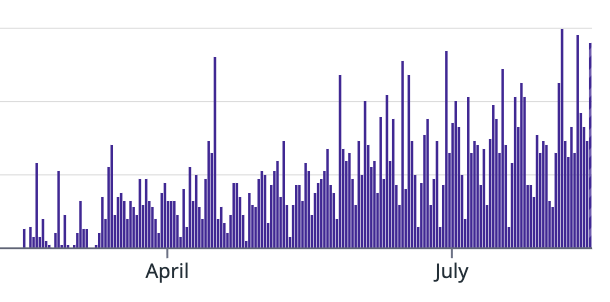
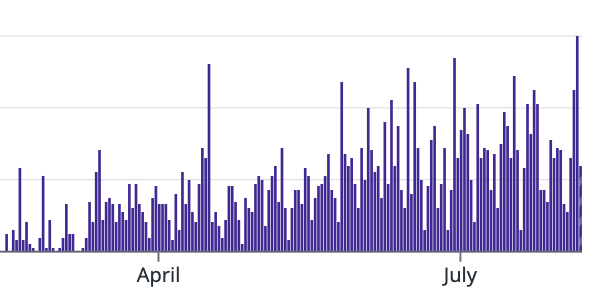
We @SindarinTech now run the leading vertical voice agent in a particular industry, with only 2 engineers.
We have been forced to see far ahead of the curve to stay alive.
Running a successful vertical voice agent typically requires multiple companies (a "horizontal" platform below the "vertical" company; another company providing evals; and yet others running inference for different parts of the stack).
We run nearly our whole stack on self-managed bare metal.
All the way from custom turn-taking models, to evals, to industry-specific dashboards, CRM integrations, and everything in-between.
We did it because we are badass, but also because we are necessarily, utterly levered to the gills with AI.
For example:
We deployed an internal employee - Samwise - in Slack on December 4. One week after Opus 4.5.
One of my favorite moments reading through @SindarinTech transcripts:
Customer calls in, hears they're speaking with AI.
Petulantly requests to speak with a human.
AI gently notifies them it can fulfill their need.
5 minutes later, the customer's intent is completely fulfilled, and ending the call with "Thank you."
This paper didn’t go viral but it should have.
A tiny AI model called HRM just beat Claude 3.5 and Gemini.
It doesn’t even use tokens.
They said it was just a research preview.
But it might be the first real shot at AGI.
Here’s what really happened and why OpenAI should be worried: 🧵
Here's the thing about deploying truly low-latency, full-duplex, realtime speech products in the real world:
You only have a couple of hundred milliseconds to do *all of the work* that you need to do to prepare your response to the user.
Most products that implement sophisticated text-based chat agents today do all sorts of RAG; auxiliary LLM calls; API calls; and so on after their user hits "send" and before generating a final response.
You cannot do it that way for realtime speech. For all practical purposes, you will *never* be able to do it that way for realtime speech.
You are battling the speed of light and RDBMS r/w speeds with every API call.
You are battling LLM TTFT and ITL - which can't fit the latency criteria even using a 7b on an 8xB200 today - with every secondary LLM call.
So the architecture of a realtime, full-duplex speech product needs to be fundamentally different.
You need new models and new infrastructure that can make speech products useful while still being lightning-fast.
That's what we've built at @SindarinTech.
When you speak with the Persona on our landing page at https://t.co/yIli8nWoya, we immediately get a summary in a Slack channel that looks like this.
If you say something hilarious, I'll post it here.
We released one of our first demos, https://t.co/Lsvsy1nP4I, nearly two years ago.
Someone just had an 18 minute conversation with it.
It's still using gpt-3.5-turbo.
Peter Thiel: “AI in 2024 is like the Internet in 1999”
“It’s clearly going to be important, big, transformative, have all kinds of interesting social and political effects - maybe even effects about how humans think about themselves. But on a business level, it’s very, very treacherous. There were a lot of different Internet businesses that failed, and even the ones that succeeded, it was quite a rollercoaster.”
He gives Amazon as an example. In 1999, it hit $113 a share, but by October 2001, it declined to $5.50.
“If you’d held it from December 1999 to today, you would have made 25x your money, but you would have first lost 95%. And then if you’d bought it in October 2001, you would have made 500x. So in some sense, Amazon was the obvious Internet company to invest in, and even that was quite a roller coaster.”
He continues:
“My suspicion is that that’s roughly where we are in AI. It’s correct as a technology, but extremely bubbly and crazed as a company-building thing or as a sector to invest.”
Video source: @triggerpod (2024)
OpenAI scraping the public web and your work, then selling you access for $2000: 😬🖕♻️🤬🤢
DeepSeek training on your work, then returning it for free and compiled as part of a model: 😻🦾🐘🐳🇨🇳
Mark Zuckerberg on the importance of engineers if you’re building a technology company
“We never thought about ourselves as a website or a social network or anything like that.”
Mark believes many companies define themselves too narrowly:
“It’s one of the things I observed as soon as I came out to [Silicon] Valley. All these companies that called themselves technology companies were not really set up that way. The CEO wasn’t technical. The board of directors had no one technical on it… And it’s like alright, if that’s your team, then you’re not a technology company.”
He believes there’s a balance:
“You don’t want everyone to be an engineer because there’s other things that matter too. But if you don’t have a high enough share of the company as engineers, then you’re not a technology company.”
This makes sense when you view it in the context of Mark’s strategy for Meta:
“I define our strategy as: If we can learn faster than every other company, we’re going to win. We’re going to build a better product than everyone else because we’re going to get it out first, we’re going to have a good feedback loop, and we’re going to learn what people like better than other people.”
He concludes:
“I think that’s basically the formula. Be a technology company. Build a good foundation. Learn from what other people are focused on in the world. And iterate as quickly as you can.”
Video source: @AcquiredFM (2024)