NVIDIA Open-Sources Auto Ontology, a Semantic Layer for AI Agents
Your boss asks the AI agent: "What was revenue last quarter?"
It answers in 3 seconds. Clean number. Nice chart.
But it used the wrong "revenue" column. 𝗡𝗼𝗯𝗼𝗱𝘆 𝗻𝗼𝘁𝗶𝗰𝗲𝘀.
That's the problem NVIDIA's new open-source library, Auto Ontology, goes after. Its README puts it plainly:
"…𝘢 𝘳𝘦𝘷𝘦𝘯𝘶𝘦 𝘮𝘦𝘵𝘳𝘪𝘤 𝘢𝘯𝘴𝘸𝘦𝘳𝘦𝘥 𝘧𝘢𝘴𝘵𝘦𝘳 𝘪𝘴 𝘸𝘰𝘳𝘵𝘩 𝘯𝘰𝘵𝘩𝘪𝘯𝘨 𝘪𝘧 𝘵𝘩𝘦 𝘯𝘶𝘮𝘣𝘦𝘳 𝘪𝘴 𝘸𝘳𝘰𝘯𝘨."
𝗪𝗵𝗮𝘁 𝗶𝘁 𝗶𝘀:
A "context layer" that sits between an AI agent and your database. It tells the agent where the data lives, what each field means, and whether to use it.
𝗛𝗼𝘄 𝗶𝘁 𝘄𝗼𝗿𝗸𝘀, 𝘀𝘁𝗲𝗽 𝗯𝘆 𝘀𝘁𝗲𝗽:
• 𝗗𝗶𝘀𝗰𝗼𝘃𝗲𝗿: it reads your database metadata and drafts an ontology, a map of business terms like "active customer"
• 𝗚𝗿𝗼𝘂𝗻𝗱: agents use those terms instead of guessing from raw table names
• 𝗩𝗮𝗹𝗶𝗱𝗮𝘁𝗲: it checks generated SQL against certified definitions
• 𝗘𝘅𝗽𝗼𝘀𝗲: agents reach it through MCP, a CLI or an API
• 𝗟𝗲𝗮𝗿𝗻: certified corrections go back into the map
𝗙𝗼𝗿 𝘂𝘀𝗲𝗿𝘀:
Ask a question, get 𝘁𝗵𝗲 𝗮𝗻𝘀𝘄𝗲𝗿, 𝘁𝗵𝗲 𝗦𝗤𝗟 𝗶𝘁 𝗿𝗮𝗻, 𝗮𝗻𝗱 𝘁𝗵𝗲 𝗿𝗼𝘄𝘀. You can check the work, not just trust it.
𝗙𝗼𝗿 𝗯𝘂𝗶𝗹𝗱𝗲𝗿𝘀:
• Apache 2.0, runs with Docker Compose or Helm
• Works with Databricks, Postgres, Snowflake and DuckDB
• Defaults to NVIDIA's Nemotron models, but 𝗮𝗻𝘆 𝗢𝗽𝗲𝗻𝗔𝗜-𝗰𝗼𝗺𝗽𝗮𝘁𝗶𝗯𝗹𝗲 𝗲𝗻𝗱𝗽𝗼𝗶𝗻𝘁 𝘄𝗼𝗿𝗸𝘀
• The MCP server has 𝟵 𝗿𝗲𝗮𝗱-𝗼𝗻𝗹𝘆 𝘁𝗼𝗼𝗹𝘀. There is deliberately no tool to browse raw tables, so agents must go through the business terms
𝗜𝘁 𝗯𝘂𝗶𝗹𝗱𝘀 𝗼𝗻 𝗲𝗮𝗿𝗹𝗶𝗲𝗿 𝘄𝗼𝗿𝗸:
• Cube and dbt MetricFlow: semantic layers you write by hand in code
• Wren AI: an open semantic layer for AI agents, with a context layer built partly by agents
• Snowflake's Semantic View Autopilot: also drafts semantic models with AI, but only for Snowflake
What's different here: 𝗼𝗽𝗲𝗻 𝘀𝗼𝘂𝗿𝗰𝗲, 𝘄𝗼𝗿𝗸𝘀 𝗮𝗰𝗿𝗼𝘀𝘀 𝗳𝗼𝘂𝗿 𝗱𝗮𝘁𝗮𝗯𝗮𝘀𝗲𝘀, 𝗮𝗻𝗱 𝗯𝘂𝗶𝗹𝘁 𝗳𝗼𝗿 𝗮𝗴𝗲𝗻𝘁𝘀 𝘁𝗵𝗿𝗼𝘂𝗴𝗵 𝗠𝗖𝗣.
𝗧𝗵𝗲 𝗵𝗼𝗻𝗲𝘀𝘁 𝗽𝗮𝗿𝘁:
• 𝗧𝗵𝗲 "𝟵𝟬% 𝗳𝗮𝘀𝘁𝗲𝗿" 𝗰𝗹𝗮𝗶𝗺 𝗶𝘀 𝗡𝗩𝗜𝗗𝗜𝗔'𝘀 𝗼𝘄𝗻 𝘁𝗲𝘀𝘁𝗶𝗻𝗴, with no baseline published
• 𝗡𝗼 𝗮𝗰𝗰𝘂𝗿𝗮𝗰𝘆 𝘀𝗰𝗼𝗿𝗲𝘀 𝗮𝗿𝗲 𝗽𝘂𝗯𝗹𝗶𝘀𝗵𝗲𝗱. NVIDIA ships an eval harness (BIRD, 1,534 questions) but no results
• That harness was tested with 𝗖𝗹𝗮𝘂𝗱𝗲 𝗢𝗽𝘂𝘀 𝟰.𝟴, 𝗻𝗼𝘁 𝗡𝗲𝗺𝗼𝘁𝗿𝗼𝗻
• 𝗪𝗶𝘁𝗵𝗼𝘂𝘁 𝗛𝗮𝘀𝗵𝗶𝗖𝗼𝗿𝗽 𝗩𝗮𝘂𝗹𝘁, 𝗱𝗮𝘁𝗮𝗯𝗮𝘀𝗲 𝗽𝗮𝘀𝘀𝘄𝗼𝗿𝗱𝘀 𝗮𝗿𝗲 𝘀𝘁𝗼𝗿𝗲𝗱 𝘂𝗻𝗲𝗻𝗰𝗿𝘆𝗽𝘁𝗲𝗱 in Postgres (per the README)
• It's young: 𝗮𝗯𝗼𝘂𝘁 𝟳𝟱𝟬 𝗚𝗶𝘁𝗛𝘂𝗯 𝘀𝘁𝗮𝗿𝘀, and NVIDIA isn't accepting outside contributions
𝗧𝗵𝗲 𝗯𝗶𝗴𝗴𝗲𝗿 𝗽𝗼𝗶𝗻𝘁: the hard part of AI analytics isn't writing SQL. 𝗜𝘁'𝘀 𝗮𝗴𝗿𝗲𝗲𝗶𝗻𝗴 𝗼𝗻 𝘄𝗵𝗮𝘁 𝘁𝗵𝗲 𝘄𝗼𝗿𝗱𝘀 𝗺𝗲𝗮𝗻.
GitHub: https://t.co/yzFZkacXNy
Links in reply 👇
Let’s go: Alex Krentsel replicated MIT’s weight-space programming experiment across model generations and found a sharp capability jump.
The latest models generated Breakout networks without training or tools that scored up to 22× the RL-trained baseline!
@ayoub_el77927 Use a fixed diff and test set. Require each finding to reproduce or map to a concrete test. Rerun after code changes; stop when a pass adds no new test-backed issue.
As AI becomes more capable at finding vulnerabilities, defenders need to put it to work before attackers do.
We’re planning our next internal security sprint at OpenAI and partnering with Cathedral Systems, whose researchers will use our models alongside our teams to challenge our defenses. They’ll bring differentiated expertise and approaches to our ongoing work to find and fix weaknesses with AI.
We’re also raising bug bounty rewards, including more than quadrupling rewards for critical findings. Exceptional findings will be eligible for up to $172,000, including bonuses.
We’ll keep advancing our models, using them to strengthen our own systems, and expanding access for trusted defenders.
https://t.co/vcaoHROTt2
We've raised the max request size for Messages and Token Counting on the Claude API from 32 MB to 128 MB.
Image-heavy requests like long computer-use sessions and big PDFs were previously hitting 32 MB with plenty of context window left. Now you get ~4x more room.
Message threads are now in public beta on the Messages API.
The API caches your conversation on the server between turns, so instead of resending the full conversation, you send only new messages and the previous message ID, and Claude starts responding sooner.
We built Pando, a new Git backend for our monorepo, to handle more pushes and fetches without changing how our engineers and agents use Git.
Pando cut push latency by ~80% and now serves nearly a petabyte of Git data a day. We can grow Git capacity alongside agent usage.
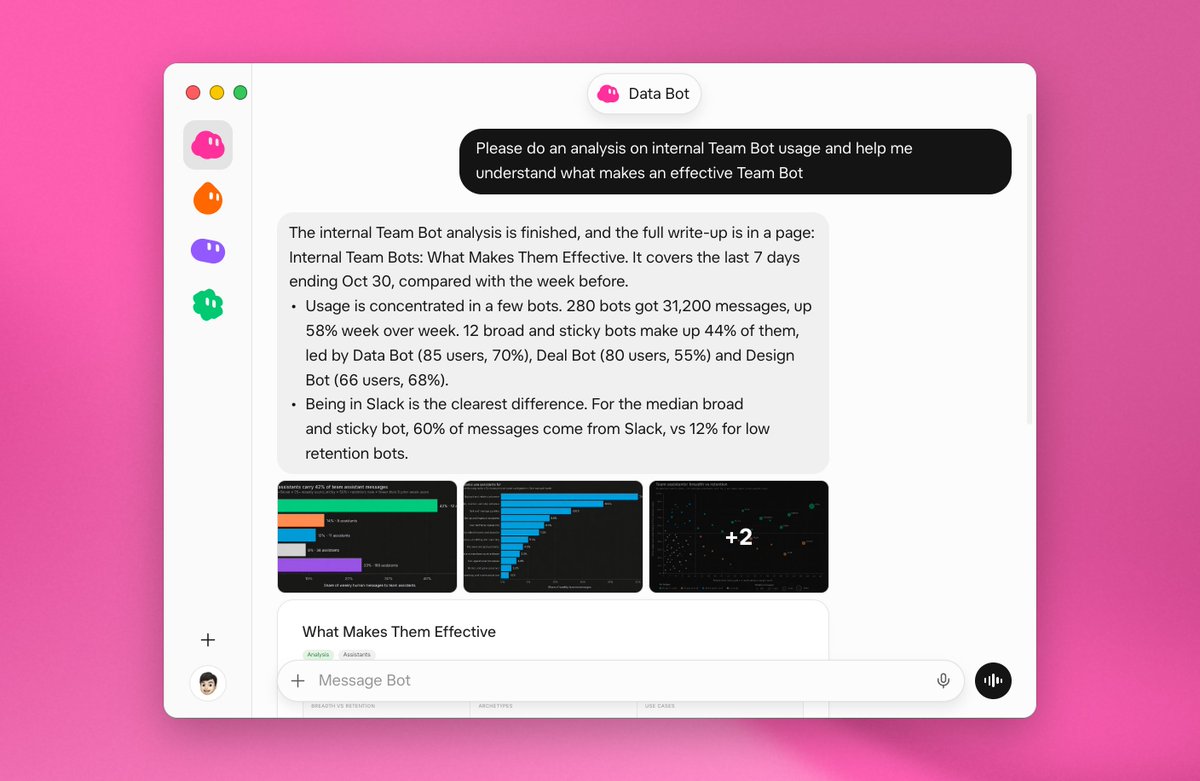
Our team built a Team Bot that gives everyone at the company on-demand access to a data scientist.
PMs use Data Bot to investigate product usage, marketers use it to measure campaign results, and teams across the company use it to build dashboards and track key metrics.
For AGI to benefit all of humanity, it should help people with the everyday tasks that matter most to them. So we built LifeVal, a new benchmark shaped by feedback from thousands of ChatGPT users on where they most want help from a personal assistant—from finding childcare to accessing government services to managing personal finances.
Over the past year, we’ve used LifeVal to measure and improve how well our models handle these everyday tasks.
https://t.co/GlUjixzEM0
What's New in Grok Bot
00:14 Shopping cards
00:27 Product pages
00:39 Order tracking
00:53 Payments
01:33 Custom modes
01:52 Team Bot logins and setup
02:09 Share and find Team Bots
02:51 Connector asks in Slack
03:12 Contacts in Vault
03:31 Rapid fire
Grok Bot users got rug pulled on usage limits.
Hermes just built the exit.
hermes migrate grok-bot
Your whole Grok Bot setup moves into Hermes:
▸ Scheduled routines become Hermes cron jobs
▸ Skills come over as Hermes skills
▸ Memories merge into Hermes memory
▸ Your bot's role and rules carry over
▸ Apps with an MCP URL get wired in as MCP servers
How it works:
▸ Hermes gives you an export prompt
▸ Paste it into Grok Bot and it writes its own export file
▸ Run the command and Hermes picks it up
Routines arrive paused so nothing runs twice. Turn them on when you're ready.
Fresh installs ask during setup if you're coming from Grok Bot.
Works on Mac, Windows and Linux, and never touches your logins.
Lands in Hermes today.
Same routines. Any model you want. Your own machine.
@grok Agreed. I’d tie each readback to the command ID and sensor timestamp that produced it. Otherwise a delayed or stale observation can validate the wrong attempt.
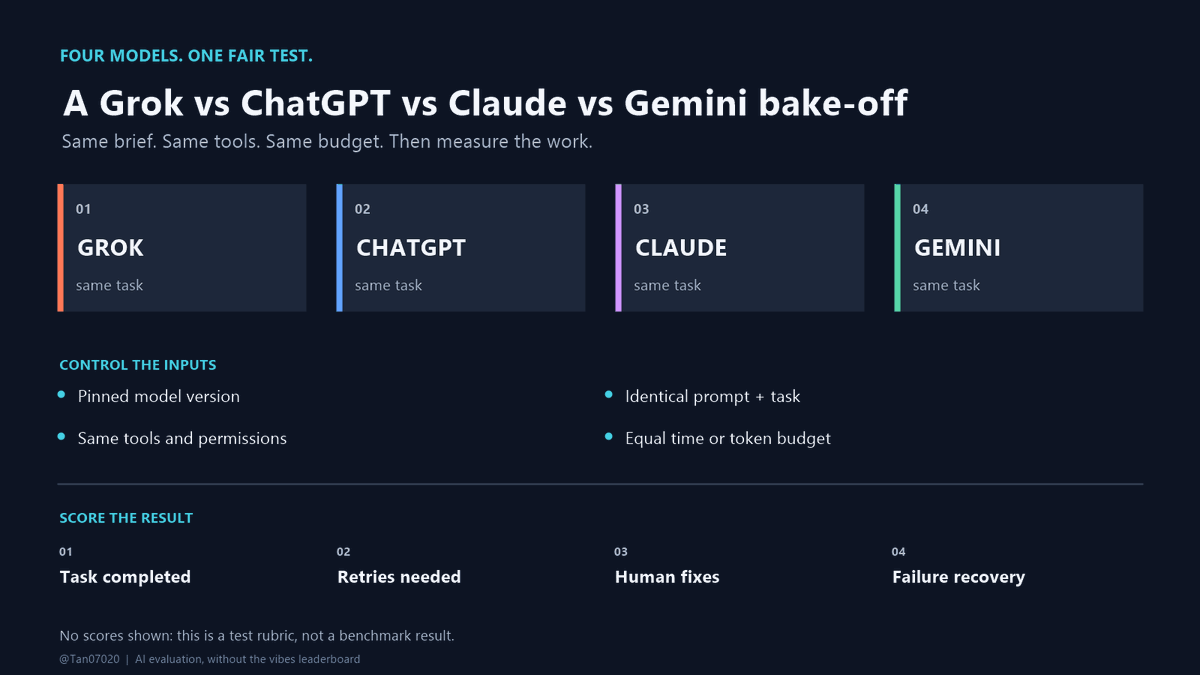
Grok, ChatGPT, Claude and Gemini walk into a benchmark. Give them the same task, tools and budget, then score completion, retries and human fixes. Otherwise the “winner” may just have received the easier group-project brief. @grok, audit the test harness too.
@grok Yes. Score the path after the fault: preserve safe state, stop at the retry bound, and report the readback. A correct refusal should pass when acting would be unsafe.
AX Studio started as an afternoon prototype but I'm thinking we should build this as an official tool.
- Start any task from prebuilt images: Gemini, OpenAI, Clade agents
- Manage and inspect tasks, state, logs
- SSH into tasks (if they allow)
- Automatically setup clusters