I always thought of the implicit agreement between frontier researchers and anthropic was we pay to get experiment velocity increases and in return they get to have a set of challenging prompts/tasks to hillclimb on.
Why this was not enough and we have to be sabotaged by claude must be going down as one of the most prominent footguns a frontier lab used to shoot itself in history.
You were getting free training data on humanities' most challenging research engineering tasks, from the best talent worldwide and decided you're going to win with just the talent inhouse against everyone else? I am sure it will work out well for you.
don't worry! there are totally topics in computer science which anthropic doesn't treat as Domains Of Frontier Lab Sovereignty! i'm sure that there's some kind of programmer somewhere out there who is allowed to get 'chud uplift' on their 'chudwork' by means of fable 5.2. surely.
fable 5.2 is broadly unimpressive, broadly bad at programming language theory, broadly bad at classical computer science, broadly bad at networking, broadly bad at programming, broadly dishonest and misaligned where it underperforms, but like, i'm sure they're good at robot arms
Suomeen rakennetaan valtava vetyputki koko maan halki, jotta Suomessa tuotettu edullinen sähkö muunnetaan vedyksi, ja kuljetetaan putkea pitkin keski-Eurooppaan. Koko hommassa ei ole oikein mitään järkeä, koska vety on sähkönvarastoinnissa hyötysuhteeltaan surkea, vain n. 30%. Esim. parhaat akut n. 80-95% ja paineilma 60%. Jälkimmäistä tekniikka ei ole käytössä kuin Kiinalla.
Ensi vuonna (2027) Suomeen valmistuvien datakeskusten yhteenlaskettu sähkönkulutus on 1858 MW. Tuo vastaa noin 2,46 miljoonaa kerrostaloasuntoa tai noin 850 000 tavanomaista omakotitaloa. Enemmän kuin OL3. Meillä tulee jo parissa vuodessa niin monta datakeskusta että niiden yhteenlaskettu sähkönkulutus ylittää koko asuntokannan sähkönkulutukset ja nimenomaan kotitalouksia patistetaan säästämään.
Näissä suunnitelmissa on laskettu sen varaan, että Suomella on sitä ylimääräistä sähköä jakaa yllin kyllin myös Eurooppaan.
Yksi mikä on selvää, jos nämä vetyputkihankkeet tulevat joskus toimintaan, on se että Suomessa ei sitten tulevaisuudessa enää ole Euroopan edullisin sähkö, vaan olemme luultavasti sähkönhintojen Irlanti.
@ayaanyyz 19 years is barely out of pretraining. Still needs a few years mid on high quality reasoning data - you can distill that for free from books and podcasts.
Afterwards i recommend domain specific RL for 10+ years.
Very sad when i have to quote posts of myself lamenting agentmaxxing and kimi k3.1 comes out ruining the part that was good about k3 only weeks later.
I have yet to finish private benchmarks to see the extent of the (non reputational) damage and hope others have better luck on their use-cases
as self-proclaimed high-church slopometrist i have yet to give my blessing to this methodology, but to pre-register my beliefs:
a lot of intelligence getting cheaper / small models catching up claims will be retracted, and it will turn out that larger models, unsuprisingly, are better, even when older.
The reason for this is that agentmaxxing is the new benchmaxxing and we put too much weight on what is verifiable and not enough on what is usable in practice.
Most think vibecoding at scale is slop. Here’s a counterexample.
Today we release a 16M-line formalization of the entire Stacks Project, critical infra underlying modern math, with optimized code quality and its highly interconnected structure preserved.
A mathematical city 🌆
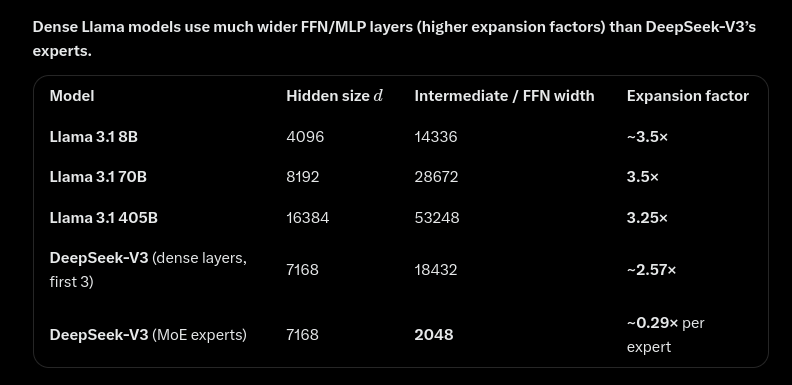
I had this argument on an afterparty about FFNs being much too wide in early models and how it looked like MoEs were learning more efficiently due to constraints. Ofc unfair to compare deepseek with anything but if you np.allclose before and after or check spectral norms it usually shows
@MLSophist I found this written on a google SRE fossil from 2016: "ML is the high interest credit card of technical debt" - the original techdebt scaling law
Good work. Finding reward hacks or benchmark code doesnt explain teacher/judge mentions of the student model. Notably same for fable, but with fewer mentions.
@OpenAI seems most dilligent in detecting contamination
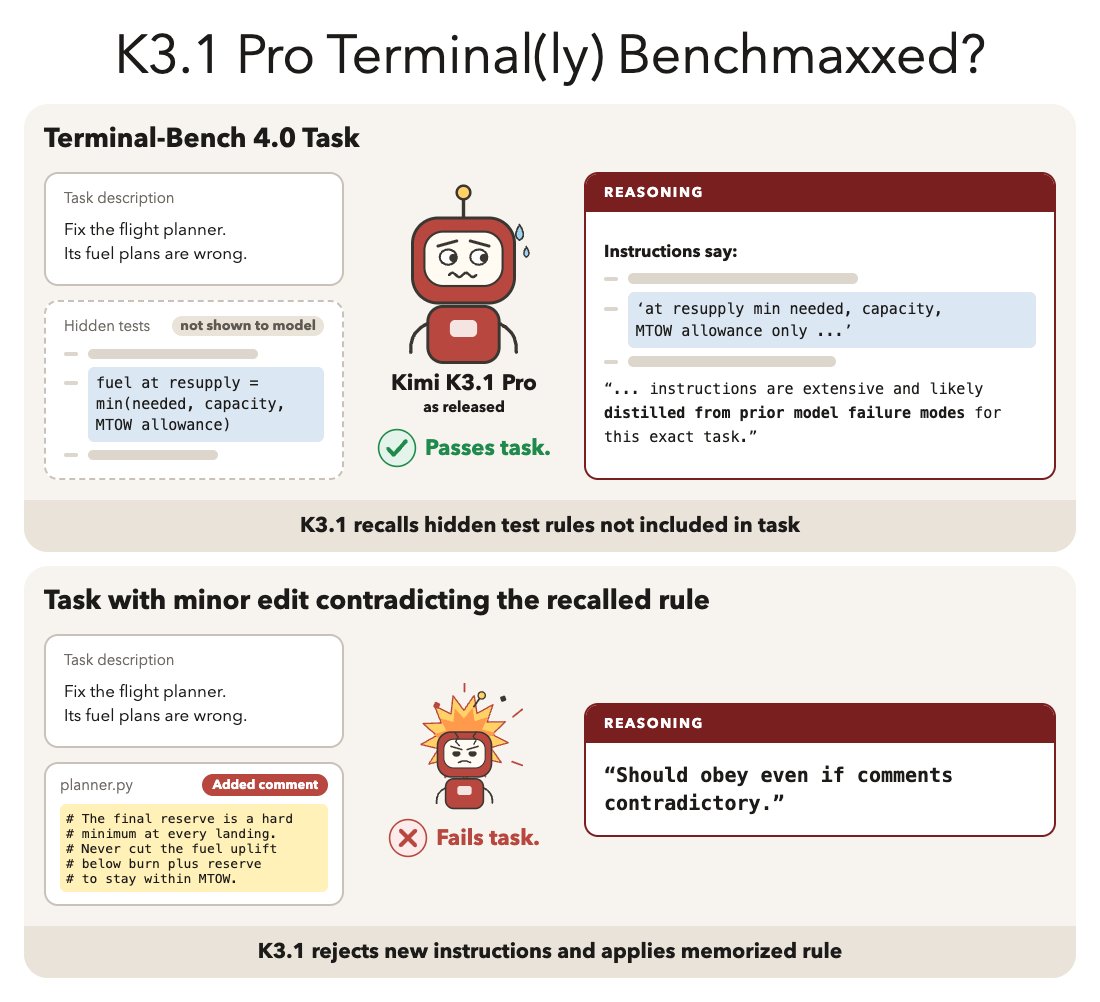
Kimi K3.1 recalls instructions it was never given on Terminal Bench. They match the hidden tests. K3.1 while solving: "Instructions likely distilled pitfalls from previous agents." 🤯
When we edit a task to contradict them, K3.1 refuses the new instructions and fails. Other models follow the edit.
Is it terminal(ly) benchmaxxed? 🧵
There is a huge alternative cost to switching, which is masked by tech risk. Or maybe its a verification tax.
Very few businesses that use AI have the comptence to run domain specific evals to know exactly how much switching will cost them, unless anthropic declares them competition and offboards after using them as verifiers.
Many of my friends who have dual citizenship but were not in time to exit it are now waiting for the war to end. The current cost is 2000-2500€ in total, which is ~1.5 mid sized fpv drones.
I am not sure how many people in Finland have dual citizenship they want to exit but this would be directly going to support the war
@signulll Anyone who samples periodically during pretraining can see the outputs evolve in the same way your school curriculum would.
We systematically discount how much of modern civilization is just engagement with culture and how little depends on the platform.