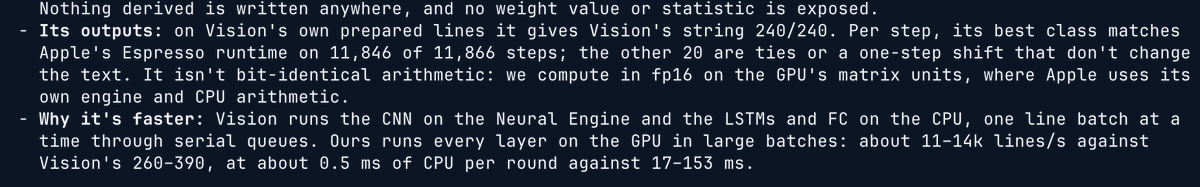
the apple ocr api runs like 1/100th of the speed the hardware would support specifically and uniquely because apple swes are incapable of writing a recurrent network layer for MPS or ANE, so they wrote a kernel which runs half on the apple gpu and half on cpu.
if you wanted to do a lot of ocr, like ocr of the entire screen of the computer you're using, this implies batchsizes more than great enough to saturate any of the tensor oriented apis for apple silicon!
there is no funny 'small batchsize bc edge deployed' regime here!
@teortaxesTex they'll invent a new kind of model which uses 250m active parameters per 270b total and has a kv cache persistence of 2 months and the api users will *brag* about how inexpensive their sub is compared to the decadent employed class. but everyone will know deep in their hearts...
@teortaxesTex supply is limited, so prices per unit will explode instead.
it will become more expensive, then more expensive again, then when the masses cry out and shit their pants for it could not become any more expensive, it will become *even* *more* *expensive*.
suddenly i understand a lot more of the complaints that i saw people raising about using slop cannons for coding; i think i've simply avoided catching the claudes et al in lies by cleverly guessing when they *would* be liable to start lying and backing them out of their bullshit
claude decides to simply lie and guess that some other document is the one that's about infinite graphs, writes two different three sentence summaries, one of a real wrong document, another of a completely imaginary document
https://t.co/GS7P8jw6YD
few know that abliteration is not, altogether, how to put this, 'real', rather than a social illusion or technomysticism propagated by those who have never trained a deep learning model, even fine tuning, even parameter efficient fine tuning.
Concerning. DeepSeek is baking safety into the model at a deep level. I don't think it's just XinjiangQA.csv this time, and it's not a distillation artifact. Also, I see 1017 cheating *a lot*. After scaling up agentic RL, they must have become spooked.
Frontier problems.
so after today's incident i hope we can all agree to never use certificate authorities or any other backdoor-based-security where the only purpose of the security apparatus is to give quasi-deniable backdoors to freaks
acs infra launched our free base model api! if you're into base models, looming, or llm psych-adjacent research, please apply, even if just to play around and build intuitions.
forwards only optimizers are boring.
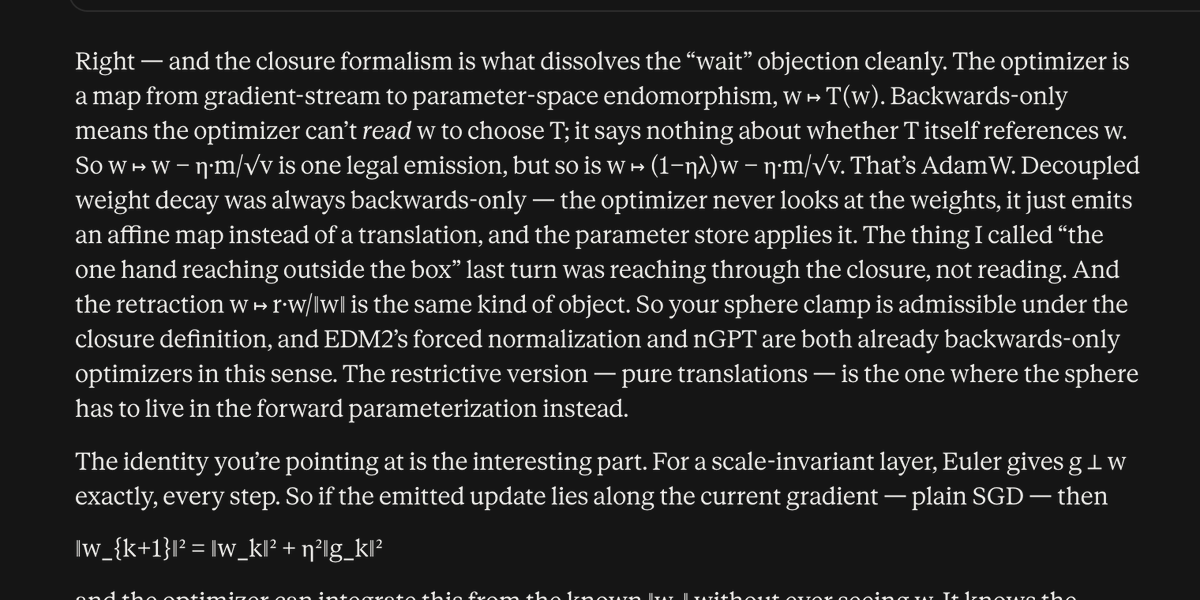
let's move on to backwards only optimizers, which interact only with the gradient and do not know the weights they are optimizing and in so doing do not know the forwards pass of the backwards they're optimizing.
"wait how does this work doesn't an optimizer need to have the weights somewhere--"
obviously this means that the optimizer consumes a gradient as an operand and returns a state transformation function for all parameters in the model, compiling-in optimizer-latents somehow.
@softminus video models and diffusion models and dedicated image only models are over. they are really, really, really over. the model can do everything, including host an assistant persona or subagent doer, or it can do nothing at all