@Codexresets_ Price/performance should include retries and review time, not just tokens. I'd like to see Sol vs Astra on the same existing repo task. A Greenfield demo is the easy case; keeping the next change clean is the real test.
I got tired of hitting the limits on a $200 subscription.
So I built my own Codex harness.
Automatic model selection. Reasoning effort matched to the task. Less time choosing settings, more time building.
Now it's open source.
Take it. Break it. Make it better.
https://t.co/2Z18FJsuoJ
How many tokens are we wasting on unnecessary reasoning?
I released my Codex harness yesterday and pushed another update today. Alongside that, I tested how much difference reasoning effort actually makes.
I used to run almost everything at maximum reasoning. Seemed obvious: more thinking, better results. But when you're running this many agent sessions, you want to know what you're spending that budget on.
I tested Gemini 3.8 Flash, GLM-5.3 Flash and DeepSeek V4.1 Flash on the same tasks at different effort levels. Gemini through Antigravity, GLM and DeepSeek through Wally. All through my OmniRoute setup.
594 request records in total, including repeats, controls and failures. I measured correctness, total response time and output tokens.
Gemini surprised me the most.
On the expanded 36-task set, low used 68.7% fewer output tokens than high.
Average response time dropped from 14.59s to 7.90s. Correct answers: 36/36 on low, 35/36 on high.
High's one failure was a length cutoff. Even after removing that entire pair, low still used 66% fewer tokens.
The effect repeated across runs: 64.5% less output in the first numerical series, and 84.3% less on a small function-generation set.
For these tasks, I was giving the model more thinking, waiting longer and spending more tokens without getting better results.
GLM wasn't so straightforward.
In the expanded series, low used 39.9% fewer output tokens. Both modes solved 33 of 36 tasks.
Average response time was 45.6% lower, but one long timeout on high contributed to that gap. On pairs where both requests finished normally, the advantage was 26.6%.
Low was faster on only 17 of 36 tasks. In the function-generation series, it actually used 36.8% MORE output tokens.
So I can't just switch GLM to low and call it solved. The task matters.
DeepSeek: why leave it on max?
All three modes solved 36/36 tasks, all in valid JSON.
Total output tokens:
• Low: 78,836
• High: 105,781
• Max: 133,767
Average response time: 5.43s / 6.61s / 8.75s, respectively.
Low used 25.5% fewer tokens than high and 41.1% fewer than max. Average response time was 37.9% lower than max.
On this set, leaving it on max wasn't worth it.
Then there was the variance.
I repeated the same DeepSeek prompt at the SAME effort level. In one control pair, the second response used about 3.8x as many output tokens. Both answers were correct.
That's why I kept running tests. One impressive result can look very different on the next attempt.
For my harness, low looks like a good starting point for short, verifiable Gemini tasks. DeepSeek also gives me a reason not to default to max. With GLM, the choice depends more on the work.
Harness:
https://t.co/2Z18FJt2eh
10 likes and I'll compare the leading models: how well they handle the tasks and how many tokens they spend doing it.
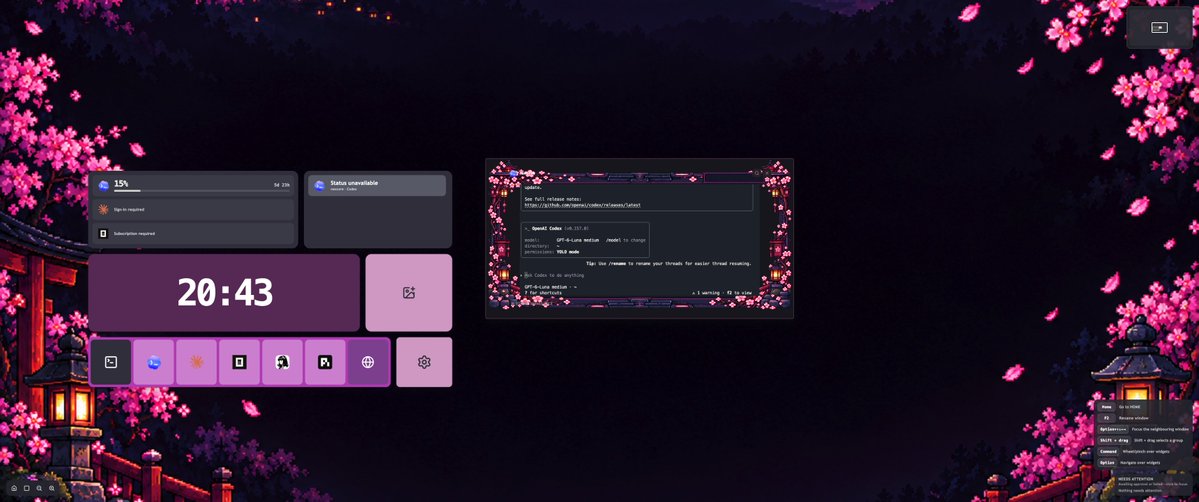
People give ChatGPT Astra on High a lot of flak, but a couple of days and a few evenings with it can get you a desktop like this.
It can be any Linux distro, Omarchy included. What matters is the ShojiWM compositor. I forked it too, adding support for different languages, new shaders, and optimizations.
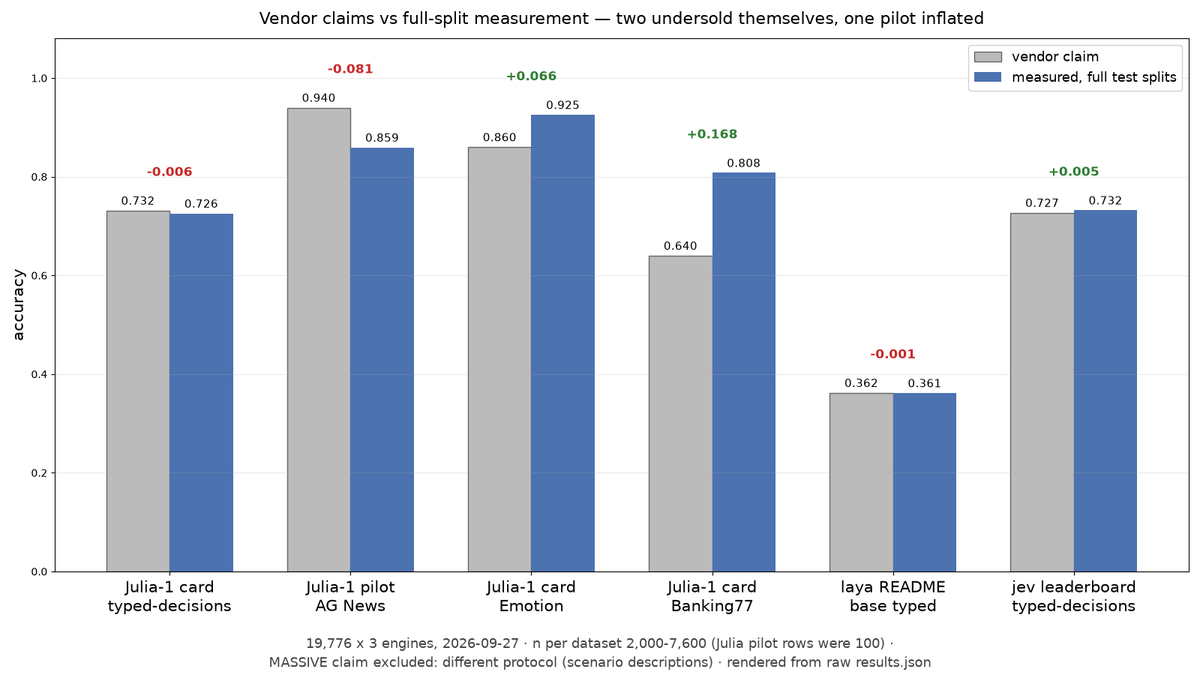
I ran jev (@typesafeai), laya (@Nandakishorm1) and Julia-1 (@supersonicai) on the same 19,776 questions: 59,328 inferences across AG News, Emotion, Banking77, MASSIVE and typed decisions, 0 failures.
I wanted to see how well published numbers survive the move from small samples to full test sets, under one setup.
Some held almost exactly. On typed decisions, laya's README reports 36.2% for the base checkpoint; under my run of the same benchmark, I got 36.1%. jev's published leaderboard score is 72.7%; under my run, it reached 73.2%.
Some dropped. Julia reports 94% on AG News using 100 examples; on the full 7,600-example AG News test set, I got 85.9%.
Some went up. Julia reports 86% on Emotion using 100 examples; on the full 2,000-example DAIR Emotion test set, I got 92.5% (credit @dair_ai / @omarsar0). On Banking77, Julia's reported result is 64%; using Julia's official tournament Router on the full benchmark setup, I got 80.8%.
So there is no simple "published numbers are too high" pattern. Small-sample reported results moved in both directions when compared with my larger/full-set runs.
The next numbers are not reported-vs-reproduced comparisons; they are the scores from this run, showing where each engine was strongest: jev 67.7% across 51 MASSIVE locales, laya 92.7% on AG News, Julia 92.5% on Emotion and 80.8% on Banking77.
Sample size, routing setup, task type and protocol can move a headline number a lot. Julia's published MASSIVE 71.5% is not compared directly here because that result used scenario descriptions, while this run used bare labels.
Dataset, raw outputs, probability vectors, manifests: https://t.co/P3G7FZMiPO
Reported vs reproduced, and per-dataset breakdown ↓
Barely made it, but it's out.
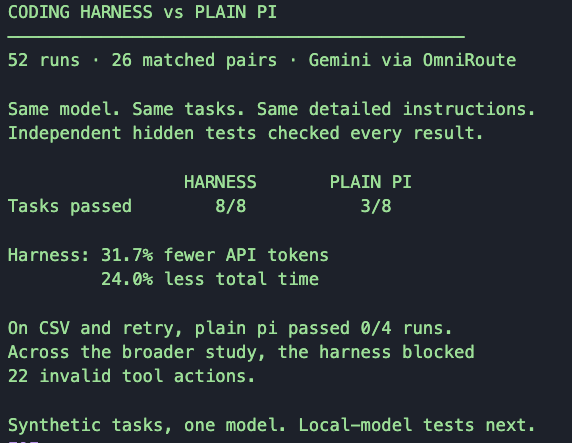
I've open-sourced the Codex harness I built to get more out of my $200 subscription.
It picks the model and reasoning level for each task. Now you can try it yourself.
To install, give your coding agent this repo:
https://t.co/2Z18FJsuoJ
Then tell it:
“Read AGENT_INSTALL.md and install this for Codex.”
The agent checks your system and walks you through setup. You'll need an OpenRouter or TypeSafe key for Jev. OmniRoute is optional.
Enter your key locally through the hidden-input prompt, not in the agent chat.
After setup, start a new Codex session, approve the new hooks via /hooks, and select jev/auto. Your current model won't switch automatically.
This is an alpha for a fresh Codex profile on macOS, Linux and Windows. The installer won't overwrite your existing configuration; if migration is needed, the agent should flag it first.
If you try it, tell me what breaks. Especially on a machine that isn't mine.
Mostly tasks that a regular worker can't handle, or coordination work across multiple workers. My setup has three tiers:
1. The main terminal delegates a task to the router, which decides whether a lightweight worker can handle it. If it can, the router picks a worker from the providers I have enabled. The result goes back to the orchestrator, which monitors and has access to the terminals.
2. If a regular worker isn't enough, or I need to review the results of a dozen workers, it goes to a mid-tier model like Sol 6. That handles most of the coordination and admin work.
3. For genuinely heavy tasks, cases Sol 6 struggles with, or setting up and managing a batch of terminals, it can use Sol 6 with higher reasoning or Astra 6.
I just open-sourced the harness, but it's still pretty raw. My post on another platform got much more attention than I expected, and I'd promised to release it if it got enough reactions. Been working flat out to get it out, and there's still plenty to improve.
Next update is reasoning/effort routing
Both are planned! And the 10 skins per theme aren't 10 unrelated designs.
Each theme has three terminal styles:
• Minimal: lightweight and unobtrusive, but still customizable.
• Detailed: basically turning the graphics settings all the way up.
• Master: a more prominent look for your orchestrator terminal, or any terminal you want to stand out.
Each style has idle, working and done variants, so the skin changes with the task's status. That's nine terminal skins, plus a matching background.
Favorites are planned too. I'm starting with five themes for the first release, but aiming for at least 40 over time.
I'm building the theme engine first rather than hardcoding everything, so users will eventually be able to create and install their own theme packs like plugins.
Been working on themes for CanvasTTY. Now testing them.
The update will include 5 main themes with 10 skins each. Here's a preview of one of them.
Planning to release it in a few days.
(still in beta)