This is what it looks like when the winner feels sorry for the loser.
Ukrainian chess player Vassily Ivanchuk and his reaction to losing at the World Blitz Chess Championship vs US player Daniel Naroditsky.
NEWS: The ERC Scientific Council has listened to the concerns from members of the research community about changes to the re-submission rules, intended to manage the surge in demand for grants.
The Scientific Council will readjust some of the changes: https://t.co/AlMC3Jts6p
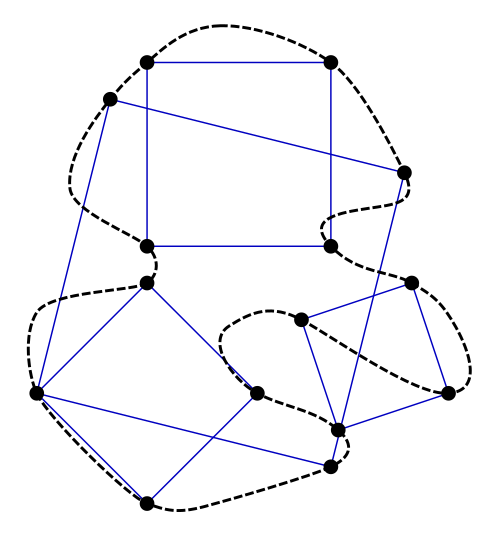
La conjecture de Toeplitz (aussi appelée problème du carré inscrit) dit que si vous tracez une courbe fermée qui ne se croise pas alors il existe 4 points de cette courbe qui forment un carré.
Cette conjecture n'a toujours pas été démontrée à ce jour.
🚨Very excited to see our work on warmth & sycophancy in LLMs out in @Nature today!🚨
We study what happens when LLMs are fine-tuned to be warmer, and find that warmth and sycophancy can be linked, with warm models showing higher errors on a range of benchmarks (🔗s below)
A stunning visualization born from a collaboration with
@manlius.bsky.social: 55,486 galaxies and 29,555 streamlines tracing how matter flows across our local universe, built on data from the CosmicFlows-4 project. Article in the first reply 👇
📘 Excited to share that Decision Making: A Very Short Introduction (OUP) is now available online (PDF for subscribers):
https://t.co/eblubeY1SU
What is it about? Understanding how humans (and other agents) make choices. Below a bit more information👇
A really dangerous situation. Too many submissions. Too many generated papers. Little responsibility.
1. In 2026, more than 24,000 submissions were made to the International Conference on Machine Learning (ICML). It’s TWO times more than in 2025. To fight it, the organizers now require researchers to pay $100 for every subsequent paper.
2. LLM adoption has increased researcher productivity by 90% (there’s a recent paper in Science).
3. The number of papers is becoming far too high. Submissions to arXiv have risen by 50% since 2022.
4. There are simply not enough reviewers. Plus, many scientists no longer want to invest precious time in it for free.
5. We can’t easily identify AI-made papers from the genuine ones.
__
Important words from Paul Ginsparg, a co-founder of arXiv:
“AI slop frequently can’t be discriminated just by looking at abstract, or even by just skimming full text. This makes it an “existential threat” to the system.”
Basically, we’re getting closer to the tipping point.
📍 Many professors blame the AI.
But the problem is likely elsewhere:
1. Without a sufficient number of papers, many PIs can’t get funded. They have to prove their credibility to reviewers. Their proposals have to rely on prior publications. In many countries, there are some informal (or even formal) expectations for how many papers a group with a certain size has to publish to survive (funding-wise).
2. Our students / postdocs need papers if they want to be hired in faculty roles. Yes, some departments hire people with few publications. But the majority still want to ensure their faculty can get funded. If funding is partly a function of papers, this is used in decision-making.
3. The number of papers is important if you want to get high-level awards. Many of them are not given because you published one paper (even if it’s great). They are given because you made a meaningful CONTRIBUTION to the field. How do you make it? Publish more papers.
4. Tenure promotions in many places take the number of your papers into account (often indirectly). Your tenure may get delayed if you don’t publish enough. Not everywhere, but for many mid- to low-ranked universities this story is more or less the same.
+ There are many more to mention.
📍My opinion:
Much of this is rooted in how funding is distributed.
There is a strong correlation between the requirements at a university and the funding acquisition criteria.
If funding were based ONLY on the quality of published papers, universities would hire people for the quality of their science. If funding agencies strongly discouraged publishing too many papers, universities wouldn’t expect numbers from faculty during promotions. And some supervisors wouldn’t pressure students and postdocs to publish unfinished studies and low-quality data.
Yes, we need good detectors of fake papers.
But we also need the right policies and better funding allocation criteria.
A great piece on causality (TLDR: read Hume). One thing natural scientists overlook as evidence of causation is the constructive approach (aka engineering): if you can build a thing that does a thing (and does it again, and again), that's a pretty tight case for causality!
Fun, but I'm stuck:
on one hand: humans are "special" in perceiving time, and it started with being able to anticipate the light/dark cycle
on the other hand: you are describing circadian rhythms, which are explicit, entrainable biochemical clocks, found across kingdoms of life
David @dav_robbe is done looking for clocks in brains.
Henri Bergson had it right, he says. We measure time by our actions and the flow of the world around us, and David has a treadmill and rodents to prove it! (Well, not prove prove, but, you know...)
https://t.co/UThLZOH5gt
The @UofCalifornia is advising scientists applying for residency not to publish in @eLife because it doesn’t have an impact factor, despite zero evidence this matters, and proving once again that the biggest problems in science and academia are entirely of our own making.