Excited to share our work on RAX! We scale online exploration for agentic robotics, turning experience into reusable programs and skills without model finetuning.
Great working with @RunhanH, @xczhangxx, and the whole team!
Robotics has spent years scaling demonstration data and model size. What happens when we scale EXPLORATION for robot agents?
We're incredibly excited to share RAX, an agentic robotics system that learns by scaling online exploration.
A coding agent connects directly to the robot’s perception and control APIs, learns from feedback, and builds programs that perceive, plan, and act. The model stays frozen. As exploration scales, the agent improves its programs and builds up reusable skills.
The results:
• ZERO teleoperation or action demonstrations on real robots—from insertion with 0.1 mm clearance and air-fryer manipulation to deformable objects and long-horizon mobile whole-body control.
• +37 percentage points on average over leading learned policies across five simulation benchmarks: RoboDojo, BEHAVIOR-1K, HumanoidArena, DexJoCo’s bimanual tasks, and LIBERO-Pro.
• One framework spanning single-arm, bimanual, dexterous, humanoid, and mobile robots, with new embodiments connected through APIs.
The craziest part: on each real-world embodiment, going from scratch to mastering the tasks took roughly two hours. No teleop. No model finetuning.
We’re open-sourcing the full framework AND every experiment session. We can’t wait to see what people build with it!
Project + sessions: https://t.co/O04Z5PUgqY
Paper: https://t.co/sd66qnYZWB
GitHub: N
Project fully led by @RunhanH and @xczhangxx who are absolutely awesome.
How it works, experiments, and robot videos below 🧵
(1/N)
A robot reaches for a cup. The cup moves. Can it still finish?
Introducing LIBERO-MAX: 8,000 paired cases of mid-task change.
Across all 14 tested robot policies, success drops by 11.0–25.7 percentage points.
https://t.co/YdESaOW57u
1/12 🧵
Practice makes perfect. A truly agentic robot shouldn’t just know what to do. It should also figure out how to get better.
What if a robot could watch a demonstration, figure out what it needs to practice, and learn how to get better through practice?
Introducing RPG: Guided Self-Improvement for Embodied Agents, a real-to-sim-to-real pipeline that turns real-world demonstrations into targeted practice.
RPG reconstructs practice tasks from demonstrations, uses demo videos to guide skill improvement, and continually updates a shared skill system from failures.
On real robots, RPG achieves 30/30 successes across 3 tasks. In simulation, it reaches 95.0% success across 22 manipulation tasks after 15 rounds of self-improvement.
Demo → Reconstruct → Guided Practice → Self-Improve → Go Real
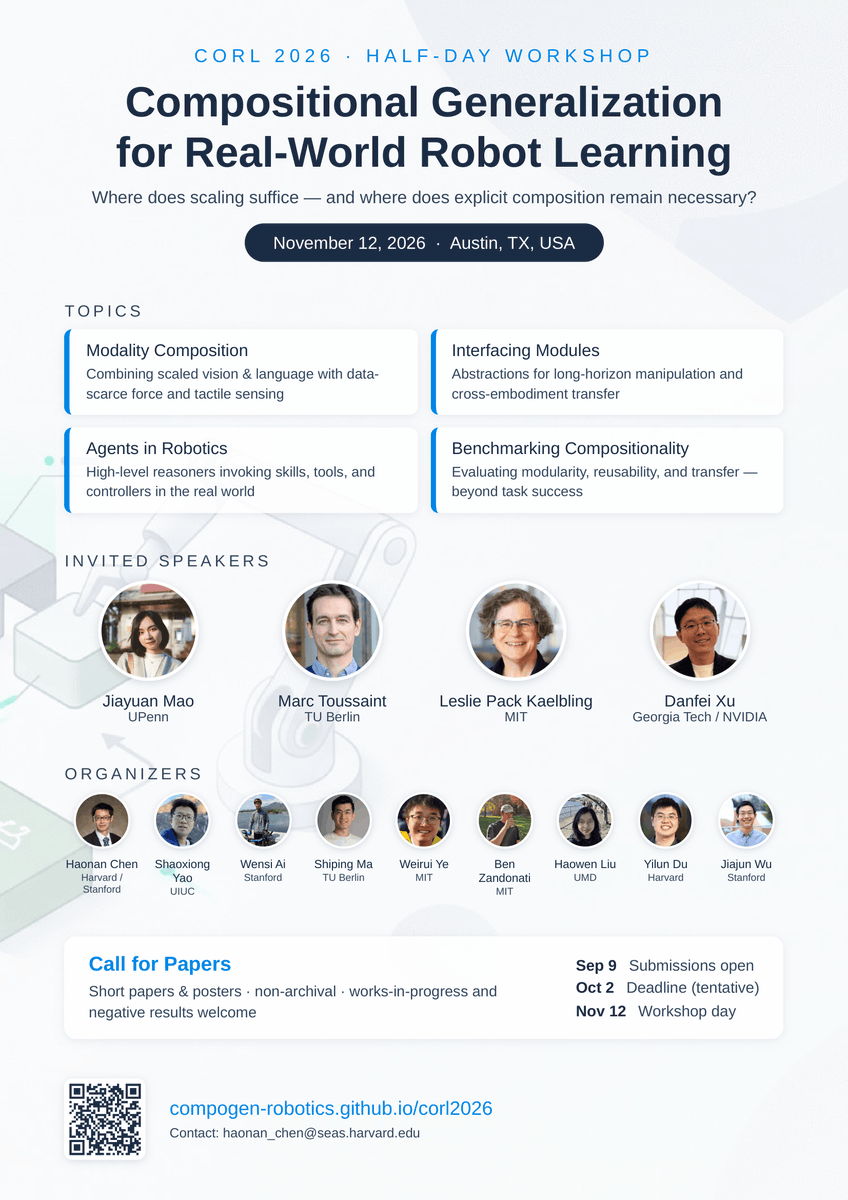
Excited to be organizing the Compositional Generalization for Real-World Robot Learning workshop at CoRL 2026!
We’re looking forward to bringing together researchers working on compositionality, generalization, and real-world robot learning.
Please consider submitting your work and joining us at CoRL 2026!
https://t.co/pDOuOckGcz
Co-organized with @ShaoxiongYao, @wensi_ai, Shipping Ma, @Weirui_Ye, @benzandonati, @HaowenLiu, @du_yilun, @jiajunwu_cs
📣 CALL FOR PAPERS 📣
𝗖𝗼𝗥𝗟 𝟮𝟬𝟮𝟲 𝗪𝗼𝗿𝗸𝘀𝗵𝗼𝗽 𝗼𝗻 𝗠𝗲𝗺𝗼𝗿𝘆 𝗳𝗼𝗿 𝗥𝗼𝗯𝗼𝘁 𝗙𝗼𝘂𝗻𝗱𝗮𝘁𝗶𝗼𝗻 𝗠𝗼𝗱𝗲𝗹𝘀 @corl_conf
📅 Submission deadline: September 24, AoE
📢 Notifications: October 12
📍 Workshop: November 12 in Austin
📝 Submit: https://t.co/DVE3ZfPQ6C
Robots operating over long horizons need to remember: which drawers they have already opened, why the last grasp failed, or how a particular user likes their kitchen arranged. But what should memory mean for a robot? What should it store, and how can we tell whether it truly helps—or whether we have simply given the model a larger context window?
If you are working on or thinking about these questions, we would love to see your work. Our goal is to map the design space for memory in robot foundation models, and 𝘄𝗲 𝗮𝗰𝘁𝗶𝘃𝗲𝗹𝘆 𝗶𝗻𝘃𝗶𝘁𝗲 𝗽𝗼𝘀𝗶𝘁𝗶𝗼𝗻 𝗽𝗮𝗽𝗲𝗿𝘀, 𝘄𝗼𝗿𝗸 𝗶𝗻 𝗽𝗿𝗼𝗴𝗿𝗲𝘀𝘀, 𝗮𝗻𝗱 𝗽𝗿𝗲𝗹𝗶𝗺𝗶𝗻𝗮𝗿𝘆 𝘀𝘁𝘂𝗱𝗶𝗲𝘀. 𝗔𝗰𝗰𝗲𝗽𝘁𝗲𝗱 𝗽𝗮𝗽𝗲𝗿𝘀 𝗴𝗲𝘁 𝗮 𝗽𝗼𝘀𝘁𝗲𝗿, 𝘄𝗶𝘁𝗵 𝗮 𝗳𝗲𝘄 𝘀𝗲𝗹𝗲𝗰𝘁𝗲𝗱 𝗳𝗼𝗿 𝗼𝗿𝗮𝗹𝘀.
Learn more at https://t.co/NWWWaRJqe4
Organized with @pgozdil@Weirui_Ye@tarikkelestemur@JNZaech@fpaissan_@ZhiyiLi02@du_yilun
#CoRL2026 #RobotLearning #Robotics #EmbodiedAI #FoundationModels