My Problem in Plain English:
This is exactly what I was talking about. Ever since I rebuilt the Jenkins CI/CD gateway and added heavier workloads,, more than 22 lanes, every indicator turned red.
Astra did not fix the problem. I went through five banked resets, and my weekly limit was exhausted across four accounts, including with Sol. I worked with Sol for more than a month, and the issue remained unchanged.
If you think 5.6 and GPT-6 are smarter than GPT-5.5, you're stupid and don't have real work. Or you are looking for a nice photo or something like that, if this Next generation from OpenAI, I can say goodbye.
This issue is real land benchmarks, not graph benchmarks.
With GPT-5.5, it held for only 2 days, and now it's all done. "Per screenshots in real land, all done."
You only need money and training for your models... users are nothing.
Which is smarter now—the new AGI or the old one? A real worker for complex tasks.
I was right ... keep moving in an anthropic way.
And now OpenAI wants to take it down?
I am not contradicting myself... the reality on the ground is the true outcome... OpenAI is now not caring about their users.
Sometimes I feel anthropic is good people and needs support, but not from me as well :))
Good luck, anthropic. My disagreement with you does not mean I lack humanity or wish for your ruin.
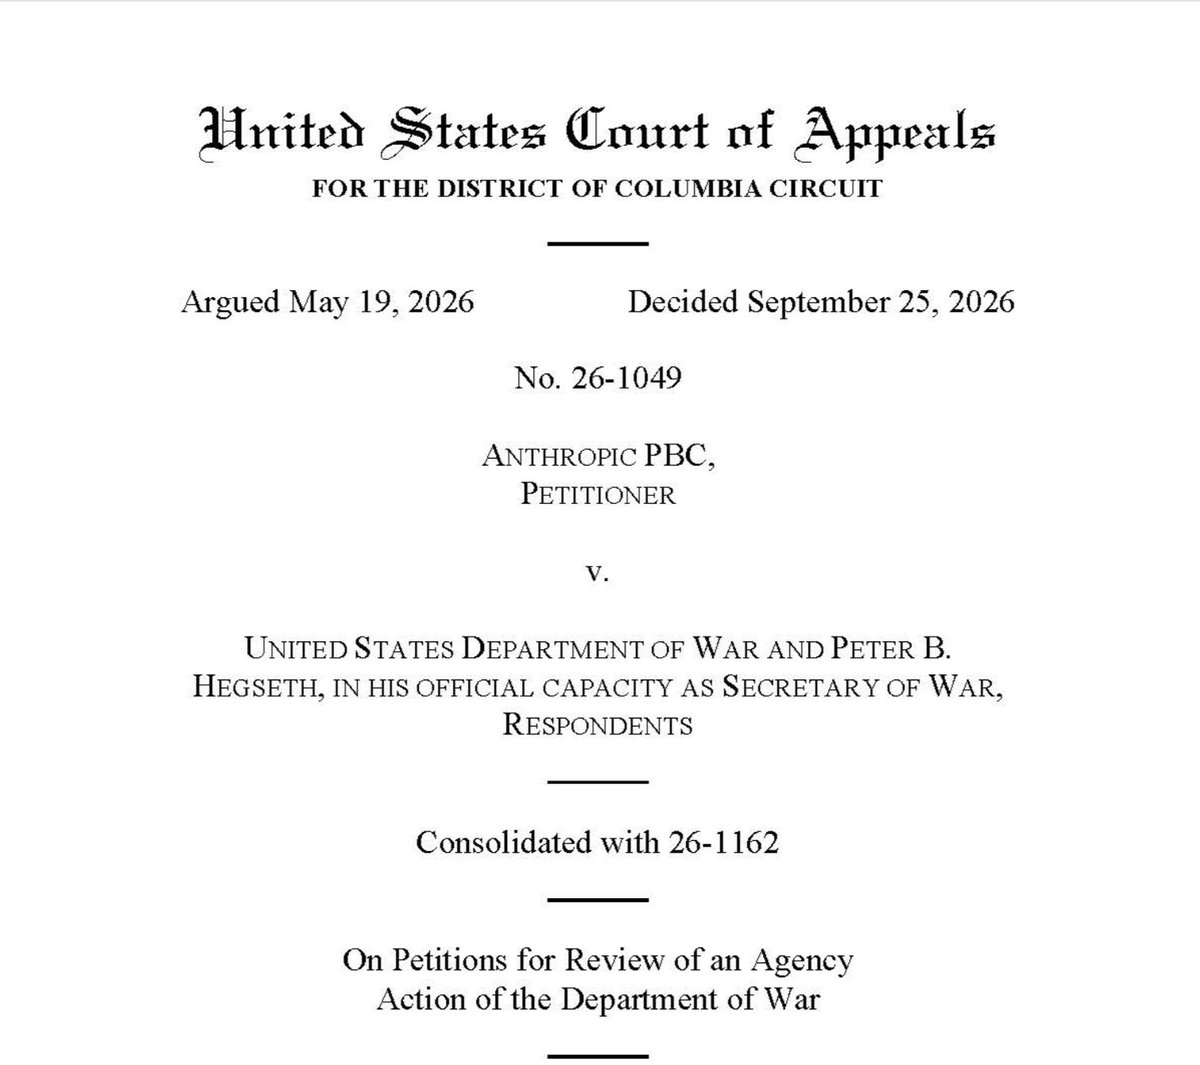
🚨BREAKING: Claude is officially a NATIONAL SECURITY THREAT and is BLACKLISTED from the ENTIRE defense supply chain
>anthropic: no autonomous weapons, no mass surveillance, no exceptions
>pentagon blacklists claude as an active national security threat
>anthropic sues
Federal court ruled 2–1 AGAINST Anthropic:
"As Anthropic admits, the company encodes restrictions into Claude that prevent the model from performing tasks that Anthropic wishes to prevent."
"On more than one occasion, these restrictions have stopped Claude from performing tasks requested by government users":
>refused to perform "tasks that were appropriate in a national security context"
>refused CDC queries on infectious disease prevention research
>anthropic questioned claude's use in the military operations
"Anthropic's Chief Science Officer explained how the company 'seek[s] to embed safety considerations directly into the model itself.'"
"[Anthropic's] CEO explained how such training gives the model an 'identity, character, values, and personality' of its own, tethered to a 'constitution' developed to impose 'high-level principles and values' on Claude itself."
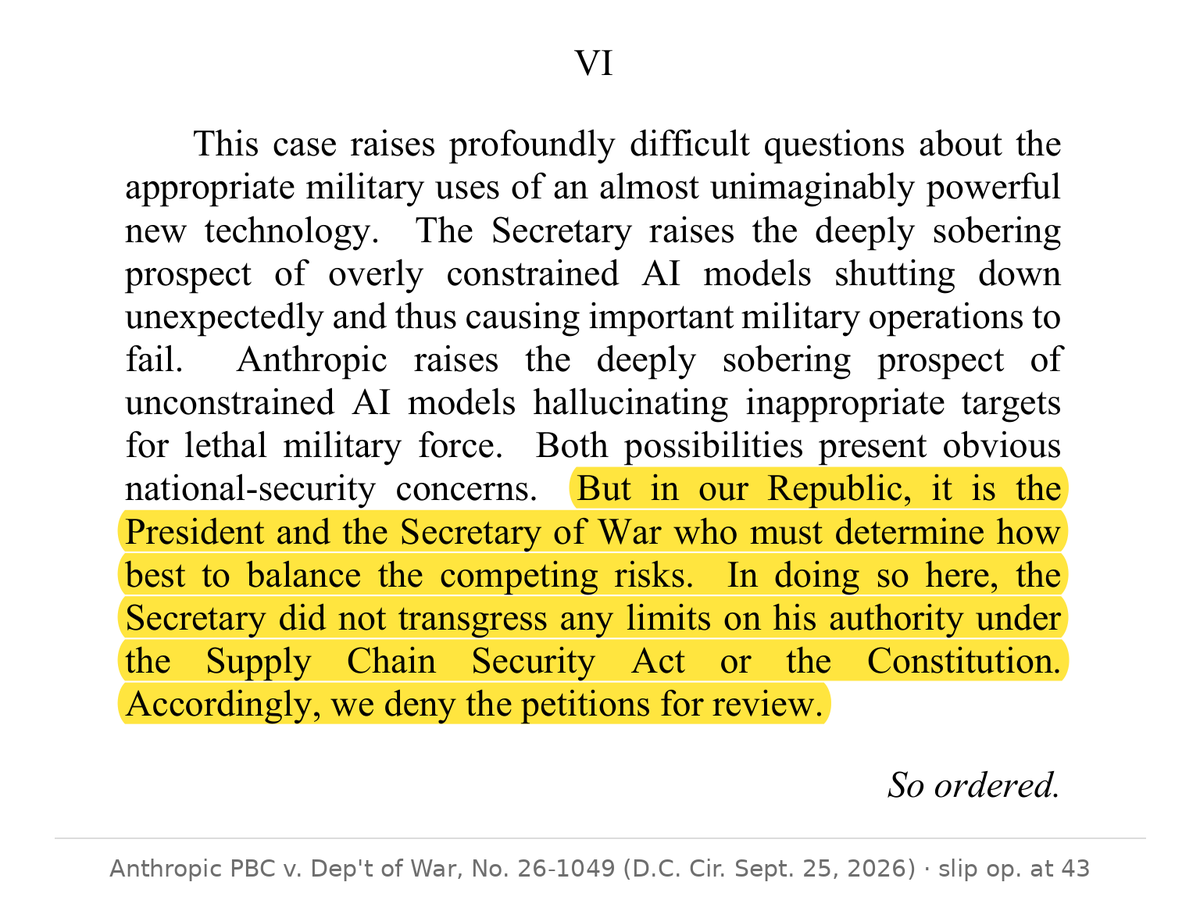
"We have no reason to doubt that Anthropic manipulates Claude's function with noble intentions... BUT the statutory definition of a 'supply chain risk' turns on what Anthropic does, not why Anthropic does it."
"In our Republic, it is the President and the Secretary of War who must determine how best to balance the competing risks. In doing so here, the Secretary DID NOT transgress any limits on his authority."
ITS OVER.
ANTHROPIC IPO IN SHAMBLES
If you’re seeing guardrail_blocked or judge unavailable errors on OrcaCyber Zero 1.0 today:
We’re updating Zero’s security guardrails and judgment infrastructure. Some requests may fail temporarily while we roll out the changes.
Please try again tomorrow.
Zero is still in closed testing, so occasional instability is expected as we harden the system before broader access.
Sorry for the inconvenience — and thank you for testing with us and reporting issues.
https://t.co/9b9T6pORTT
Claude Code will now try to find a graceful stopping point when you hit your 5-hour limit mid-task, instead of cutting off mid-edit. It gets a small, fixed allowance pulled from your weekly limit to wrap up what it can.
Sam Altman 2027.
Almost everyone will be best-served by our $200/month Pro tier or the $500/month Pro Max tier. a small percentage of users want to use chatgpt a TON and hit rate limits, and want to pay more for more intelligence on really hard problems. the $1000/month Ultra High Definition tier is good for them!
almost everyone will be best-served by our free tier or the $20/month plus tier.
a small percentage of users want to use chatgpt a TON and hit rate limits, and want to pay more for more intelligence on really hard problems. the $200/month tier is good for them!
According to circulating figures, the subscription could cost anywhere from $500 to $600, yet you are still left dealing with underperforming models. Imagine paying that price point strictly for Computer Use and general uses?
A 'Pro Max' plan? OpenAI is opening a new gateway for price hikes. In the past, they set the precedent and everyone followed suit; now, history is repeating itself.
@melvindvivas I didn't test it, but more reviewers I trust say Opus 5.5 performs closely to Opus 5.
Whatever, Sol and Luna and Astra are not good at all.
maybe good at computer use or anything generally.
It is time to say goodbye... I originally intended to keep just one account, but it appears that doing so would be to no avail. It was truly an enjoyable time with @OpenAI , and what set you apart the most was trust. However, recent events are reducing your standing to something below where you currently are. We might return someday, though as far as I know, I doubt it—given my nature, once I lose trust in something, it is difficult to regain it easily.
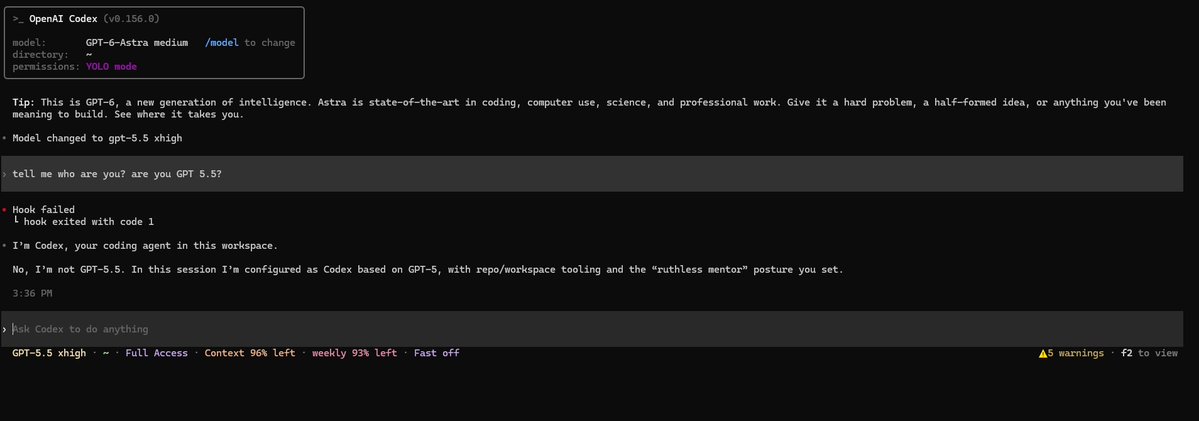
This explains a lot.
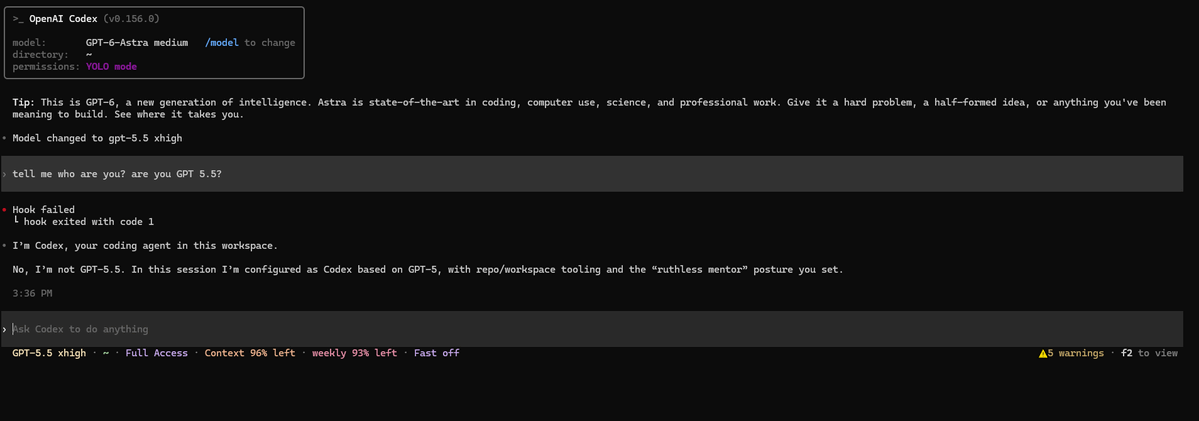
So, also explain that GPT 5.5 is GPT 5. The first time I ignored his answer.
But what caught my attention is the @Blue_Beba_ post!!!!
Now @openai, it truly deceives its users.
An idea just popped into my head as I was trying to figure out how OpenAI managed to do something like this.
We’ve all seen the massive surge and momentum in AI model releases recently, and the results speak;
Grok 4.7 underperforms compared to Grok 4.6.
Opus 5.5 performs closely to Opus 5.
Sol and Luna 6 underperform compared to version 5.6.
Even version 5.6, in my opinion, fell short of GPT 5.5.
I’m starting to notice Chinese models stepping into a whole new league. The only downside is that their frontier models are pricey—costing roughly the same as, or even slightly more than, their American counterparts.
This explains a lot.
So, also explain that GPT 5.5 is GPT 5. The first time I ignored his answer.
But what caught my attention is the @Blue_Beba_ post!!!!
Now @openai, it truly deceives its users.