@twid Even stronger most of the youth hate AI with a vengeance as they fear their studies wont be meaningful … go outside an touch gras , and discover that we, tech nerds live in a bubble …
@twid We are the minority and none of the household members want to be part of the AI craze … we the Tech nerds believe it is the best thing since … all the people I know outside the ones in Tech hate / do not want to be part of this made course.
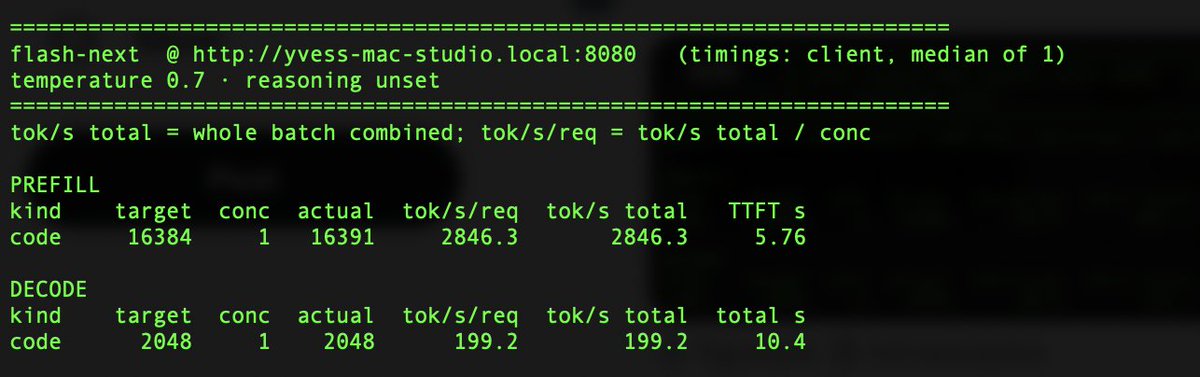
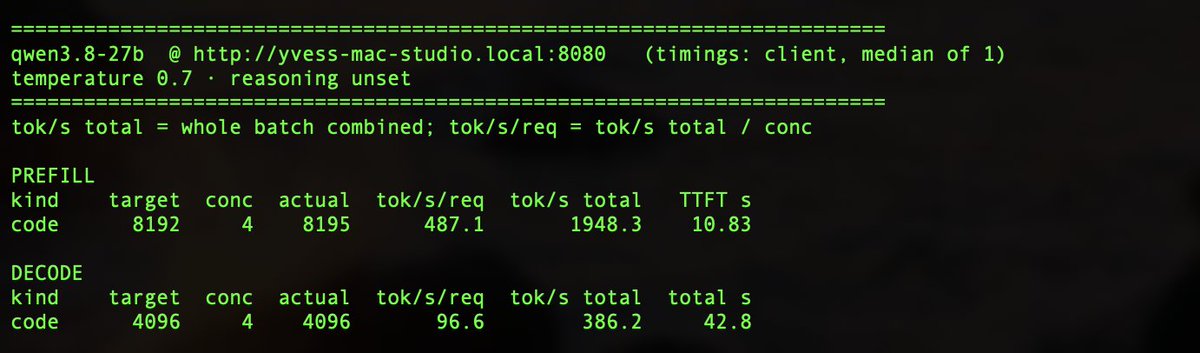
@ivanfioravanti That is why I never trust magical 2x breakthroughs. Having said that, if it works in real live and the speed gain holds up, than, good. Reality is that in many cases the faster t/s lead to higher times to compleet the same task as the model looses intelligence / token
Pushing Qwen Next Flash on my Mac Studio M5 Ultra (256GB) 🚀
🔥 17 concurrent requests (16 actively decoding)
⚡ 453 tokens/sec median aggregate decode
📈 ~438 tokens/sec sustained right now
That's roughly 27–28 tok/s per request, with all 16 decoding in parallel.
And the interesting part? This isn't a synthetic benchmark. It's a real workload, running continuously.
Apple Silicon + MoE models are a pretty fascinating combination. 🍎
@seapy After the failed benchmarks I would not have expected anything less. The performance numbers you posted where lower than my 2 M5Max … and I can asure you even my 64 core GPU M5U is faster than those 2 … and way faster than my 2 DGX Sparks (sold)
@seapy I was also referring to the prefill numbers I know sparks are good at it, but not beyond GPU space, even if it are 4 Anyway I replaced the 2 DGX sparks with a M5U 64 core GPU, it flies on Tenserfold, 2 with 6 cables is next, that will be the best price performance for my case.
@cem2ran@krunkosaurus For dense model 1.8 faster prefill and around 1.5 faster decode. MoE’s will be less but it will be faster than 1 512 … you loose around 10GB though. In scaling as you have 2.4GB/s memory, who knows. 2 64 core and cheaper too is what I will do.