Had a great time presenting work from @Huawei’s Noah’s Ark Lab and our Montreal NLP team at #CoLLAs2026! We’re hiring — if you’re around and interested in long-context models, memory, post-training, or agentic AI, let’s connect and chat.
If you claim to support human rights yet can’t bring yourself to show solidarity with those fighting for their liberty in Iran, you’ve revealed yourself. You don’t give a damn about people being oppressed and brutalised so long as it’s being done by the enemies of your enemies.
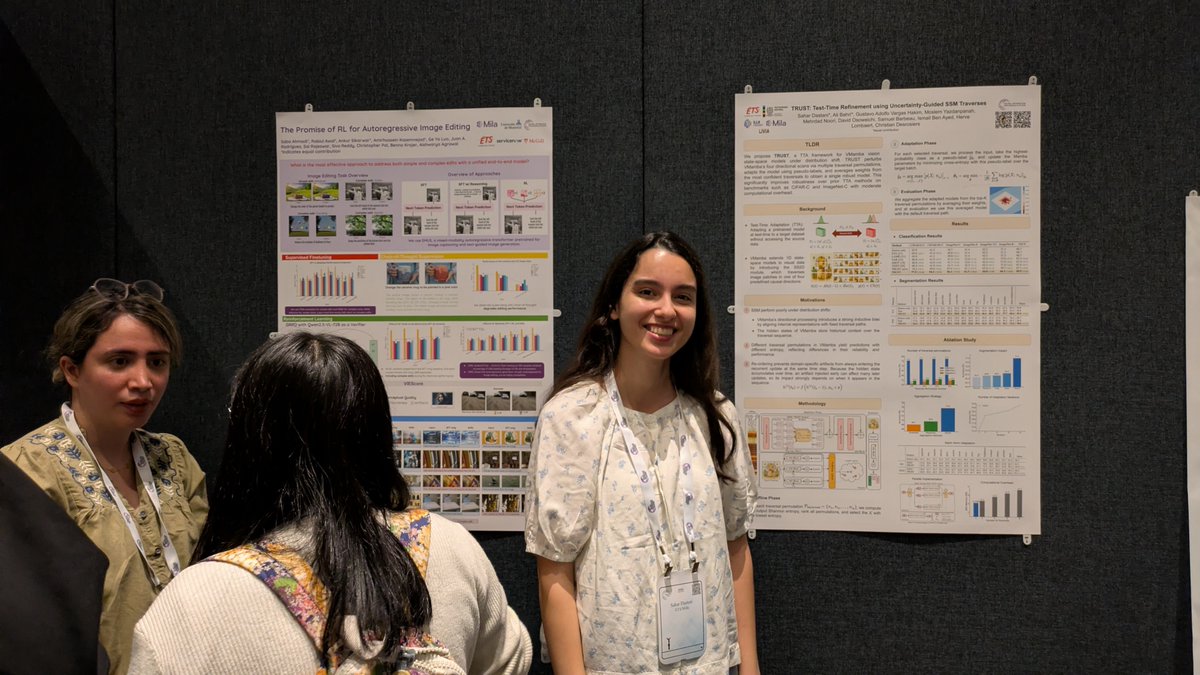
Alongside @NeurIPSConf in San Diego, the satellite conference NeurIPS Mexico City is taking place, with several Mila student-researchers taking part. Two of them presented their research today.
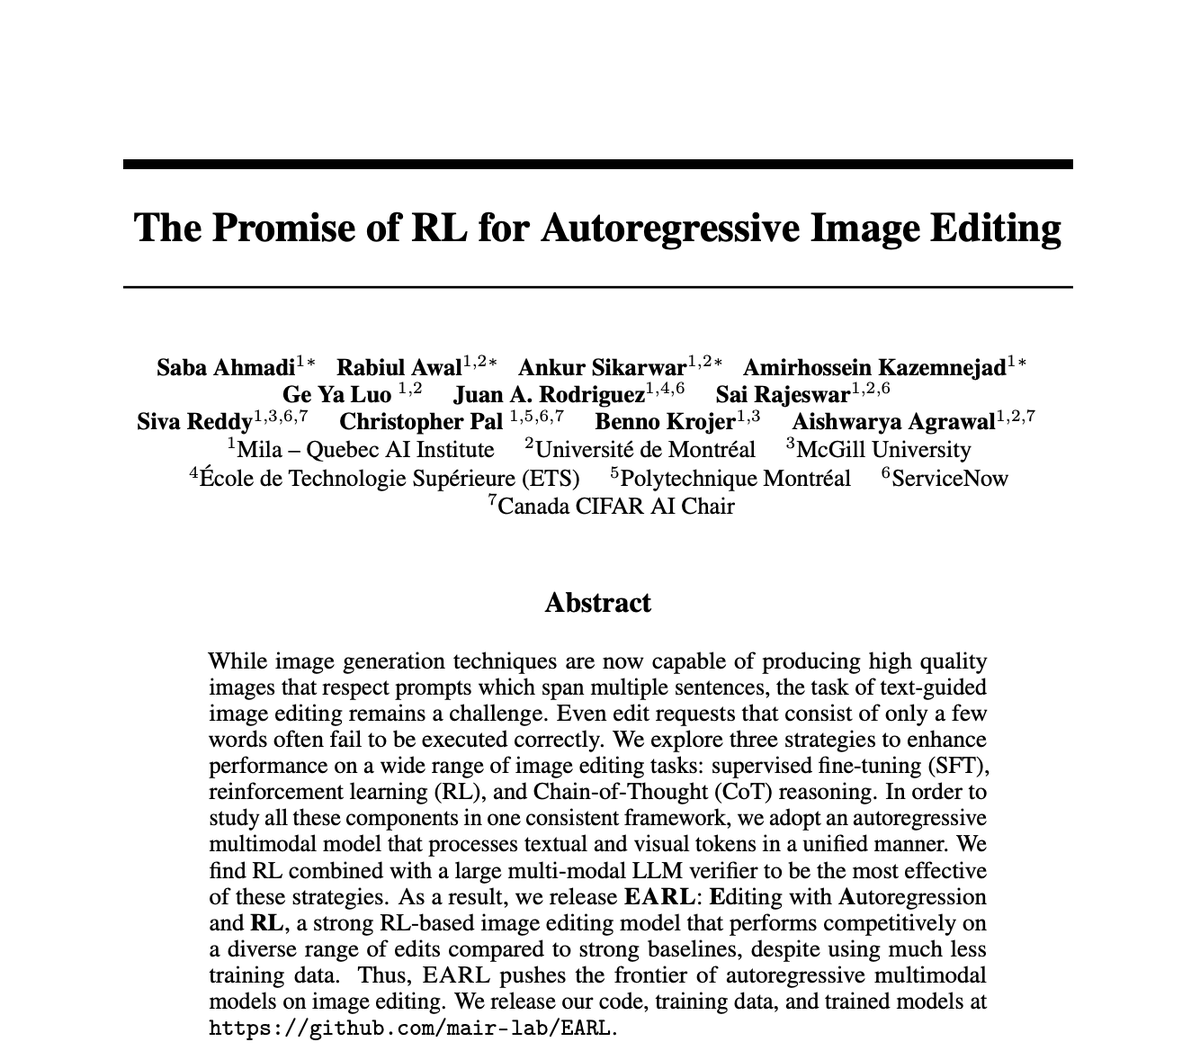
SaharDastani (@sonia_dt98), PhD student at ETS/Mila, presented “TRUST: Test-Time Refinement using Uncertainty-Guided SSM Traverses” and Saba Ahmadi (@Saba_A96), affiliated researcher at UdeM/Mila, presented “The Promise of RL for Autoregressive Image Editing.” Congratulations!
We built a new 𝗮𝘂𝘁𝗼𝗿𝗲𝗴𝗿𝗲𝘀𝘀𝗶𝘃𝗲 + 𝗥𝗟 image editing model using a strong verifier — and it beats SOTA diffusion baselines using 5× less data.
🔥 𝗘𝗔𝗥𝗟: a simple, scalable RL pipeline for high-quality, controllable edits.
🧵1/
Introducing nanoAhaMoment: Karpathy-style, single file RL for LLM library (<700 lines)
- super hackable
- no TRL / Verl, no abstraction💆♂️
- Single GPU, full param tuning, 3B LLM
- Efficient (R1-zero countdown < 10h)
comes with a from-scratch, fully spelled out YT video [1/n]
🚨 Excited to introduce PairBench! 🚨
💡 TL;DR: VLM-judges can fail at data comparison!
✅ PairBench helps you pick the right one by testing alignment, symmetry, smoothness & controllability—ensuring reliable auto-evaluation.
📄Paper: https://t.co/R7XylscvB3
🧵 Thread: 👇
VinePPO, a straightforward modification to PPO, unlocks RL’s true potential for LLM Reasoning.
It beats RL-free methods (DPO and RestEM) and PPO, surpassing it in less steps(up to 9x), less time(up to 3x), and less KL with half memory.
Time to rethink RL post-training🧵: [1/n]
Can one achieve SOTA LLM performance at a much lower bitsize (=>memory/inference costs) than current (post-training) quantization? YES! - by training ternary LLMs - a "sweet spot" between underperforming binary and costly ful-precision ones.
Happy to announce our recently open-sourced Spectra suite of 54 models - 9 sizes (99M to 3.9B), 6 models per size: TriLMs (1.58bit), FP16 Float, a few quantized baselines - @cerc_aai lab joint work with @NolanoOrg presented last week at ICML's FM-WILD and Scaling workshops https://t.co/wnu8USI1jW; paper: https://t.co/aEraZQWfzp.
We recently released VisMin -- a vision-language benchmark for Visual Minimal-Change Understanding. The benchmark is designed to assess VLMs’ fine-grained understanding of objects, attributes, counting and spatial relations.
🚨 Open-source AI community - stop building everything from scratch, let's build on each other's (and your own) work over time - continually, as we should! Don't waste previoius compute and human effort!
See https://t.co/jugB0DW4KZ - simple & useful tips on how to just keep training foundaiton models on new data without forgetting or performance degradations w.r.t. usual large-scale training!
Kudos to our amazing team, @kgupta24@benjamintherien@ai_phd@MatsRichter@QuentinAnthon15@TLesort@ebelilov !
Interested in seamlessly updating your #LLM on new datasets to avoid wasting previous efforts & compute, all while maintaining performance on past data? Excited to present Simple and Scalable Strategies to Continually Pre-train Large Language Models! 🧵https://t.co/hlpWC03VJA 1/N
@Erfan_theSecond البته فکر کنم اوایل ۹۷ درخواست داده که اون موقع دلار هنوز گرون نشده بود.
البته جلوی دزدیهای اینا که عددی نیست ولی اون موقع با این پول میشد ۴۰ تا پاترول خرید احتمالا.
من بهار ۹۷ پژو پارس رو ۳۷ تومن فروختم.
1/9 Our(@aagrawalAA) latest research(https://t.co/bXDDWigE0W) examines reference-free metrics for automatic evaluation of image captions: CLIPScore (Hessel et al., 2021) & UMIC (Lee et al., 2021). Known for achieving high correlation with human judgment, are they really robust?