LLMs cannot reason.
Despite their impressive capabilities, all LLMs, including OpenAI o1, are still fundamentally limited by design constraints that make them incapable of true, open-ended reasoning.
Let's break it down. 🧵 (1/5)
🚀Excited to speak at Open Data Science Conference Europe 2024 in London tomorrow 6th Sep at 10:30 on "Exploring Multimodal AI beyond Vision and Language."
Join me to explore multimodal AI's potential across six disciplines!
📍 Novotel London West
👉 https://t.co/vtM671z1e7
#ACL2024 was great. But very few papers were asking hard scientific questions. A lot of “LLM engineering”. In particular, university labs should really defocus on this type of engineering as industry labs, though not publishing every minute detail, are doing way more advanced “LLM engineering” work. Academic reviewers reviewing academic work of this type contribute very little to scientific progress. “LLM engineering” is very seductive - but it becomes obsolete very quickly if you are not looking at the core problem. A few percentage increase on a benchmark can be completely washed out by a bigger model with more training data or another round of RLHF. So ask the hard questions - ask the WHY not just the how.
This afternoon @ecir2024, we are going to present our paper “Simulated Task Oriented Dialogues for Developing Versatile Conversational Agents” in the QA & Conversational session. We will share with you the insights we obtained in generating synthetic dialogues. #ecir2024
It gives us great pleasure to pre-announce the 8th CHiME Speech Separation and Recognition Challenge (CHiME-8) that will launch in February 2024.
CHiME-8 TASKS includes:
Task 1 - DASR
Task 2 - NOTSOFAR-1
Task 3 - MMCSG
Please check https://t.co/rhQiJtrdWe
Introducing COLM (https://t.co/7T42bAAQa4) the Conference on Language Modeling. A new research venue dedicated to the theory, practice, and applications of language models.
Submissions: March 15 (it's pronounced "collum" 🕊️)
Join us for ASRU's satellite event - the Workshop on Speech Foundation Models & Performance Benchmarks (SPARKS), on Dec 16th, 2023, in Taiwan.
📌 Paper Submission: Oct 19th
🔗 Webpage: https://t.co/ctPGLbJprp
Tip: When registering for ASRU, tick the SPARKS option. #ASRU
``One model to rule them all ? Towards End-to-End Joint Speaker Diarization and Speech Recognition. (arXiv:2310.01688v1 [https://t.co/3pcQCkeyAA]),'' Samuele Cornell, Jee-weon Jung, Shinji Watanabe, Stefano Squartini, https://t.co/oxNpZwUTx2
@shinjiw_at_cmu@WavLab has released an Open Whisper-style Speech Model (OWSM), perhaps the first attempt in academia to reproduce OpenAI's Whisper from scratch using public data and open-source toolkits. OWSM even supports more translation directions and can be more efficient.
Mistral 7B is out. It outperforms Llama 2 13B on every benchmark we tried. It is also superior to LLaMA 1 34B in code, math, and reasoning, and is released under the Apache 2.0 licence.
https://t.co/krGs0xwbLH
If you ever try to install Kaldi on a Mac with Apple silicon, feel free to check out this new section 1.1.1 in my ASR blog: https://t.co/11FnKgcADr
#Kaldiinstallation#macM1
💡New preprint on non-autoregressive sequence-to-sequence voice conversion (non-AR seq2seq VC) ‼️
We made seq2seq VC training fast and simple, and it can work on a 5 min parallel dataset!
Demo: https://t.co/chNvaMUfwu
Code: https://t.co/0c0WjX2Ivp
Paper: https://t.co/hkuM0dG2Ct
Check out our new paper on foreign accent conversion (FAC)! Accepted to APSIPA ASC 2023 🇹🇼
Demo: https://t.co/q4kLFpXxEy
Code: https://t.co/0c0WjX2Ivp
Paper: https://t.co/bi5qEcgVwM
We found none of the three most recent FAC methods is superior to the other 🤔
A further opportunity to join my team. This time as a Gr8 >>Senior Research Fellow<< 3-year post with possibilities for extension.
https://t.co/o551sbPnkf
Pls, RT
Interesting #INTERSPEECH2023 paper (I think ;-)) on using MOS scores vs side-by-side preference tests when comparing TTS systems.
How to choose? Is one more robust/sensitive than the other?
Ever wondered about that? Here is the paper:
https://t.co/K9NS3qe8XM
#NLProc#GoogleAI
+++ PostDoc position+++
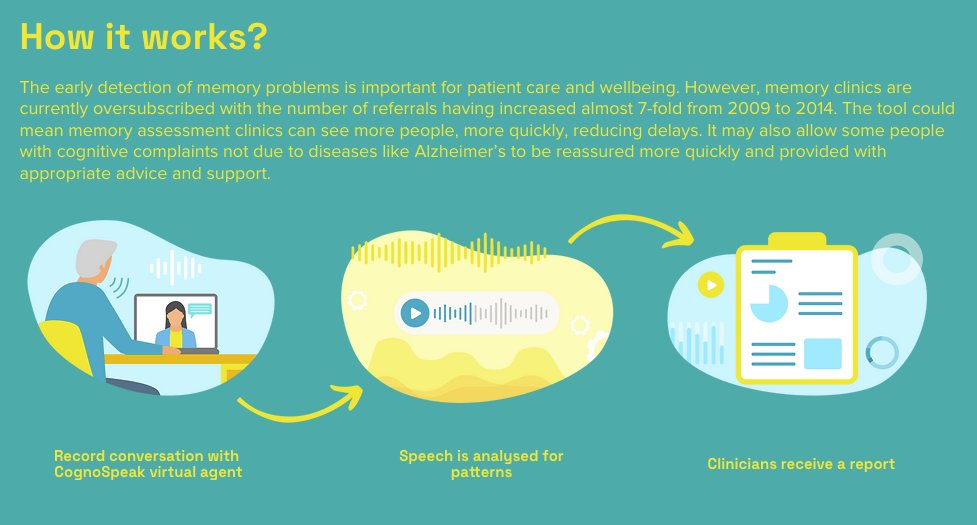
Come work with me and my team @shefcompsci on the detection of cognitive decline on the @CognoSpeak project: https://t.co/TsokDwHNou (please RT)