Why the days of 90% software margins are totally gone
“I think basically almost no company today has software margins anymore. The 90% margins-plus that you used to see in Silicon Valley are basically gone.
Today you have applications, models, infrastructure, cloud and NVIDIA. When a customer pays a dollar at the top of the stack, it has to flow through a lot of different layers.
There is a lot of opportunity to make a lot of money, but you are splitting it across a lot of layers in the stack. Modal has an opportunity long term to get to 40%, 50%, 60% margins, but we are never going to get to software margins.” @bernhardsson
Love to hear your thoughts @poyark@GavinSBaker@jaminball@afc
20-latek z Bieszczad pozyskał 32 mln zł na swój startup AI, m. in. od współzałożycieli Ubera i Snowflake’a. I wcale im się nie dziwię.
Szymona miałem okazję poznać ponad rok temu w Krakowie, dzień przed jego wylotem do San Francisco. Właśnie dostał się do Y Combinator, a przed nim była jeszcze matura z polskiego. Mimo to znalazł czas, żeby porozmawiać.
Już wtedy uderzyło mnie, jak dojrzały jest jak na swój wiek. Świetnie rozumiał niuanse technologii i biznesu, miał dryg przedsiębiorcy: duże ambicje, ale twardo na ziemi. Sam bym w niego zainwestował.
Jeśli jakaś umiejętność na pewno pozostanie kluczowa w świecie AI przez najbliższą dekadę, to zdolność przekonywania do siebie ludzi. Nie każdy zaufa 20-latkowi z Polski. Szymonowi zaufali. I dziś, bez kompleksów, buduje globalną firmę z Warszawy.
Inwestorów przekonali programiści. 1 października TesterArmy @e2e opublikował e2e, otwarty framework do testowania aplikacji. W pierwszym miesiącu pobrano go ponad 1,3 mln razy, z czego 587 tys. w samym ostatnim tygodniu października. Do tego ponad 12 tys. gwiazdek na GitHubie i 60 zewnętrznych kontrybutorów.
To odpowiedź na pytanie, które Szymon słyszał najczęściej: czym różnią się od dziesiątek innych startupów robiących testowanie z AI. – Inwestorzy zobaczyli, że programiści sami wybierają nasze narzędzie – mówi.
e2e sprawdza aplikację tak, jak zrobiłby to człowiek, i wyłapuje błędy, zanim trafią do użytkowników. To odpowiedź na nowy problem: agenci AI piszą kod szybciej, niż zespoły są w stanie go zweryfikować. – Wchodzimy w erę verification engineering – mówi Szymon. Testerzy nie znikną, ale zamiast łatać skrypty, będą opisywać, co ma działać, a agent to sprawdzi.
Framework zostaje darmowy. Firma zarobi na infrastrukturze do testów w chmurze (start w 2027 roku) i wdrożeniach dla dużych firm, podobnie jak Vercel. Pieniądze z rundy pójdą głównie na ludzi w Warszawie i San Francisco.
– Ta runda to przede wszystkim odpowiedzialność, bo ludzie postawili na nas pieniądze i zaufanie – mówi @SzymonRybczak . Coraz więcej czasu spędza na rekrutacji i rozmowach z klientami, ale wciąż trzyma się blisko produktu. – Uczę się bycia CEO w biegu.
Cały wywiad z Szymonem na https://t.co/g2XWOoYCvZ
Link w komentarzu.
This is f*cking insane. SpaceXAI engineer Nick Miller (ex-Cursor):
"99% open one Grok Bot and call it automation.
I run 30+ bots with a Chief of Staff, PM, QA, and 20+ workers".
In this 30-minute demo, he walks through turning a single bot into a team that actually coordinates.
Grok Bot -> Chief of Staff -> PM -> QA -> Workers
Adding bots doesn't give you a team. Handoffs and verification do.
Worth more than most $800 agent engineering courses.
Bookmark it and watch it today.
Then read Grok Bot Engineering guide below ↓
🚨 The AI BUBBLE is starting to look like a MUCH bigger problem than overpriced tech stocks
More than $2 TRILLION was on track to be wiped off the Nasdaq 100 in October, and now Wall Street is getting nervous about something far more dangerous: DEBT.
Blackstone expects Anthropic to receive a JUNK credit rating after its IPO, according to the FT, even as the company plans more than $800 BILLION in computing investments through 2045.
Amazon is burning through cash. Alphabet just lost roughly $500 billion in market value in ONE DAY. And CoreWeave's borrowing costs have reached levels that would make most companies sweat.
Here's where things get crazy.
AI companies are borrowing BILLIONS to buy chips from suppliers who are increasingly helping finance the very customers buying those chips.
That's a LOT of money moving around the same circle.
And the entire industry is just betting that future AI revenues will eventually justify the enormous costs of building all this infrastructure.
Nobody is even questioning whether AI is actually useful.
They're rather questioning whether the spent TRILLIONS to build it will ever make returns.
And if the debt markets lose confidence before those profits arrive, this could get ugly VERY quickly.
Source: MarketScreener, Investing[dot]com, Bloomberg / Writer: Oliver
Chinese models run 112 times cheaper than Anthropic for every million tokens.
Chamath broke it down on CNBC: Anthropic's "barrel of intelligence" runs $56, OpenAI $26, Meta $1.50, xAI and Google $1, and Chinese models $0.50.
That gap amounts to the steepest commodity curve in the recorded history of technology.
Oil needed 40 years to compress that way. Semiconductors needed 20. AI inference is getting there in months.
The firms priced at $26 and $56 aren't careless. They're gambling that trust, safety and enterprise ties keep the markup in place long enough for their costs to fall.
The timeline is the one thing they can't bet on. The $0.50 model is a working product.
Interested in AI?
Follow @FeliciaRios_ and never fall behind.
I track ChatGPT, Claude, and how every new agent is changing how we work and think, then hand you the pure signals.
Autonomiczne walce drogowe. Budimex jest pierwszą spółką w Europie, która wdraża takie rozwiązanie. Montujemy na maszynie kamerę, starlinka, oprogramowanie i z walca którym jeździł człowiek robi się maszyna autonomiczna.
I spent 48 hours in SF hanging out with billionaires, data labs and AI founders and execs running $1B to $100B companies.
My observations:
1. Sooo MANY stories of data brokers making like $2M a WEEK selling company data to labs. I can't tell if it's the beginning or a bubble, and I kept wondering which niches are left. Digging into it actively.
2. At dinner, someone asked the table, "If a new model drops next month, does your company get better or worse?" HALF the table went quiet! I think that's the best question to ask about any AI startup right now.
3. The bar people talk about now is hitting $1B in revenue in 12 months (I guess that's the new unicorn?). What I didn't hear much about is retention. AI revenue can come in fast and leave fast, and I think we're going to see a lot of stories of AI companies with huge revenue and terrible retention.
4. It's pretty clear we're living through the reinvention of the computer. The model is the CPU, the harness is the operating system, and skills and plugins are the apps. Thinking about it that way makes it easier to see where the whitespace is.
5. We're maybe 12 months from an agent that can watch you work for a week and then do your job without any instructions. The screen recording plus agent memory plus local model combination makes this possible right now.
6. Agent harnesses feel like the new GPT wrappers, in a good way, especially vertical ones. The best teams I talked to treat the model as swappable. One founder walked me through routing different models to different jobs: one for taste and visuals, a cheaper one for the everyday stuff, another for text.
They use prompts they can move across models over fine-tuning, and A/B test the output on what users actually do with it: do they edit it, export it, share it? A vertical harness is basically four things: the connectors for that industry's data, evals written by people who know the work, rules for what the agent can and can't touch, and a clean screen for a human to review. The model is maybe 20% of it.
7. There's a lot of reverse engineering going on/cloning going on more than I've ever seen. People are decompiling software and rebuilding it with agents, and someone showed a suite of like 10 apps that are worth $5B+ each all that he cloned open source. Me and everyone are still thinking through what it means when software gets this easy to copy.
8. My guess is the value moves to data. If the software can be rebuilt quickly, what's worth paying for in a legacy SaaS company is the years of customer data and workflows inside it. Some SaaS companies are secretly data companies.
Gets me thinking about how do you truly value data for this saas companies? Like if we were buying these dying saas companies at 2x ARR before (as example), maybe there is a better metric. Idk, just thinking out loud here.
9. It feels like a good chunk of legacy software won't make it to the agentic era, especially anything built around people clicking through a lot of screens.
10. Every company I talked to wants to pipe its internal data into one place and expose it to agents through MCP. Then they look at the data and realize it's a mess: five versions of the same customer, old Slack channels, PDFs nobody can search. Cleaning that up feels like a big consulting opportunity!
11. A lot of founders are building the basic building blocks for agents: APIs, data layers and tools. Some of the companies I saw barely have a UI because the main user is an agent. I really believe the startups that build primitives to this agentic era will do extremely well. Building blocks is the best way to think about it.
12. Labs can get plenty of training data, but it's harder to get real examples of agents failing inside companies. Whoever has those logs has something valuable.
13. Someone running a big consumer company told me the next fight is over memory. The model that remembers the most about you wins, and the smartest model matters less than people think.
14. Physical AI came up a lot. Astra I think was the first model that got people into AI can actually do CAD, and I think a lot of people are thinking what does vibe manufacturing really look like. The line I keep thinking about came from a robotics founder: the hardest problems in AI are deployment problems now, not research problems. Their robots work on their own, call a human when they get stuck, and every one of those calls becomes training data.
15. Cybersecurity companies are having a moment and are actually cool companies to build now, especially the ones that clean up after a breach. Every agent with access to your systems is a new door into your company, and a lot of those doors were left open.
16. Some startups are worth more dead than alive now. A shutdown company with 5 years of Slack, email and code can get paid for licensing all of it. I wouldn't be surprised if founders start factoring that into when they shut down.
17. People are starting to talk about monetizing the agent web. It feels really early, but when the most popular user of the internet is an agent, what startups should you be building?
18. I think agent insurance is coming. Once an agent makes an expensive mistake, insurers will want audits before they cover anyone.
19. Several people said the hire they want most is someone with taste who can write evals. The models are getting good at generating ideas, so the hard part is judging which ones are good.
20. New trend I observed: startup raises VC, uses venture dollars to become a creator, startup fails, founder falls back on being a full-time creator and incubates other products bootstrapped.
21. Getting SIGNIFICANT distribution is HARD right now. Founders are sponsoring buses, buying billboards like crazy and throwing parties with famous DJs to get noticed. Kinda feels dotcom era in that sense.
Attention is what's scarce! The growth guy going viral sharing his UGC strategy from Wispr Flow is a good example. It's the sauce everyone wants, and I truly believe there are probably only 50 people on the planet who know how to scale these types of businesses efficiently in this era.
Always good to get that dose of SF. I felt sooo lucky to have such an incredible trip during such an incredible time in building businesses. Surreal in so many ways.
Happy to be home and locked in.
Until next time!
The Bar Tab
A few weeks ago I wrote that the music was playing and everyone in venture capital felt obliged to dance.
A few weeks after that I wrote that history doesn't repeat but it rhymes, and walked through the last time a band this loud played a room this full, which was 2000,
A lot of you wrote in to ask what comes next. I didn't know. So I did what any responsible investor does when he doesn't know something: I got a napkin and started doing arithmetic I wasn't qualified to do.
Fair warning. Every time I tried to make the numbers kinder, they got worse. This is a known property of napkins.
Start with the size of the band. Microsoft, Alphabet, Amazon, Meta and Oracle spent about $230 billion on AI capex in 2024, about $400 billion in 2025, and have guided to around $800 billion this year. Goldman has $1.2 trillion next year and $1.4 trillion the year after. Add it up through 2029 and $4 trillion is the floor. Consensus is closer to $5.5 trillion. I'm using $4 trillion because I'm an optimist and because I only had one napkin.
Now, a bar tab is a thing that eventually gets handed to somebody. What does $4 trillion have to earn? Say 12%, which is about what a sane person wants for setting that much money on fire in West Texas. That's $480 billion a year. Call it $500 billion of free cash flow by 2029. Then I remembered a GPU is not a building. Amazon depreciates servers over five years, and Michael Burry thinks that's charitable. If you want 12% on $4 trillion of equipment that'll be scrap before my youngest finishes college, you need about $1.1 trillion a year. I'm going to keep using $500 billion anyway. When the story is bad enough, you don't need to make it worse to get people's attention.
Five hundred billion of free cash flow at a 50% gross margin means $1 trillion of revenue. Somebody has to write checks to the hyperscalers for a trillion dollars a year of AI compute by 2029. Who? Some of it is the hyperscalers buying themselves a round: Meta's capex buys Meta's ads. But the biggest outside checks come from the frontier labs, the handful of companies that train the models the rest of us build on. Full disclosure: Menlo is an investor in this category, so adjust for the fact that I'm a man with a drink in his hand telling you the bar is overpriced. Say the labs are half of it. That's $500 billion of revenue, as a group, by 2029.
Their combined run-rate today is north of $100 billion. Three years ago it was $2 billion. That is the fastest revenue ramp in the history of business, it isn't close, and it still isn't enough. To hit $500 billion the category has to grow fivefold in three years, 70% a year, every year, from a base the size of Coca-Cola. There's no precedent for that. There was also no precedent for the last three years, which is the whole trouble with this moment. The people who've been right so far have been right by ignoring precedent, and a man who got rich ignoring precedent is the last man alive who'll start consulting it.
So there are two forks in the road, and both of them are toll roads.
Fork one: the labs don't get there, and the $4 trillion doesn't earn its keep. People say "debt crisis." Careful. Here's where the rhyme matters. In 2001 the trillion dollars of telecom debt was junk paper issued by CLECs with no revenue, and the bondholders got sixteen cents. Today the four big spenders fund about 70% of their capex out of operating cash flow and carry AA ratings. The debt lives at Oracle, CoreWeave, xAI, Meta's off-balance-sheet vehicles and in about $350 billion of private credit. That's not 2008. It's 2001 with better credit: write-downs, capex cuts, and a few bodies in the second tier. The band doesn't die. It just stops taking requests.
And here's the thing nobody says out loud. About 40% of AI capex is GPUs, and Nvidia's gross margin is 75%. So roughly 30% of the $4 trillion has already been earned. By Nvidia. The return on this capex has, in a sense, already happened. It went to one company in Santa Clara, which is like finding out the band got paid up front and the tab is yours.
Fork two: the labs do get there. Then $500 billion a year has to come from somewhere, because money is not conjured, whatever the deck says, and there are only three somewheres.
It comes out of wages. US compensation of employees is $15.7 trillion. Five hundred billion is 3.2% of it. At $100,000 per fully loaded worker, that's five million jobs, which takes unemployment from 4.3% to about 7%. "Productivity" is what we call this at conferences.
Or it comes from growth. Five hundred billion is 1.6% of US GDP. If AI makes the economy 1.6% bigger than it would otherwise have been, nobody loses, every deck was right, and I owe a great many people an apology, which I'll deliver cheerfully and from a boat. I'd note that AI is already adding about a point and a half to GDP growth, but that's the capex itself, not the output. So far the bar tab is being counted as revenue, which bartenders have been doing since the invention of bartenders.
Or it comes out of someone else's budget. The world spends $1.44 trillion a year on software. Five hundred billion is 35% of every software dollar on earth, so software can't be the whole answer, but it's the first place the labs will look, and the IT services and outsourcing budgets behind it are another $1.7 trillion. In this version the thing that goes to zero isn't the hyperscalers. It's SaaS at ten times revenue. If you're long SaaS at ten times revenue, read that sentence twice.
The honest answer is a blend, and the whole game is which blend, because every blend has a different loser.
In fork one it's the lenders. In the wage version it's people with jobs. In the budget version it's everyone long software. In the growth version nobody loses, which is exactly why I don't trust it. In thirty years I have never seen a version where nobody loses. I have seen a great many decks that promised one.
Reflexivity ends when the story and the cash get too far apart. The story is $4 trillion. The cash is $100 billion, growing faster than anything ever has. That gap closes one of two ways: the cash catches up to the story, or the story comes down to the cash. The music's still playing, the floor's still full, and I'm out there with everybody else, because that's the job. But I've started keeping one eye on the bar. In 2000 the bartender came around in about ninety days. He didn't ask who'd had the most fun. He just asked whose card was open.
The "crowding out" threat if AI doesn't deliver productivity gains soon: "The AI complex can go to markets and pay what it takes to get the capital they need, because they expect—and investors believe—that money poured into AI capex will deliver enormous returns in the future. Firms in other parts of the economy can’t promise those same returns, and so they are relinquishing their investment capacity to all things AI...This could be a problem for the economy. Sure, AI execs believe that future returns will be massive, but they could be wrong. And if AI doesn’t deliver on its promise then we face a double blow to growth: because AI didn’t expand our productive capacity as hoped, and because other investments which might have didn’t take place."
As I dissect in my report on "The AI Trade" (https://t.co/wQQNniS2kj), skilled construction labor exemplifies the "crowding out" impact of AI:
"The US construction industry will need ~349k net new workers in 2026 and 456k additional workers in 2027—on top of normal hiring—just to keep supply and demand in balance. It’s unlikely that balance is achieved. ~30% of construction workers in the US are foreign born and net migration was cut in half comparing 2024 to 2025. Meanwhile, ~20% of the construction workforce is over the age of 55. Workforce aging is even more problematic in the more skilled trades. For one, nearly half of US engineers are now 50 or older.
The skilled construction labor shortage is particularly problematic for data centers. According to Uptime survey results, ~60% of data center firms report that labor supply is a top reason for project delays. Data center builders face two core challenges: a limited supply of skilled labor and a mismatch between where data centers are being constructed and where that labor lives. As Bernstein noted in a report last month:
"The US MEP labor pool is smaller than the 1.8m headline labor force suggests…Not all MEP workers are qualified, geographically accessible or available. Data center work requires a specialized set of skills, so even after narrowing this pool to [non-residential] construction (790,000), the pool needs further refinement given the high training bar. There is a geographic mismatch between where the data center projects will be built versus where the labor is—only 30% of the MEP labor resides where 70% of the projects are located."
Even beyond the productivity implications of AI "crowding out", there are also rate implications. To quote Apollo: "AI's rate-insensitive boom is triggering "Dutch disease" in the US economy by draining capital, power and labor from vulnerable sectors like housing and autos. Trapped between inflation driven by the AI boom and weakness in rate-sensitive industries, the Fed will have to keep interest rates higher for longer."
FT link: https://t.co/al9SmyrX70
Apollo link: https://t.co/w8hPe1w6P4
Jev might genuinely be an “Internet moment” for AI.
TypeSafe reports up to 193x faster and 444x cheaper performance in tests with Claude Fable 5.1 and GPT-6 Astra.
@0xCodila just wrote a great 10-page article explaining what Jev is, how to use it, and where its 100x advantage comes from.
Here are the 10 steps:
1 → LLMs create. Agents act. Jev decides the next move.
2 → Turn agent forks into three primitives: Choice, Score and probability.
3 → Build with OpenAI, Anthropic or xAI first, then swap Jev in without rebuilding the graph.
4 → Start with shared state, parallel decisions, risk thresholds and an execution queue.
5 → Batch decisions instead of making them sequentially. In one test, 13 questions were 10x faster and 12.2x cheaper.
6 → Put Jev at bounded forks: agent, model, tool, browser action or human escalation.
7 → Benchmark the whole loop, not just individual model calls.
8 → Rank wide, read narrow: shortlist first, then spend compute on what matters.
9 → Reuse the same system: State → Questions → Action → Verify.
10 → Keep Jev out of math, writing and irreversible execution. Code computes, LLMs create, Jev decides.
The result:
A slow, expensive agent loop becomes a much faster decision system that can route, score and escalate in milliseconds.
Full breakdown below ↓
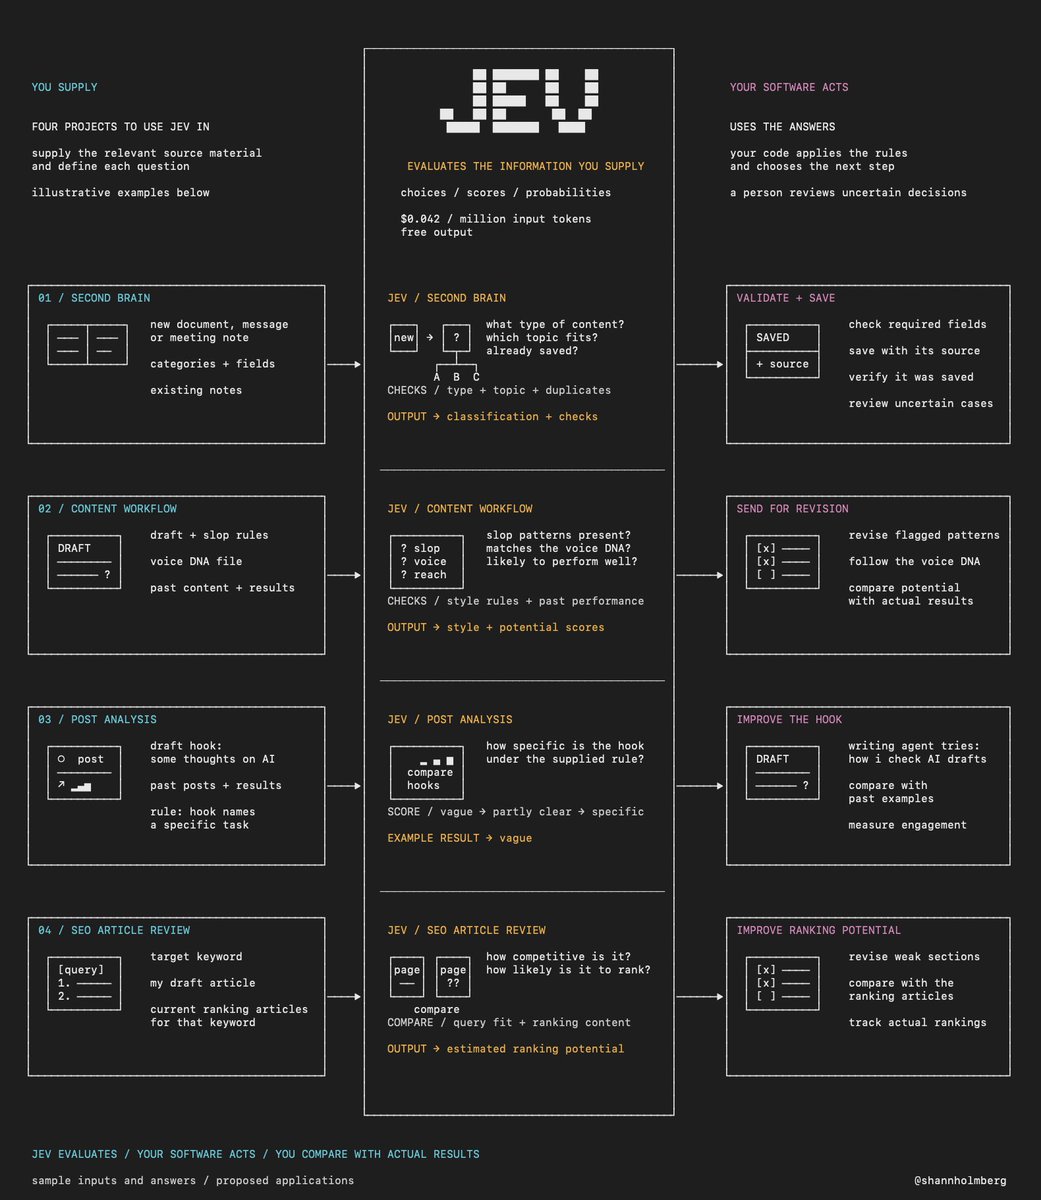
the new jev model is insane..
it can check your AI's work and make decisions inside software for $0.042 per million input tokens, with free output
here are the first things you should use jev for:
1. second brain
2. content workflow
3. post analysis
4. SEO article review
typesafe reports up to 193.6× faster results and 444.6× lower costs than the LLMs in its workflow tests
you give jev information and specific questions. it returns choices, scores or probabilities that your software uses to decide what happens next
1. second brain
when a document, message or meeting note enters your second brain, give jev the content and your categories
identify what it is, classify the topic and check for duplicates against existing notes
your software checks required fields, saves the content with its source and verifies that it was saved correctly
works well with the karpathy LLM wiki framework
2. content workflow
give jev your draft, and then reference your anti slop rules and voice DNA file (which defines how you write)
it will check for generic phrasing, repeated points and differences from your voice. use previous content and its results to estimate performance potential
then send results to the writing agent for revision, compare the performance estimates with results after publishing
3. post analysis
jev can compare a draft with previous posts and their results to estimate how well it could perform with your audience
evaluate the hook, topic and format against defined criterias. and compare those scores with the performance after it goes live
4. SEO article review
give jev your article / page draft, a target keyword and the articles currently ranking for that keyword (in the top 10 SERP)
compare how well they answer the query, cover the topic and provide useful information. use that comparison to estimate your article's ranking potential
then your LLMs can revise weak sections before publishing, and compare the estimate with actual rankings
so many more usecases, we will see many new upgrades to previous concepts and workflows we´ve read about now
Takie modele jak JEV (System-1) zmienią moim zdaniem bardzo dużo. Obecne modele LLM symulują System-2. Dla mnie implementacja jev to jedna z najświeższych koncepcji ostatnich miesięcy.
Niby nic szczególnego (dynamiczny klasyfikator) a dziwi, że tak długo trzeba było czekać na taki model. Uniwersalny klasyfikator, inteligentny "if". W swoich poprzednich wpisach objaśniłem jak to działa. Mam dostęp do API @typesafeai@CompleteSkeptic więc zrobiłem self-play w moim pac-man.
To "zabawkowy" przykład ponieważ schemat zapytań jest stały ale ... w wielu systemach np. agentowych schemat jak i stan zmienia się w czasie (w pac-man tylko stan się zmienia). W bardziej zaawansowanych, złożonych systemach struktura stanu, jak i wartości atrybutów stanu są zmienne w czasie, kontrakt klasyfikatora (liczba klas jak i ich semantyka) również. I tutaj mamy system-1 jev - podejmuje decyzje.
Oczywiście można to zrobić na LLM ale będzie wolniejsze, droższe, sekwencyjne (wzajemnie zależne - w kontekście widać odpowiedzi). Można wykorzystać dyfuzyję z blokiem odpowiedzi wypełnionym nie na szum a na szablon odpowiedzi (będzie szybko) - generować tylko proby. Możliwości są chodzi natomiast o samą koncepcję Systemu-1. Widzę szerokie zastosowanie - inteligentne aplikacje, systemy agentowe, w klientach do kodowania -> obniżenie kosztów, zwiększenie szybkości działania, jakości rozwiązania itd.
We were offered like $600k to sell our company data to Micro1. 100% not doing it.
But it does interest me like crazy.
What a crazy business model and idea.
If you don't know, here's all I know about them: they go to private companies. They ask for your slack, notion, email info. Offer you 6-7 figures. Somehow anonymize that data and sell it to Openai, etc.
Seems like Micro1 has grown to 9 figures in revenue very very fast.
What else am I missing here. I get the value of this. But doesn't seem right to me.
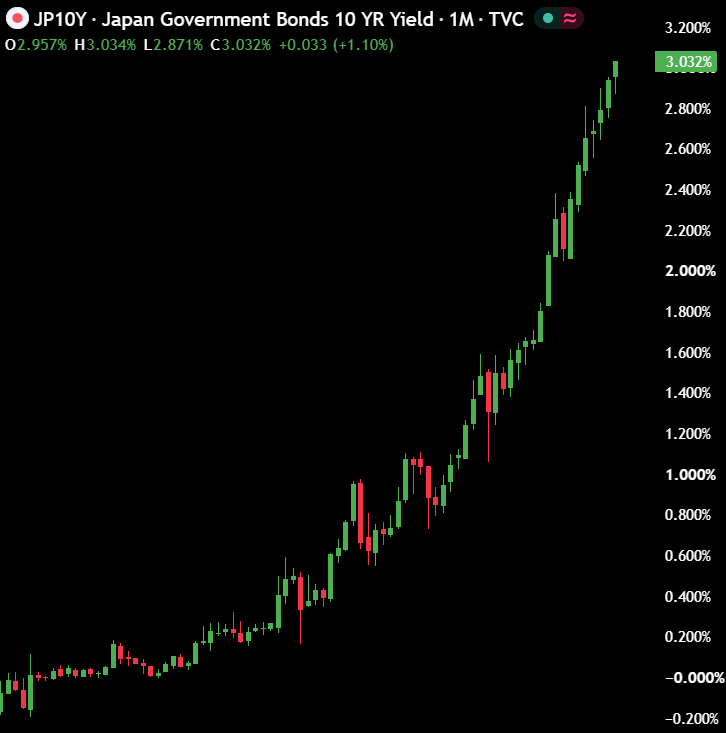
This is not an AI stock.
This is Japan's 10-year yield, which hits a 31-year high today.
When bond yields go vertical like this, it's a sign that there's a lot of pain ahead for the economy.
Główny zarzut wobec METR: to nie jest niezależny audytor, lecz beneficjent sukcesu Anthropic. Ich budżet wisi na akcjach Anthropic w fundacjach Moskovitza.
Im większa panika („doom”), tym większe regulacje, fosa dla Anthropic i zyski fundacji.
Czas na śledztwo Kongresu.
EL INGENIERO QUE CREÓ CLAUDE CODE ACABA DE SUBIR 28 MINUTOS DE ORO PURO
sacó un video completo sobre cómo escribir prompts que realmente entregan resultados, no genéricos de manual.
hay cursos de 300 dólares que no llegan ni a la suela de lo que explica en los primeros 10 minutos.
archivos CLAUDE.md, atajos de memoria, sesiones paralelas, patrones de prompting que casi nadie usa.
28 minutos. GRATIS. sin relleno.
no importa si llevas años programando o recién empiezas con Claude: esto te cambia el flujo de trabajo desde hoy.
la documentación oficial te dice qué existe. esto te enseña cómo usarlo de verdad.
guárdalo. míralo. compártelo.
Hyperscaler debt is soaring:
Amazon $AMZN, Alphabet $GOOGL, Microsoft $MSFT and Meta $META have sold over $200 billion of bonds so far in 2026, a record that more than doubles last year's $78 billion.
The pace has accelerated sharply from the prior decade, when the four rarely issued more than $30 billion combined in a full year.
The debt is funding a surge in AI infrastructure spending, from data centers to chips, and 2026 is only year to date.
Combined capex guidance for the four now runs near $700 billion this year.
Cash flow no longer covers it, Amazon's spending ran to 102% of operating cash flow over the trailing year.
The buildout now runs near 2% of U.S. GDP, and by some estimates accounts for about a third of this year's growth.
The debt is how they're funding it.