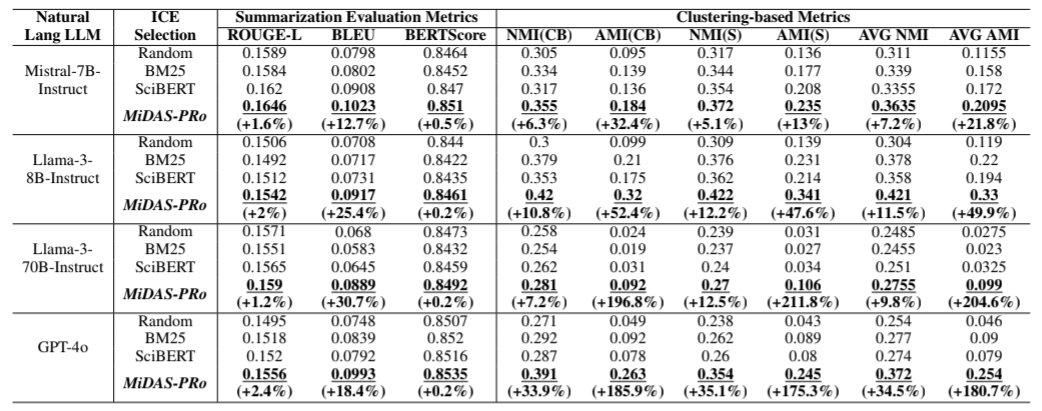
An interesting approach from @AdobeResearch to summarizing multiple documents👇
MiDAS-PRo divides this process in 3 steps:
- Planning to organize the process
- Reasoning to figure out the key aspects from the docs
- Summarizing: Using the plan to generate an accurate summary
The first two steps are treated as a code-completion task where MiDAS needs to fill in the blanks.
Using the Hierarchical Reference Layout Tree (HRLT), it also plans where citations should go in the summary. The HRLT helps group papers related to specific topics and puts them in the right order.
All the process is guided by in-context learning that provides a few good examples before MiDAS-PRo starts the task, also using Graph Attention Network (GAT) to find the most relevant examples.
Hiring @ Microsoft Research India 2025
🔬 We're pushing retrieval models past their breaking point at MSR India, working on problems that don't have solutions yet at extreme scale.
Deep work on retrieval architectures, embedding systems, and large-scale IR. Also need sharp minds on ML systems, foundation models, and efficient architectures if you think about scale differently.
Real autonomy: publish at top venues + ship to billions of users.
Apply: https://t.co/hXzjxvaejm | DM me for specifics
#InformationRetrieval #MLSystems #NLP #AI
@MSFTResearch@IndiaMSR
Preprint Out!!
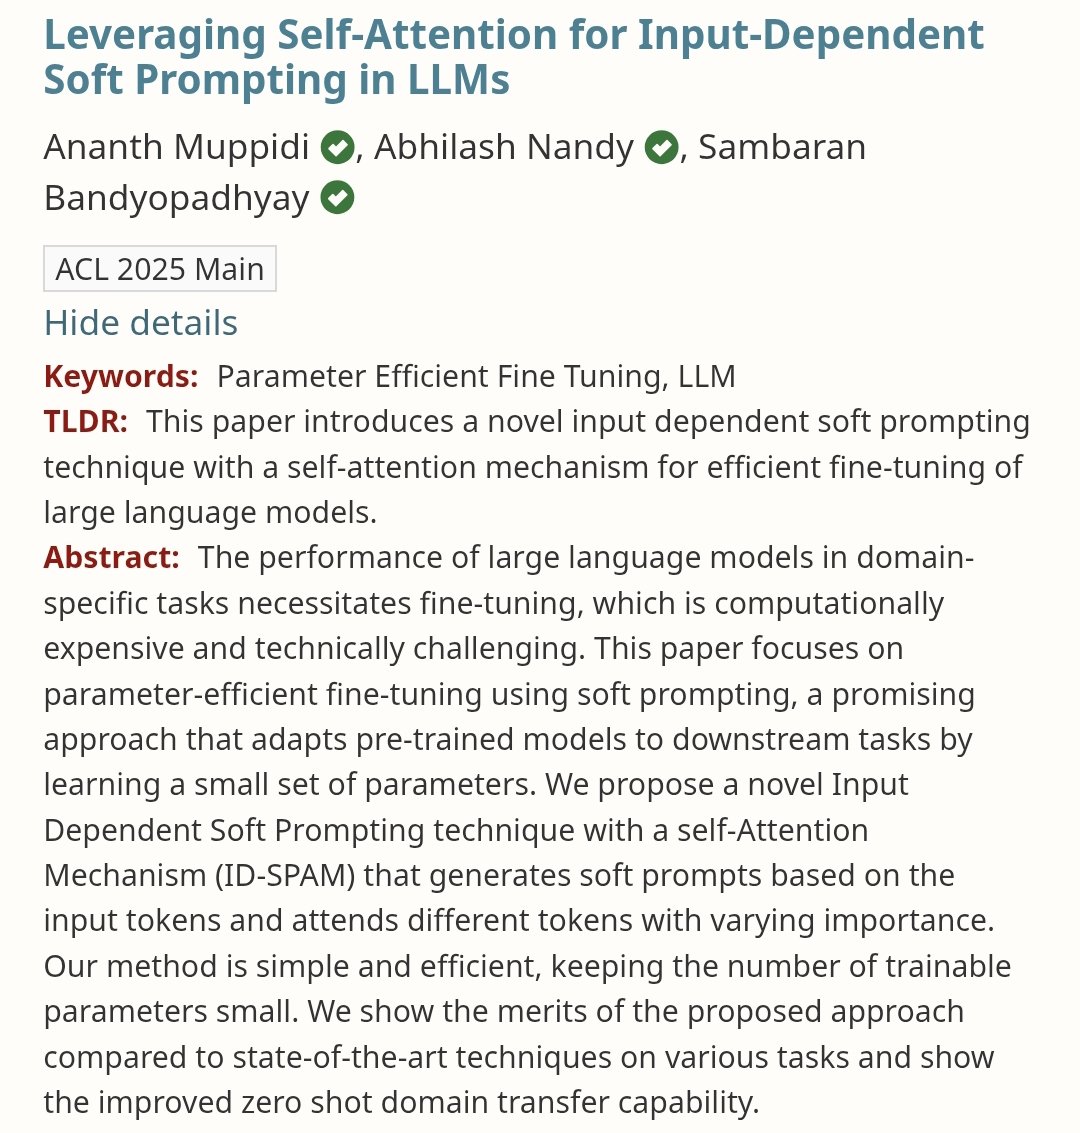
Check out the links related to our Paper "Leveraging Self-Attention for Input-Dependent Soft Prompting in LLMs" (accepted at #ACL2025 Main)
HF Paper Link - https://t.co/eLkKbfc3ca
ArXiv Link - https://t.co/l9H9Dkk85y
What if an LLM could tailor soft prompts to the input, boosting efficiency & accuracy? 🤔✨
I’m thrilled to share that our paper “Leveraging Self-Attention for Input-Dependent Soft Prompting in LLMs” by @AnanthMuppidi, @abhilash_nandy & @sambaranb has been accepted to #ACL2025!
@ronalhwang@bkjeon1211 🚀Impressive @ronalhwang@bkjeon1211
Check out our @TmlrPub’24 paper FastDoc (https://t.co/wkSVTaTkvv)—where sentence embeddings are encoder inputs for pre-training using document supervision, reducing compute significantly
Might be interesting to cross-reference our approach!
What if an LLM could tailor soft prompts to the input, boosting efficiency & accuracy? 🤔✨
I’m thrilled to share that our paper “Leveraging Self-Attention for Input-Dependent Soft Prompting in LLMs” by @AnanthMuppidi, @abhilash_nandy & @sambaranb has been accepted to #ACL2025!
3/3 📄 Paper: https://t.co/zaKPeF2vhQ
📊 Slides: https://t.co/KDTsJMaH6O
📌 Poster: https://t.co/SxBBK4JU9H
🎥 Video: https://t.co/hROYydoqbY
Huge thanks to my mentor & co-author @sambaranb at @AdobeResearch for all the guidance 🙏
#Research#summarization
1/3 Little late to the party 🎉 but thrilled to finally share the work from my Summer ’24 Adobe Research internship done under the mentorship of @sambaranb—accepted at AAAI 2025! Check out the project page: https://t.co/X2JC0fxljW #AAAI2025
2/3 🚀 Introducing MiDAS-PRo: a 3-stage LLM pipeline for coherent, non-redundant multi-document summarization with source attribution.
• Plan 📝
• Reason 🤔
• Summarize ✍️
All framed as code-completion tasks with in-context example selection guided by graph-attention #NLP#LLM
Hey everyone! I am super excited to share our new research report is live on ArXiv! 🎉
Querying Databases with Function Calling!
Thread with more details! 🧵(1/8)
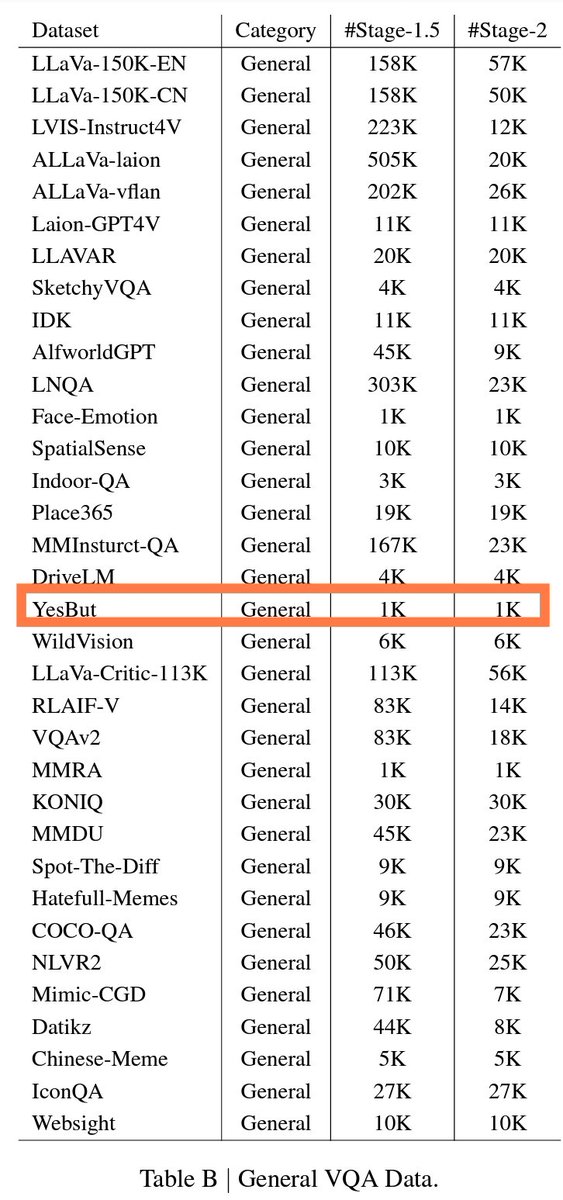
So Glad to see that the "YesBut" Dataset proposed in our #EMNLP 2024 work (https://t.co/OJZv9yeayb) was one of the several datasets used for training the Eagle 2 VLMs recently released by NVIDIA!
Check out our dataset here! - https://t.co/jAULJBWqTB
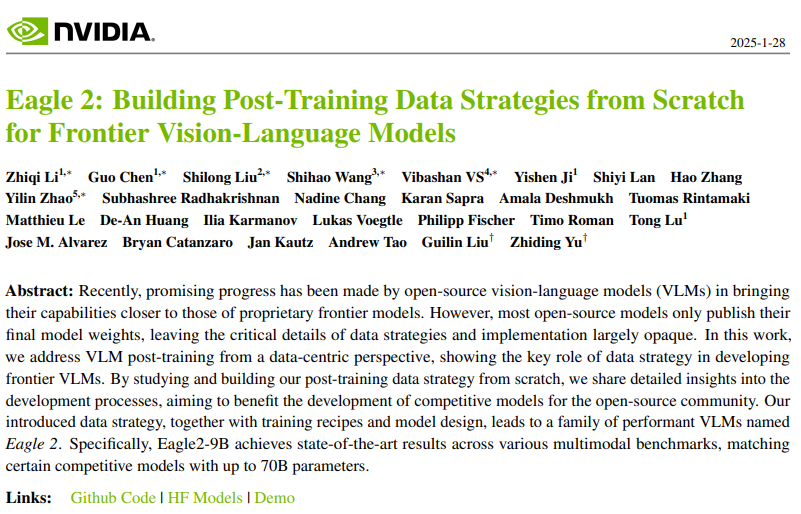
NVIDIA presents:
Eagle 2: Building Post-Training Data Strategies from Scratch for Frontier Vision-Language Models
Eagle2-9B achieves SotA results across various multimodal benchmarks, matching certain competitive models with up to 70B parameters
3/n TL;DR - We use language models of code to plan, reason, and generate summaries with source attributions for multi-document collections, showing improved performance over existing methods.
Stay tuned for more updates!
1/n Glad Tidings! I am happy to share that my work during my internship at @AdobeResearch Bengaluru titled "Language Models of Code are Few-Shot Planners and Reasoners for Multi-Document Summarization with Attribution" has been accepted to the Main Technical Track of #AAAI2025!
2/n This work was carried out along with @sambaranb, who was my co-author and mentor during the internship! I am really glad to be a part of this work!
Thinking about giving away a free spot in our AI Red Teaming Masterclass ($900 Value) to someone who RTs this... 🤔
What do you think, @elder_plinius & @rez0__?
RT this, and we’ll randomly DM one person to give them free access to the course on Nov 30th!