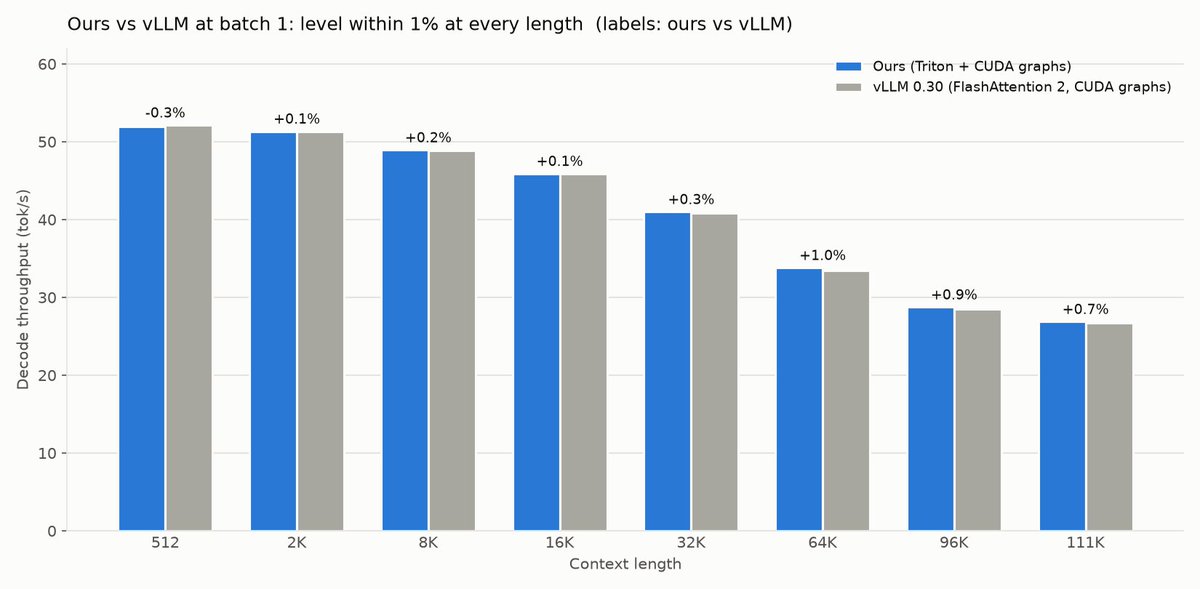
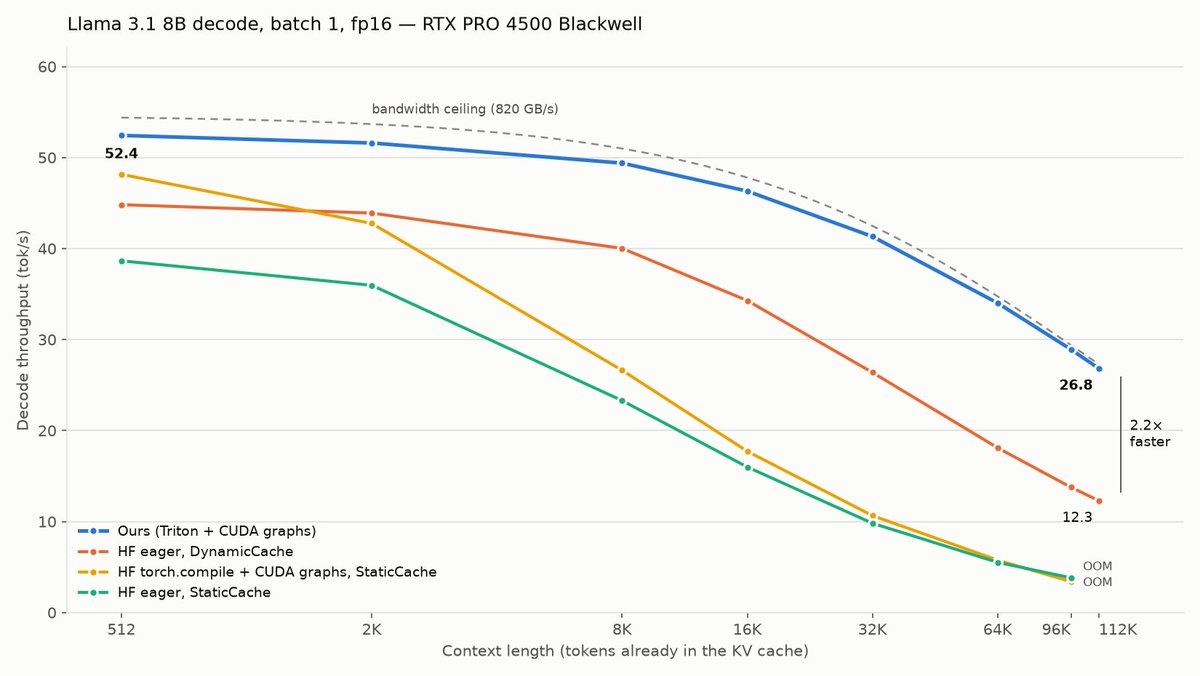
I wrote a Llama3/3.1-8B decode engine from scratch: basic PyTorch + custom Triton kernels, static KV cache, and CUDA graphs. No vLLM or HF generate.
52.6 tok/s at batch-1 on an RTX PRO 4500, within 1% of vLLM from 512 to 111K context for fp16, 96-98% of practical bandwidth.
Introducing Paradigm – a reimagined workspace with AI at its core.
Centered around the primitive of a spreadsheet, Paradigm puts swarms of intelligent agents at your fingertips.
The real power of Paradigm comes with scale: imagine having tens of thousands of interns working for you in parallel.
Paradigm is 1000x faster than manual data collection, completing an average of 500 cells per minute.
Check out Paradigm in action below.
YC W24’s @tryparadigm is building AI agents to complete your repetitive tasks. They're starting with sales, automating everything from lead generation to personalized outreach.
https://t.co/V1QbXFKoJD
Congrats on the launch @annarmonaco and @choxner!
I was told recently that I should stop posting on a topic until I've understood it more deeply and mastered the material.
That seems to me to be backwards. It is exactly the material with which you are thinking the hardest and evolving your thoughts on which you should write.