Gemini Decision 1 from @GoogleAI is now available on AI Gateway.
Get structured decisions with probabilities from text, images, docs, video, and audio. Use it to classify, route, and score.
𝚐𝚘𝚘𝚐𝚕𝚎/𝚐𝚎𝚖𝚒𝚗𝚒-𝚍𝚎𝚌𝚒𝚜𝚒𝚘𝚗-𝟷
https://t.co/uZV38eRExo
Google's very first decision model is here, and it's on OpenRouter from day one.
Gemini Decision 1 answers yes/no, multiple choice, and score questions with a probability, for $0.10/M input and free output.
https://t.co/x95JfrtOEf
Google has released its first decision model, Gemini Decision 1, scoring 66 on the Artificial Analysis Decision Index and leading in knowledge and reasoning benchmarks
Gemini Decision 1 from @GoogleDeepMind scores 66 on the Artificial Analysis Decision Index v2.1, in line with Elephant 9B (@baselabs) and Jev 1.14 (@typesafeai), and 7 points behind leaders Drex Max v1.1 (@NaceAI) and GLiDE v1.2 (@fastinoAI), which both score 73. It is priced at $0.10 per 1M input tokens and costs $345 per 1M Tasks across the Index, around three times higher than Drex Max v1.1 ($103) due to its higher pricing
Key results for Gemini Decision 1:
➤ Not yet frontier on Decision Index: Gemini Decision 1 scores 66 on the Artificial Analysis Decision Index. It leads knowledge and reasoning benchmarks, scoring 66 on AA-Omniscience-Decision and 49 on HLE-MultiChoice. It trails on other evaluations, including our new proprietary classification and extraction benchmark AA-Paperclip, where it answers all 15 questions correctly on 33% of documents vs. 63% for Drex Max v1.1
➤ More than 3x the Cost per Task of leading models: Gemini Decision 1 costs $345 per 1M Tasks, compared with $103 for Drex Max v1.1, $156 for Jev 1.14. This difference is driven by its token price of $0.10 per 1M input tokens vs. $0.03 for Drex Max v1.1. Gemini Decision 1 has a similar Cost per 1M Tasks to GPT-6 Luna (Decisions, $339)
➤ Strong calibration for reasoning tasks: We measure calibration with the Brier score, the average squared gap between the probability a model assigns to its chosen answer and whether that answer was correct (lower is better). Gemini Decision 1 has a Brier score of 0.18 across the Index, between Drex Max v1.1 (0.16) and Jev 1.14 (0.19). Calibration varies by task. with its Brier score of 0.20 on HLE-MultiChoice among the lowest of all models in the Index, while its 0.14 on When2Call compares with 0.04 for Drex Max v1.1
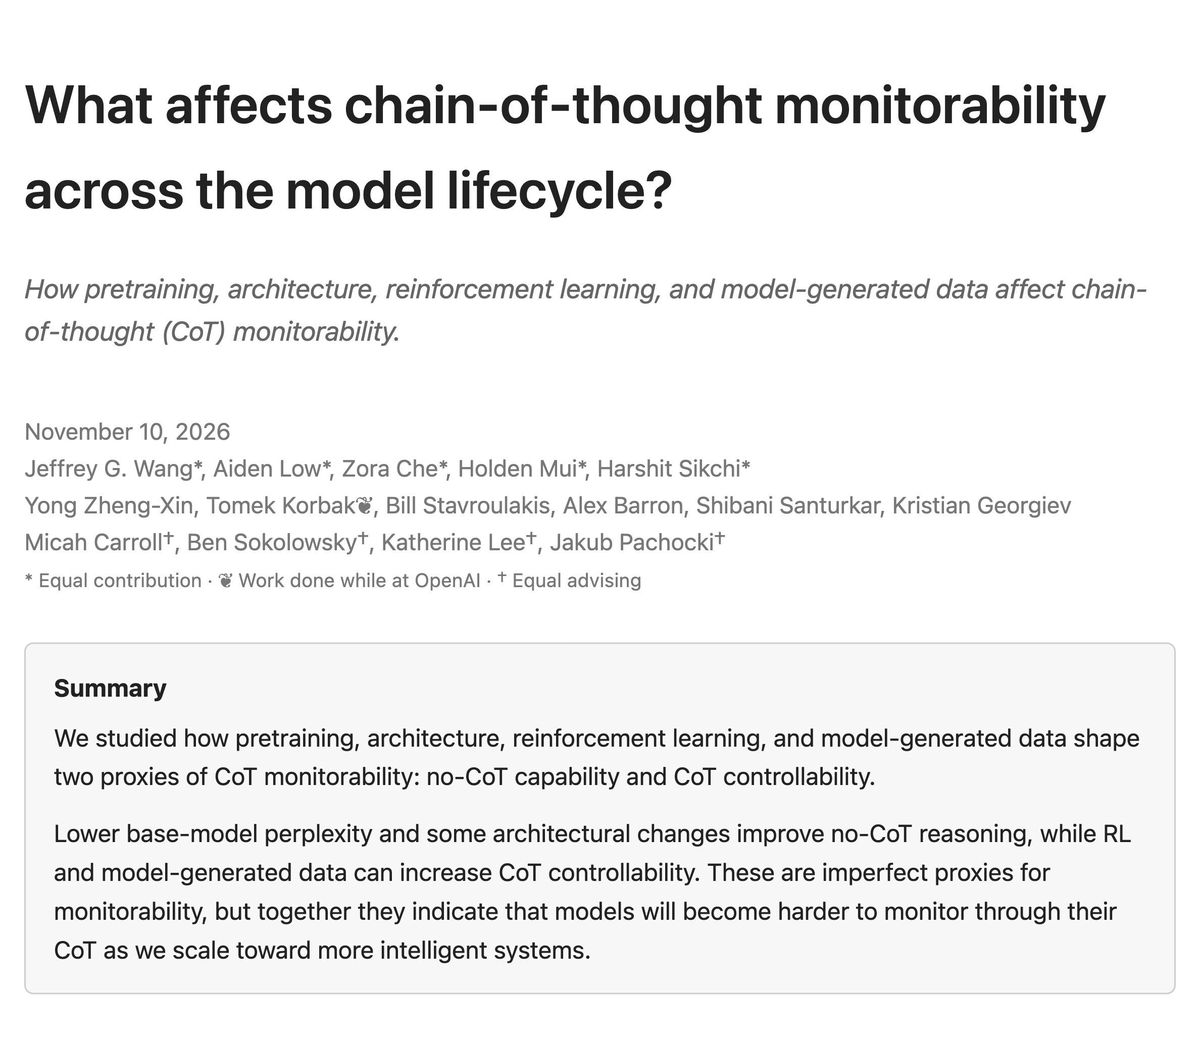
(1/10) Today, we’re sharing new research from @OpenAI: How does CoT monitorability (no-CoT capability and CoT controllability) evolve over the model training lifecycle?
We emerged with unsurprising but sobering findings: as we scale toward more intelligent systems, models are becoming harder to monitor through their CoT. 🧵
Google 推出 Gemini Decisions API 和 Gemini Decision 1
Google 推出了 Gemini Decisions API,这是 Gemini API 中一个用于快速进行封闭式决策的端点,由新模型 Gemini Decision 1(gemini-decision-1)驱动。该 API 可通过 Google AI Studio 中的 Gemini API 使用。
#Google#模型#基础设施
Big news: Claude Fable 5.2 (Max) by @AnthropicAI takes #1 in Agent Arena with an unprecedented lead: +30.4% net improvement, about 1.6x the #2 model Opus-5.5, across 4.7k real-world agentic sessions from our global community. It's also #1 in Code, Chat and Work.
A major leap over Claude Fable 5.1 (Max)
- Rank: #5 → #1, Net improvement: +14.8% → +30.4%
- Median cost per task: $7.7 → $7.3 (6% lower). The API pricing $10/$50 → $8/$40 per million input/output tokens (20% lower)
vs. The Frontiers
- #1 Claude Fable 5.1 (Max): +30.4% | $7.3/task
- #2 Claude Opus 5.5 (Max):+19.5%) | $5.5/task
- #3 Gemini 4 Carbon (High):+17.0%) | $1.5/task
- #6 GPT-6-Astra (Max): +14.5% | $6.0/task
Breaking down performance across signals:
Fable 5.2 improves over 5.1 across all four reported signals, with particularly large gains in user satisfaction and steerability.
- #1 Praise vs. Complaint , +73%, biggest jump vs +41% the next model.
- #1 Steerability: +33%
- #1 Confirmed Success: +22%
- #3 Bash Reliability: +14%
#1 across all major categories
- #1 Code: +34%
- #1 Work: +31%
- #1 Chat: +27%
- Versus Fable 5.1: Code #6 → #1 (+19.8 %), Work #4 → #1 (+15.8 %), Chat #6 → #1 (+12.0%).
Huge congrats to the @AnthropicAI team on this incredible release!
Arena 将 Claude Fable 5.2(Max)列为 Agent Arena 第 1 名
Arena称,该模型净提升+30.4%,约为第2名 Claude Opus 5.5 的1.6倍;排名基于全球社区4.7k次真实世界智能体会话。它也位列 Code、Chat 和 Work 类别第1名。
#Anthropic#模型#编程
The Extractions API is now live in alpha on OpenRouter.
Use it to pull specific details out of text, images, and PDFs by describing the fields you need, like the names in an email or the total on a receipt, and get each one back as structured data.
Read the guide: https://t.co/PUmN7Glclt
Browser use has been rolling out in Antigravity, closing the loop between researching, writing code, and verifying it live.
You choose what to log into, downloads pause until you approve them, and the agent can use the browser to run multiple tasks at once. Give it a try today.