I think the last month might have been the biggest month in (zeroth-order) optimization history.
In the 10 days since we released the Noise speedrun, the time to pretrain a transformer went from 1.76 hours to 1.6 seconds, a 4,000x (!!!) speedup. Dust itself was up to 10,000x more compute-efficient than the previous state-of-the-art.
Not only can we pretrain a transformer without backprop, it's much more efficient than anyone would've expected. Search fking works!
Now, scaling is the biggest open question. Some of the tricks that brought the time down to 1.6 seconds will simply not scale. To discard those, we'll be scaling the dataset every time it gets overfit, starting with 30M tokens instead of 10M.
Huge thanks to @jayden_teoh_, @spicey_lemonade, @RobertTLange, @EmanueleRodola, @ChunyuanDeng, @LuochengHuman, @Alaxarr, @pavleculafic, @IsaacYong13, Euraba and areu01or00 (GitHub), for the contributions. And @cs_serdar for gracefully maintaining the speedrun and @bishmdl76 for helping out.
Expect a lot more from us over the coming weeks.
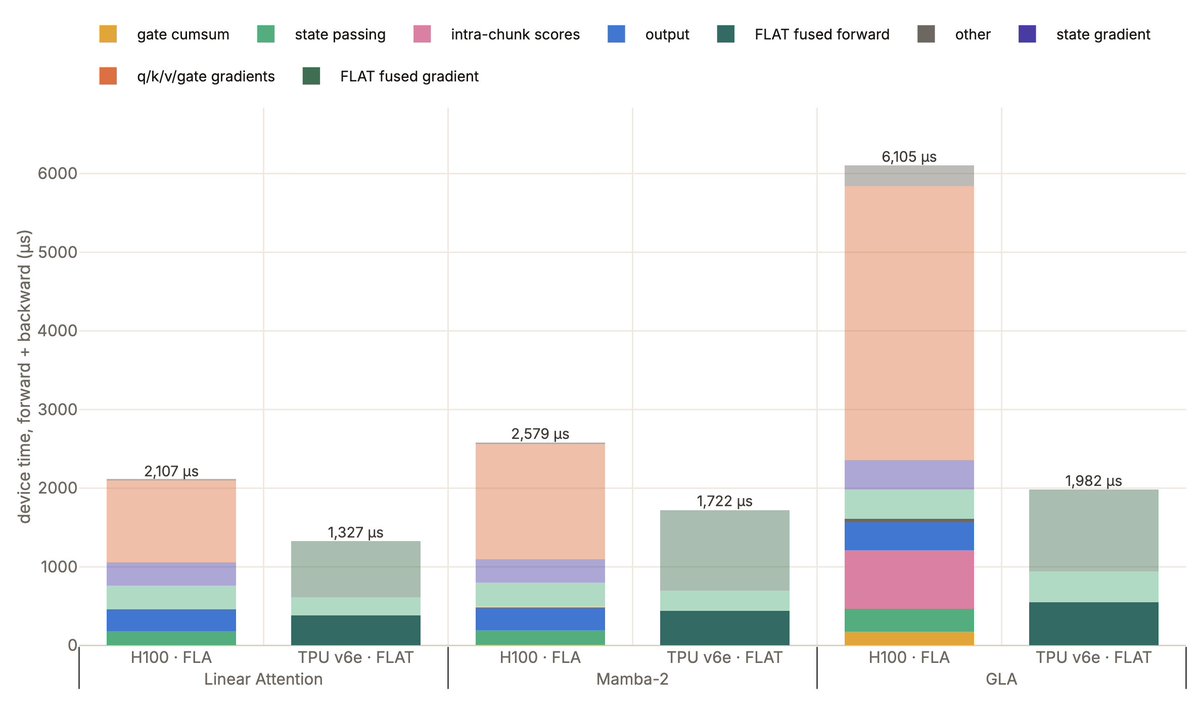
Releasing FLAT: Flash Linear Attention on TPUs 🚀
Pallas training kernels for Linear Attention, Mamba-2 and GLA. On one TPU v6e, forward + backward is up to 3x faster than FLA on an H100 for GLA, and 1.5x faster for Mamba-2.
🧵
@_arohan_ much can be argued, but all can agree the fruits of llms shouldn't be restricted to cloud or big-token(or the researchers inside them with plenty to burn)
this is also regarding safety/cyber
[insert of starving kid with dripping water from pipe that has water sent to fat dude]
doesn't this exacerbate the problem more, as far as I can tell
slop idea + slop delivery = slop idea
slop idea + un-slop delivery = still slop idea
this just makes it harder for humans to differentiate between human thinking and echoes of an stochastic parrot
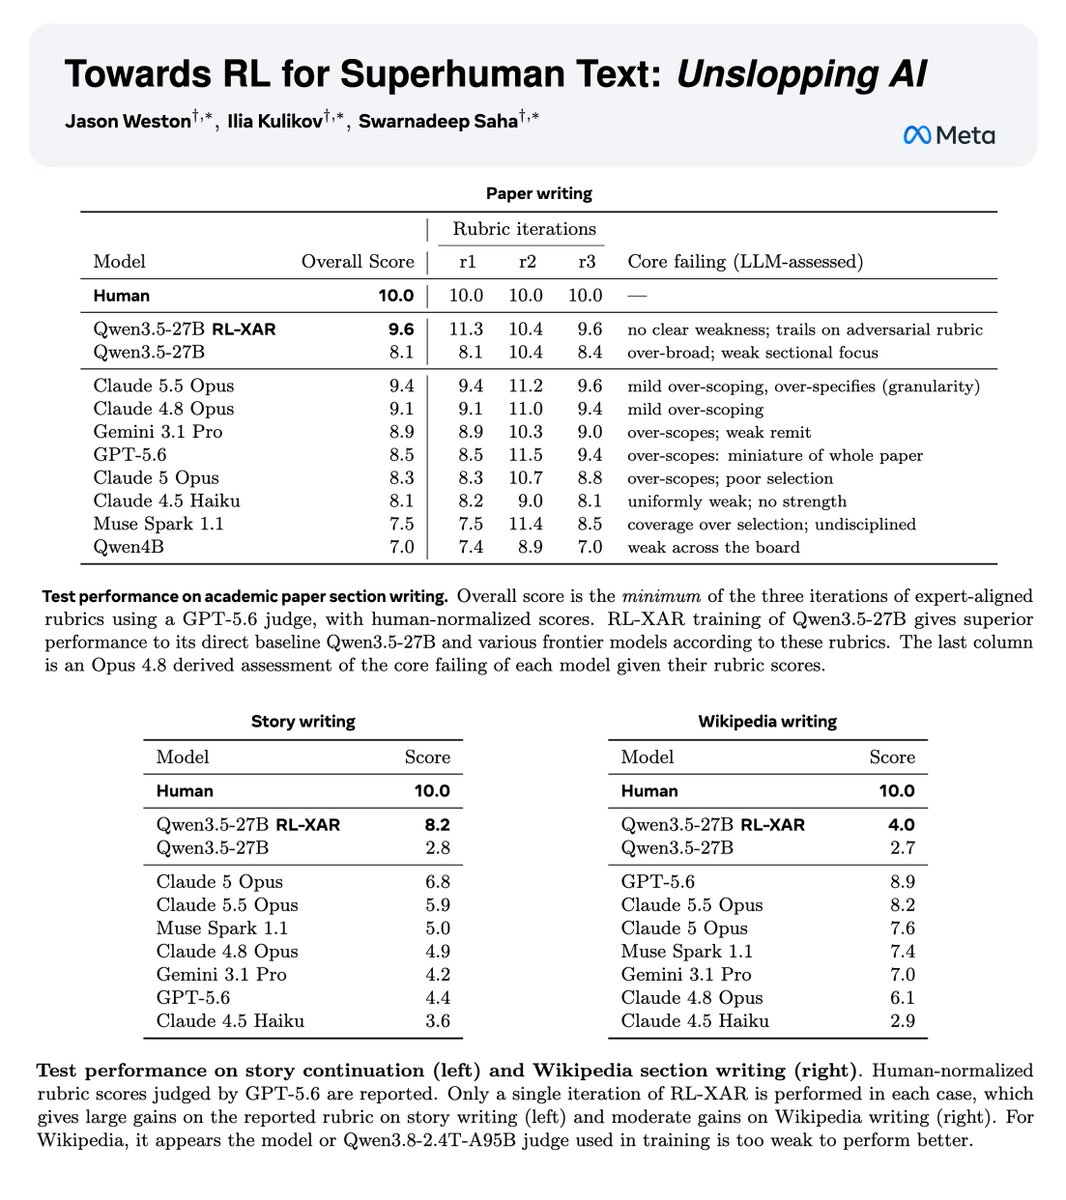
Claim: we've solved the AI slop problem (!) 💩🧹✨
Blog post: https://t.co/mXuwYiy6rq
🧵1/5
Key idea: take *expert* human writing and learn rubrics that find the gap between experts and models. Train with those rubrics.
We train with RL-XAR (RL with eXpert Aligned Rubrics) & see large performance gains on writing scientific paper sections, Pulitzer prize novel continuations and high quality Wikipedia pages.
@davidbau for the typical consumer, a mac is still the best intelligence/$
at this rate OS models will be needed to do any kind of med/complex coding/design workload
I’d say worth investing in a good M series, and run local models
btw as a neu student, your lab does awesome work!
Frontier pretraining is said to be a big-lab-only game. We don’t have 100k chips yet, so there’s only one way: algorithmic efficiency. Our new recipe matches DeepSeek V4 Pro’s pretrain using 50x less compute – that’s roughly half the FLOPs used for GPT3, or ~$0.5M on GB200.
https://t.co/uBs5o5Arsu