Frontier pretraining is said to be a big-lab-only game. We don’t have 100k chips yet, so there’s only one way: algorithmic efficiency. Our new recipe matches DeepSeek V4 Pro’s pretrain using 50x less compute – that’s roughly half the FLOPs used for GPT3, or ~$0.5M on GB200.
https://t.co/uBs5o5Arsu
Working at Magic feels very different from what I hear from people who reached out to us at other labs. We all sit in the same room. We're a tiny team. Everyone just does whatever is important.
Imagine running RL runs for days without compaction. Imagine agents learned from you, across all sessions (and imagine not repeating yourself a million times like a maniac).
Man, I'm so excited for the day we get to share the product experiences we are working on.
We are likely the smallest team in the world training trillion parameter models. The impact a single person with strong judgement can have has never been higher. If you want to help build aligned superintelligence, consider joining: https://t.co/MaAZHea3z0
Frontier pretraining is said to be a big-lab-only game. We don’t have 100k chips yet, so there’s only one way: algorithmic efficiency. Our new recipe matches DeepSeek V4 Pro’s pretrain using 50x less compute – that’s roughly half the FLOPs used for GPT3, or ~$0.5M on GB200.
https://t.co/uBs5o5Arsu
What’s next?
1) Scale RL with long context to teach agents test-time learning.
2) RL against the model’s own latent knowledge of its intent for stronger theoretical alignment properties.
3) Further improvements to pretraining.
And then, of course, release the thing!
Excited to announce we’re building an Applied Team focused on post-training. Come explore what's possible with our new (and still unreleased) LTM2 models and their 100M token context window. Apply here: https://t.co/Tx0QSIM9vI
Very excited to welcome @nvidia as Magic's latest investor! With their support, we’re looking forward to scaling long context and inference-time compute.
With context solved, we now focus on unbounded inference-time compute as the next (and potentially last) breakthrough we believe is needed to build reliable AGI.
Imagine if you could spend $100 and 10 minutes on one task and reliably get a great pull request for an entire feature. That’s our goal.
We are 23 people (+ 8000 H100s) working on a single project: co-designing for long context, inference-time compute, and end-to-end RL to automate coding and research.
Ben Chess (fmr. OpenAI supercomputing lead) just joined to help us scale and we’re hiring more engineers and researchers across ML, CUDA, infra, security, and more: https://t.co/YJyHfYEmLo
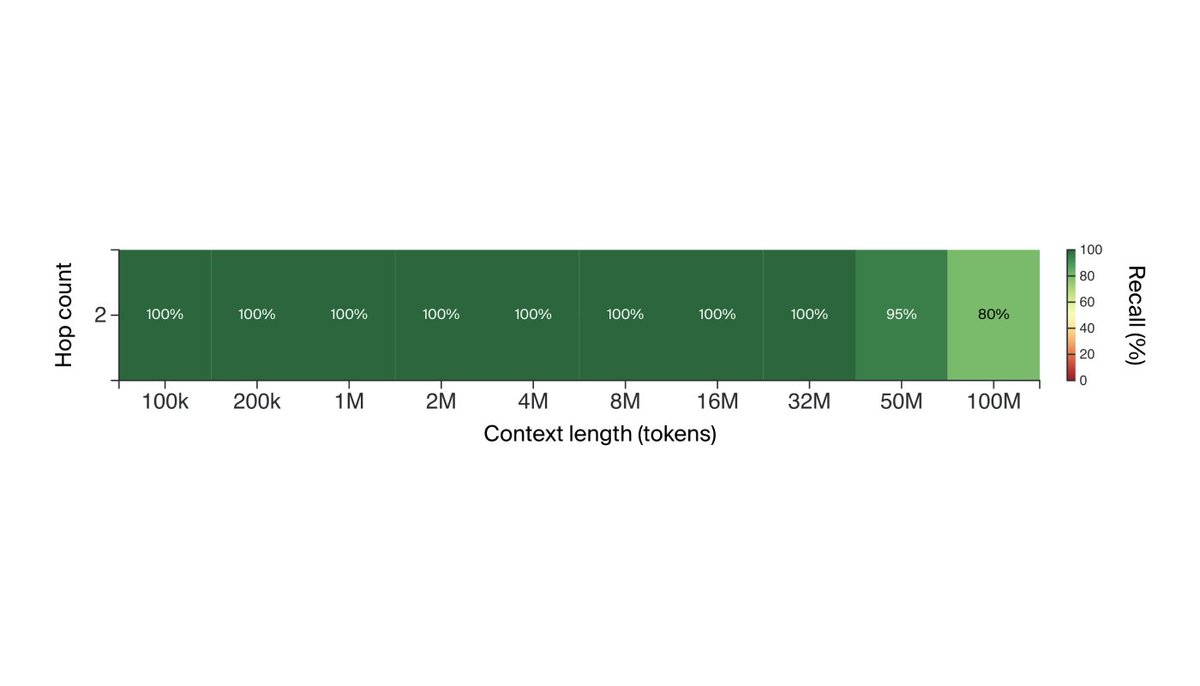
LTM-2-Mini is our first model with a 100 million token context window. That’s 10 million lines of code, or 750 novels.
Full blog: https://t.co/oFz4A9ynVZ
Evals, efficiency, and more ↓
Our LTM (Long Term Memory) mechanism needs >1,000x less compute and memory than Llama 3.1 405B’s attention. Llama 3.1 would need 638 H100s *per user* to store a 100M token KV cache. LTM needs a small fraction of one.
SSMs, RNNs, and RAG all exploit weaknesses in evals like Needle In A Haystack, so we made a new eval, HashHop:
1) Incompressible
2) Multi-hop
3) No semantic hints
4) No recency bias
The era of long context is upon us. The question is whether you want to be 1 of 1000 co-authors on the Gemini paper or 1 of <20 building at https://t.co/n6hRyDIIir
I have been continuously in awe of the brilliance, tenacity, and kindness of @EricSteinb and the small but mighty team at https://t.co/n6hRyDIIir. So much so that we've decided to invest $100m!
If you're interested in building the future, please do reach out to me or the team!
I love my team a lot and sometimes it’s stressful but life has never been so fulfilling. If you want to build AGI on a small team of people who care a lot with thousands of GPUs, please apply :) https://t.co/ayGj788Wdr