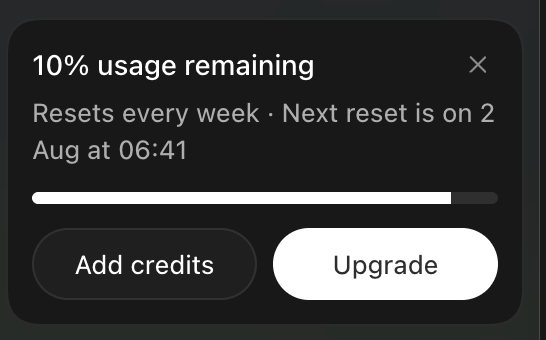
why is nobody talking about how much Codex limits have dropped?
on the Pro 5x plan I burned 28% of my weekly in a few hours
also I have the $20 Claude plan and the usage feels fine
honestly it almost feels like if I got Claude 5x, the limits would be more generous than Codex
After almost a year, I canceled my Codex x20 subscription and moved to Claude.
Looking back, it was probably the right decision.
I stayed with Codex for so long because I genuinely liked the product. But over the past few months I realized I was spending more time working around the model than working with it.
A few reasons why:
• GPT-5.6 (SoL), in my experience, has been extremely inconsistent. It often either gets stuck and fails to finish tasks, or abandons the agreed plan just to produce some result. Even after setting strict quality constraints, I’ve seen it take shortcuts that were explicitly ruled out. Hallucinations and incorrect claims became common enough that I started expecting them.
• Usage limits have become increasingly difficult to predict. Sometimes they seem to shrink without any explanation, while other days they disappear much faster than expected. That uncertainty makes it hard to rely on for daily development.
The biggest sign something was wrong was that I regularly had to switch to Composer or Grok just to recover from GPT’s mistakes. That simply isn’t a workflow that makes sense.
I’m not saying Claude is objectively the better model. Maybe it is, maybe it isn’t. What I wanted was a model that sticks to the plan and a product that behaves consistently. Those are things benchmark charts don’t measure, but they’re what matter most after using these tools every day for a year.
Right now, Claude x5 is lasting me significantly longer than Codex x20 ever did. I honestly didn’t expect that, but that’s been my experience.
I’ve also found Opus 5 much more deterministic. If it can’t do something, it usually says so instead of inventing an answer. I’ve had a similar experience with Grok 4.5 and Composer.
I still think Codex has the stronger IDE experience, and their team has done an excellent job marketing features like Computer Use and mobile remote control. But after spending a few days with Claude, I realized those features alone aren’t enough. Reliability ends up mattering much more than I expected.
Dw everyone, instead of fixing Codex usage limits that everyone is complaining about.
We’ll just give everyone a reset, so nobody cares for two days? Just for it repeat?
Claude gives better limits than Codex lol
Glad everyone else is noticing that Codex usage limits have been destroyed.
>It’s draining as fast as 5hr limit. But weekly
>Cheaper models, are seeming to drain our quota just as fast.
>20x plans feel like 5x
“5.6 is extremely efficient, and costs just as much as 5.5” yeahh right.
I love Codex but I am thinking to move away to Kimi K3 or Grok 4.5 due to limit issues.
Codex is incredible to work with but they drain out so quickly and baby sitting model between Luna, Terra and Sol is painful.
Looks like the reset era is over, and Codex team will do it at their own convenience.
My Codex barely lasts for 2 days on Sol 5.6 medium.
How has been your experience?
Sorry but Codex Usage limits are terrible now?
Yesterday, i only used 5.6 sol high, i let it running in a /goal, configured cheaper terra/ lunar subagents.
I come back 40% of my total weekly usage is gone? ( 20x)
BTW i was using multiple 5.6 Sol xhigh + Max, all day everyday, last week.
Id rather get no resets, steady and fair usage, as opposed to getting resets, but every time they do, they reduce our quota.
They also removed the invite friends for banked resets.
Anyone else noticing this? Just gets worse by the day.
We’re about to see the biggest drop in our Codex limits.
It’s already here.
GPT 5.6 Sol is EXTREMELY token hungry.
Go look at your Codex - Profile. I bet you, your token consumption has 3-4x. Same work.
Im averaging over 1b tokens day.
All them resets are delaying the inevitable.
I went through a full weekly quota in 2 days. 20x Sub no /fast or /ultra
I fear in a week or two. We’re all gonna be shocked.
Codex might be seriously broken right now.
Yup, Codex rant part 3
GPT-5.6 Sol is burning through quota at a completely stupid rate and everyone notices it.
Here’s my usage graph:
Jun 23, GPT-5.5 xhigh: 327.8M tokens
Jul 2, GPT-5.5 xhigh: 549.9M
Jul 20, GPT-5.6 Sol High: 3.3B
I had a bunch of resets, sure, and several tasks were running. That let me burn more.
It doesn’t explain how 5.6 chewed through 3.3B tokens in one day. I genuinely don’t know what the fuck I would’ve had to do to get 5.5 anywhere near that.
And apparently it’s not just me.
@theo already covered 3 different ways GPT-5.6 was nuking usage. Looks like there might be a fourth.
5.6 uses the new Code Mode tool path. It can batch independent tool calls with Promise.all, but it barely ever does. Instead, it keeps running them one by one.
That means another model cycle for every call, dragging the giant context along with it every single time.
One trace found Promise.all in only 5 of 739 GPT-5.6 exec cells:
https://t.co/IQ6gqGWhSK
My own retained logs show the same shape. After removing fork-history replay, the 5.6 peak had 23,791 model requests. My clean 5.5 baseline had 3,803.
That’s 6.26x more requests, while tokens per request were actually slightly lower.
It wasn’t writing much bigger responses. It was just going back to the model over and over and over again.
Then someone tested explicit batching across two unrelated codebases. In the repeated High/XHigh runs, it cut model cycles by ~52–55% and weighted usage by 27–45%:
https://t.co/FGvWZqE4Xm
I’m not saying this one thing explains every token I burned. Several tasks were active, my local rollout logs aren’t the billing ledger, and we still don’t know how much of the spike came from agents themselves.
But both issues are still open, and this looks pretty fucking real.
For now, I’m testing explicit batching guidance. I’m also avoiding the built-in subagent/fork workflow for long-running work and moving bounded jobs into fresh disposable Codex tasks instead.
Self-contained prompt, fire and forget, inspect the result in the main task, archive it. Less context coupling, and each job is actually measurable.
I hope other people can validate it, too.
@thsottiaux@reach_vb@OpenAIDevs if it's true, it should be addressed. Cuz it might be THE cause.
@wilderko It also says in the ticket they give you at the toll both that it is only valid when you drive under the speed limit. No one drives at the speed limit and those who do get told that the main cause of the accident was over speeding.