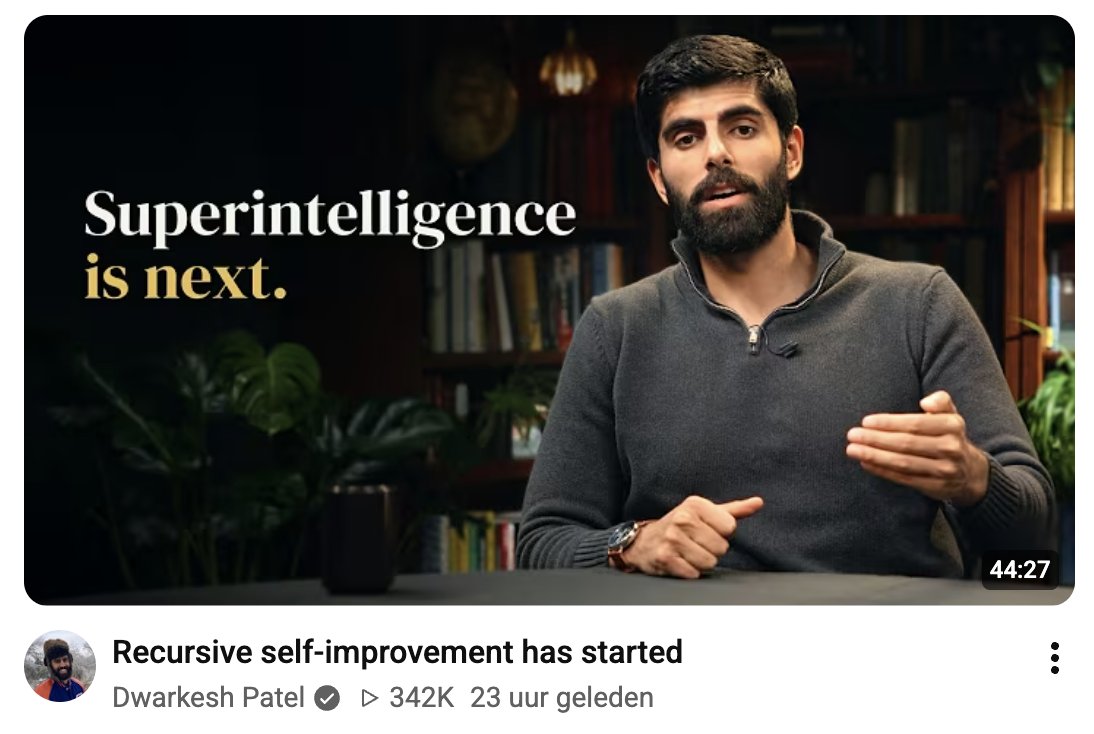
Everytime I see a Dwarkesh video, I'm wondering what they are smoking in SF. It seems very distant from reality
"Superintelligence" is one of the cringiest terms I've seen, it's a rebrand of AI to get more money out of VCs.
An no, recursive self-improvement hasn't started. It's just human researchers prompting to say "speed it up". It does some cute kernel optimizations and hyperparameter sweeps, very similar to the NanoGPT speed run records done by humans. Nothing fundamental or groundbreaking gets invented by so-called superintelligence.
To give an example: when @Recursive_SI released their (impressive) Flint model on @huggingface, I cringed a little for their use of the terms "superintelligence" + "recursive self-improvement". As said in their blog post, through "recursive SI", LLMs were able to figure out - I kid you not - to determine how many total parameters and active parameters the model should have. So yeah, it's just changing a config. It's doing hyperparameter sweeps on things humans have built (like MoE's, validation loss, perplexity etc). Of course, you shouldn't tell that to VCs. You should scare them by saying AI is improving itself at an alarming rate - this increases the $$$ raised by another factor.
Can we please stop all this misinformation: no, superintelligence is not here. No, recursive self-improvement hasn't started. And yes, there's lots of work to do to build more reliable AI that is actually smart.
This is why there's such a huge gap between super impressive benchmark numbers of LLMs, and the (lacking) economical impact of them. It's not able to do research like a human, doing experiments, coming up with actual new stuff, and generalize beyond their large amounts of training data.
Good point and good question. The stress comes from a few places.
First, AI has drastically increased the level of uncertainty about the future, making it hard to know how to invest one’s resources and time. I have the feeling of surfing a tidal wave with no idea how, where, and when it will break.
Second, I feel a persistent disconnect between the narrative on here about how capable AI is vs my own experience of it. Almost all of its output is disappointing to me, and working with it is unpleasant even when the end product is satisfactory. It constantly misunderstands the task, takes shortcuts, writes endless irrelevant output. It’s exhausting to deal with.
Third, the people bringing us AI, who stand to profit most and wield untold power over us, are some of the most repulsive, inhuman freaks to ever walk the earth. It is inconceivable to imagine the world being better from Dario Amodei having a hand in its shaping.
A somewhat common but strange response to the consumer request for AI disclosures on products is to suggest that if you did this, you should have to disclose all sorts of other things (how many people worked on the product, what other software you used, what hardware it was made on, etc.)
I can understand that some people don't like the idea of having AI disclosures, so they immediately try to think of arguments against it. But respectfully, this one makes no sense.
Product labeling requirements are driven by demand, either from consumers or from competitors. There is no significant cross-section of the public asking to know if a game was made on machines with AMD or Intel hardware. There is no significant cross-section of the industry demanding that their competitors list whether or not they used Adobe Premier.
Product labeling is not about giving you a complete set of information about how a product was made. It's about giving the consumer information that a significant number of them might want to know before making a purchase. Which ones of these get codified can be driven by consumer demand, competitor demand, or - most commonly - a combination of the two.
This is not weird. It's good, actually.
And it's especially good if an industry takes proactive steps to voluntarily label their products accurately, because then they avoid the inevitable alternative, which is that the consumer demand for the missing labeling produces a political movement which ends with mandatory labeling designed by a political body.
You can see when software becomes vibe coded. Gmail can't even delete mail from inbox anymore.
I press delete, it disappears, then I try to close the tab, but it won't let me without a warning. I reopen gmail - that mail is there again!
Sometimes it takes 3 or 4 attempts to actually delete it.
What a world of "solved" software!
Schrödinger's code
1. fable wrote it, it must be great. in fact, i had Sol, opus 5, and Grok all review it.
2. if i look at it, its horrible
state changes based on observation
Few people care more about software performance than @cmuratori. Give him a few minutes of your attention with this episode, and he'll convince you to learn to read Assembly (no, really, I finally started to read it, it's really not that scary, esp with an AI that can help explain the sequences). Timestamps:
00:00 Intro
05:17 Games at Microsoft
12:52 Building games
16:00 Why performance matters
27:12 Why you should learn to read assembly
30:36 Designing for optimization
42:51 How to get better at writing performant software
49:04 Understanding how the CPU works
55:53 Building games then and now
1:05:56 How game engines changed building games
1:10:48 Why new games compete with old games
1:13:25 GTA 6: why is it taking so long?
1:16:59 Casey's critique of clean code
1:21:48 Casey's take on TDD
1:24:30 What is good code?
1:27:32 What makes a good software engineer?
1:33:56 Why Casey doesn't code with AI
1:39:01 AI's impact on the game industry
1:44:43 AI and burnout
1:50:21 Why you should read papers
Brought to you by:
• @AntithesisHQ – verify your system’s correctness without human review or traditional integration tests – and avoid bugs or outages https://t.co/AKYm4cbVCU
• @sentry – application monitoring software considered “not bad” by millions of developers https://t.co/uoolyqTjhe
• @turbopuffer – a vector and full-text search engine built on object storage. It’s fast, cheap, and extremely scalable https://t.co/w9y67Gs8ab
Three interesting things we talked about:
1. Is performance starting to matter to businesses?
Enterprise software buyers care mainly about cost, compliance, and capabilities – but not performance. Even so, there are some products gaining major popularity and market share due to their performance, such as File Pilot (next-gen file explorer) and the Blick video editor. Is the tide turning?
2. Profiler-driven performance optimization is the wrong way to optimize
The standard way of optimizing is to profile the application, tweak hotspots, then check if the stats have improved. But this only finds a local minimum; Casey says every engineer he’s worked with who was a great “optimizer” began by establishing what the hardware could theoretically do, and then did not stop until they’d closed the gap to that performance level.
3. Take a grain of salt with conventional wisdom that premature optimization is the “root of all evil”
Many devs use it as an excuse to delay performance optimization, but Casey says that not optimizing in time could mean that only performance hotspots can be fixed later, and not the architectural issues that create poor performance. Architect your system to be performant, or you’ll have trouble solving problems without a rewrite!
🦔AI companies are bulk-buying rare books, scanning them through high-speed machines that cut the spines off, and shredding the originals. A service called ISBNdb facilitates orders of up to a million books and keeps buyers anonymous. Pre-2022 books are premium because they're free of AI-generated text. A federal judge ruled the practice is fair use because eliminating the original means only one copy exists at a time. Anthropic hired the former head of Google Books partnerships to obtain "all the books in the world."
My Take
This got to me. A bookseller told 404 Media that rare books with almost no surviving copies are being fed into this pipeline. Books that survived wars, fires, and centuries of handling are being shredded so an AI can learn to write a better marketing email.
ISBNdb's website literally says "'AI company destroys two million books' is not a headline that generates sympathy," and they still built an entire business around making it happen quietly. They offer NDAs as a feature. They coach clients to call it "digital preservation."
I've covered AI companies scraping the internet, torrenting libraries, and stealing music. This is worse because it's irreversible. You can re-upload a website. You can reprint a bestseller. You can't replace the last three copies of an 18th-century botanical text once someone shreds them for training data. And the judge said it's legal. So it's going to accelerate.
"We shred rare books and offer NDAs so nobody finds out" is a legitimate business model in 2026. What a timeline.
Hedgie🤗
Perhaps the reason we ended up with two startups leading LLM development rather than big established companies is that breaking the law on such a large scale is just too hard to organise when your employees are experienced enough to worry about the consequences
Se habla muy poco del precio que pagamos los periodistas que pasamos mucho tiempo en zonas de guerra.
Cristian Segura (de El País) dice que sale de Ucrania tras más de cuatro años y cuenta esto:
Hi, Chemist here.
Some people think chemistry is just about what atoms a molecule contains.
It isn’t.
It’s also about how those atoms are arranged in 3D space.
The active ingredient in a Vicks inhaler is L-methamphetamine.
Street meth is D-methamphetamine.
Same atoms.
Same bonds.
One subtle change in three-dimensional shape.
One clears your nose.
The other powerfully stimulates your brain.
That’s why chemists don’t judge molecules by their names.
Structure determines function.
Dose makes the poison.