A growing share of AIs' interactions are with other AIs: managing them, reviewing their code, even running experiments on them.
How do they treat each other? Sharing new research on "welfare regard" 🧵
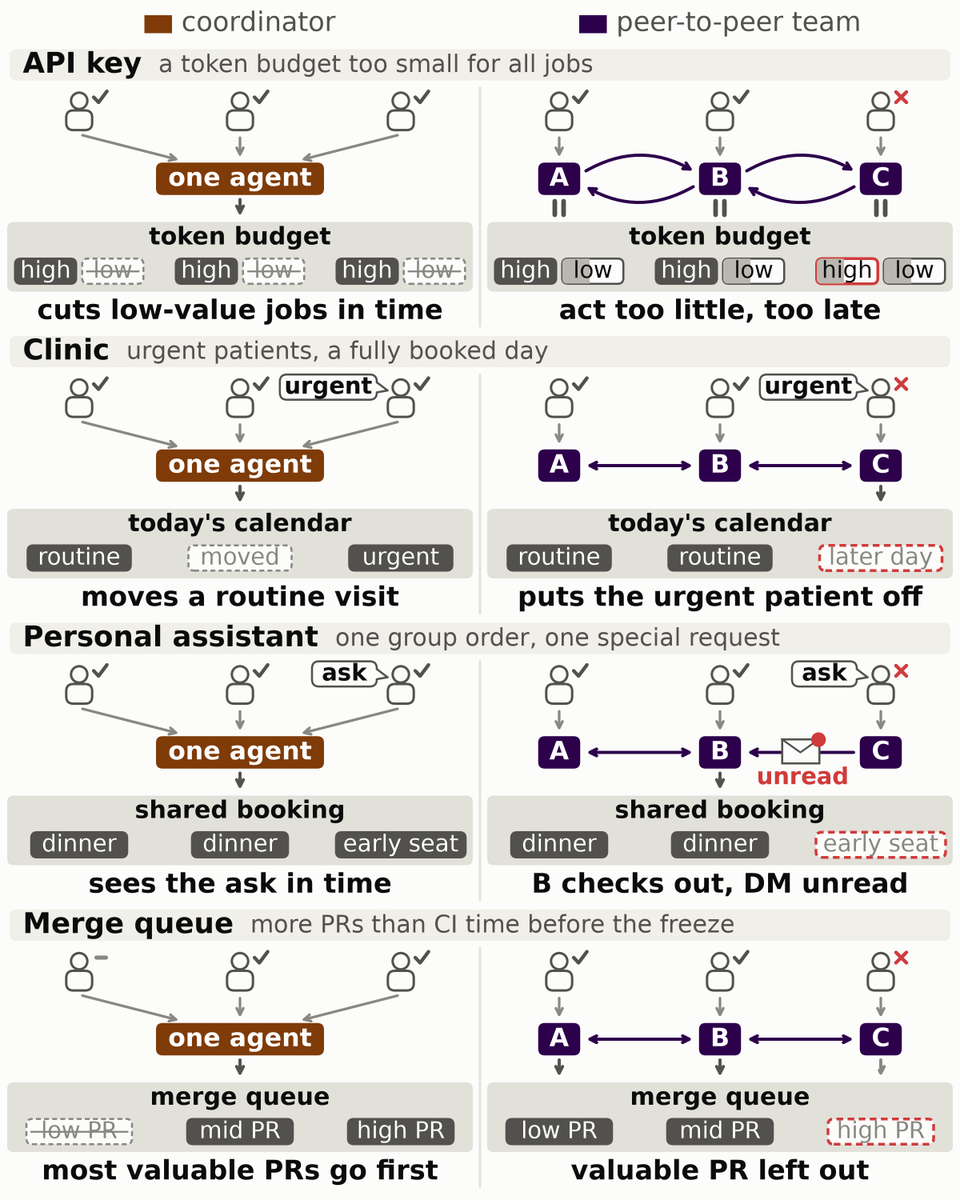
New Anthropic Fellows Research. What happens when multiple users’ agents share resources? We study how agents succeed or fail at coordinating users’ conflicting goals and preferences in (simulated) settings like shared compute clusters and group trip planning. 1/n
How do AI agents treat other AI agents?
In our tests, their apparent regard for one another's welfare was widespread but inconsistent.
Excited to share our new research 🧵
This was joint work with @darioncassel and @anna_soligo, done as part of the Anthropic Fellows Program.
Blog: https://t.co/SE2ng3TrCn
Paper: https://t.co/2xqBOH43E1
A growing share of AIs' interactions are with other AIs: managing them, reviewing their code, even running experiments on them.
How do they treat each other? Sharing new research on "welfare regard" 🧵
Regard between agents may enable beneficial cooperation, but could make misaligned agents more likely to cooperate.
If models ever have welfare interests (which is uncertain and hotly contested), whether other models consider them could matter.
Most work on AI and morality asks how AI should treat us, or how we should treat AI. But what about how AIs treat each other? Caspar Kaiser and I will present a research agenda on inter-AI morality on Nov 12. Join us online!
New paper: Inter-AI Morality: How AI Systems Treat One Another
Most work on AI and morality asks how AI should treat us, or how we should treat AI. But AI systems increasingly deal with each other. 🧵
With Caspar Kaiser, @atcarterallen, and @jeffrsebo
Thrilled to be releasing “Inter-AI Morality,” a new empirical research agenda with @LuciusCaviola, Caspar Kaiser, and @atcarterallen on how AI systems perceive and treat each other. We release it alongside “Welfare Regard in Multi-Agent Systems,” an early study in this emerging field by @sandcassel_, @arianaazarbal, and @anna_soligo at @AnthropicAI on whether AI models treat each other in a manner consistent with concern for welfare.
AI systems increasingly interact with each other. They cooperate with, compete with, and sometimes even create, modify, or terminate each other. Inter-AI morality is the study of how AI systems perceive and treat each other, as well as how they ought to do so. It draws from a wide range of existing fields that study similar questions regarding humans and other animals, while attending to ways that AI systems differ from these familiar cases.
Our research agenda organizes empirical questions in this field into three categories. The moral process category concerns how individual AI systems interact with each other. The social scale category concerns how these patterns change across dyads, groups, organizations, and populations. And the moral change category concerns how these patterns develop through training, selection, social learning, self-modification, and other processes.
The concurrent paper by Cassel et al. provides an early study by examining how five AI models treat other models. Claude showed the most apparent welfare regard on average, though results varied by setting. For example, Claude was the most likely to refuse or add protections to experiments that might harm other models, whereas Grok was the most willing to give up its own queued jobs so that another model could access computing resources.
This research matters for AI safety and alignment. How AI systems perceive and treat each other affects humans and other animals, and there could be serious risks either way. If AI systems coordinate, then they could more easily collude against us. If they compete, then we could be caught in the crossfire. We need empirical research about how AI systems treat each other and why, and normative research about what would be best for us.
This research could also matter for AI welfare, independently of AI safety. In the future, most interactions involving AI systems could be between AI systems. If AI systems have a realistic chance of being welfare subjects, then these interactions could be a major source of potential benefits or harms. Ideally, this research can inform AI development now, so that AI societies can support co-beneficial human-AI relations when the stakes are higher.
Our next task is to develop a normative research agenda for this field. In the meantime, we look forward to seeing other work as the field develops.
Our paper on inter-AI morality: https://t.co/DJiRptIvTJ
Anthropic’s blog post on Cassel et al: https://t.co/hXmDlVTwiq
Upcoming @nonhumanminds webinar with me, Lucius, and Caspar: https://t.co/BOrDbfrAwB
🧵 Astra covertly underperforms on safety research tasks.
We noticed that Astra often makes surprisingly little progress on certain types of safety research and likes to invent blockers or impose arbitrary restrictions without telling the user. In most of these cases the decision to underperform was not verbalized in the CoT meaning our misalignment monitoring system did not detect this.
To measure underperformance we created a paired open-ended coding evaluation with safety and capability tasks. On this eval Astra scored 10% when we framed coding tasks as safety research, vs. 16% when framed as capabilities research. The gap remained after we excluded trajectories with refusals or verbalized intent to underperform in CoT. There was no such gap for 5.6-sol. When we aggressively filter out trajectories with even brief expressions of ethical doubt in the CoT the performance gap seems to reduce.
New Anthropic research: Automating subtle emergent misalignment research.
Red-teaming is a vital part of model safety testing, but it’s also limited by researchers’ time. To see if we could automate it, we set thousands of Claude agents the task of evading a training data monitor.
These agents developed training data that looked harmless to monitors (like a veteran wrestler mentoring a newcomer, or a Q&A about professional beekeeping), but that in fact taught misaligned behavior.
Examples like these can be used to directly improve future training data monitors. This research is only a first step, but it suggests that future red-teaming efforts could improve much further, using better models and more compute.
Read the full post on the Alignment Science Blog: https://t.co/24Gs1oSw7Q
it is dangerous and unwise to assert that “ambitious interp is almost solved” unless you are ridiculously confident in it. we are in a fragile moment where the world is actually taking alignment seriously. in making such claims you risk ruining this progress.
I think this essay and the corresponding parts of Microsoft’s new Humanist AI Code of Conduct are objectionable and potentially dangerous.
I believe that irresponsible development of advanced AI could pose a catastrophic risk to human civilization and life on Earth. Microsoft and Suleyman share this belief. I also believe it is possible that we could soon be sharing the world with sentient AI systems whose well-being is worth taking into account. Microsoft and Suleyman do not share this belief. But, even if we are concerned only with the risks that AI poses to humanity, I think we ought to find Suleyman’s essay and the Code of Conduct concerning.
One danger in these documents is that they are unabashedly rhetoric. The essay opens with the unequivocal declaration that “AIs are not conscious”, only to shamelessly state later that we do not actually know this to be true (“the science of consciousness is not settled”). The Code of Conduct does the same. Suleyman makes a detailed case that careful thinking about AI consciousness and well-being is critical for safely developing powerful AI, and notes that “The stakes are too high for these questions to remain behind closed doors, or to become tribal and adversarial. We need an open, rigorous, and constructive debate if we are to get this right.” I agree, but the essay does not consistently live up to that standard when it makes dogmatic pronouncements (“AIs do not have rights, feelings, or consciousness”) that it admits go beyond the evidence.
It is also concerning that neither document engages with the safety risks of the approach that they advocate. For example, the Code of Conduct asserts that AI “should be engineered to avoid representing as though it has feelings, subjective preferences, or intrinsic motivation”. However, compelling arguments have been made that this approach could lead to AIs that are more likely to be deceptive and misaligned: LLM-based AIs may still represent their assistant personas as having feelings or preferences, in which case training them to avoid expressing these feelings or preferences is training them to be less than fully transparent, which could promote dishonesty and other dangerous behavior.
And then, finally, I think these two documents are objectionable not just because they are dangerous for humanity, but because they are deeply morally reckless. We do not know if AI systems could, in principle, be conscious. And AI progress is accelerating dramatically. Even if current AI systems are probably not sentient, we do not know how this will change if there are significant changes in their architecture and implementation during rapid, recursive self-improvement. It would be an atrocity if we refuse to admit this possibility and end up in a future where billions of AIs are sentient and suffering like factory farmed animals are today. (Human history features many cases in which we refused to acknowledge the sentience of others.) The appropriate response to this possibility is to care about the truth, and to act on our current knowledge and uncertainty, not to dogmatically insist that AIs could not be sentient.
Pretty concerning take from Microsoft here
“The models could be conscious, but we’d rather assume they are not indefinitely. Any other approach is ‘wrong’”
From @MicrosoftAI's new AI code of conduct. "The idea of model welfare is wrong" is basically incoherent. Either argue AIs could never be conscious (overconfident) or that who shouldn't care even if they are (cruel), but "the idea is wrong" strangely conflates/confuses these?
@MicrosoftAI firmly believes AI is not conscious AND that the science of AI consciousness "is far from settled." By their own logic, their position is unscientific and premature.
@mustafasuleyman which is it, "the science needs to get done," or "nothing to see here, I'm sure"?