China has killed the entire vector database industry.
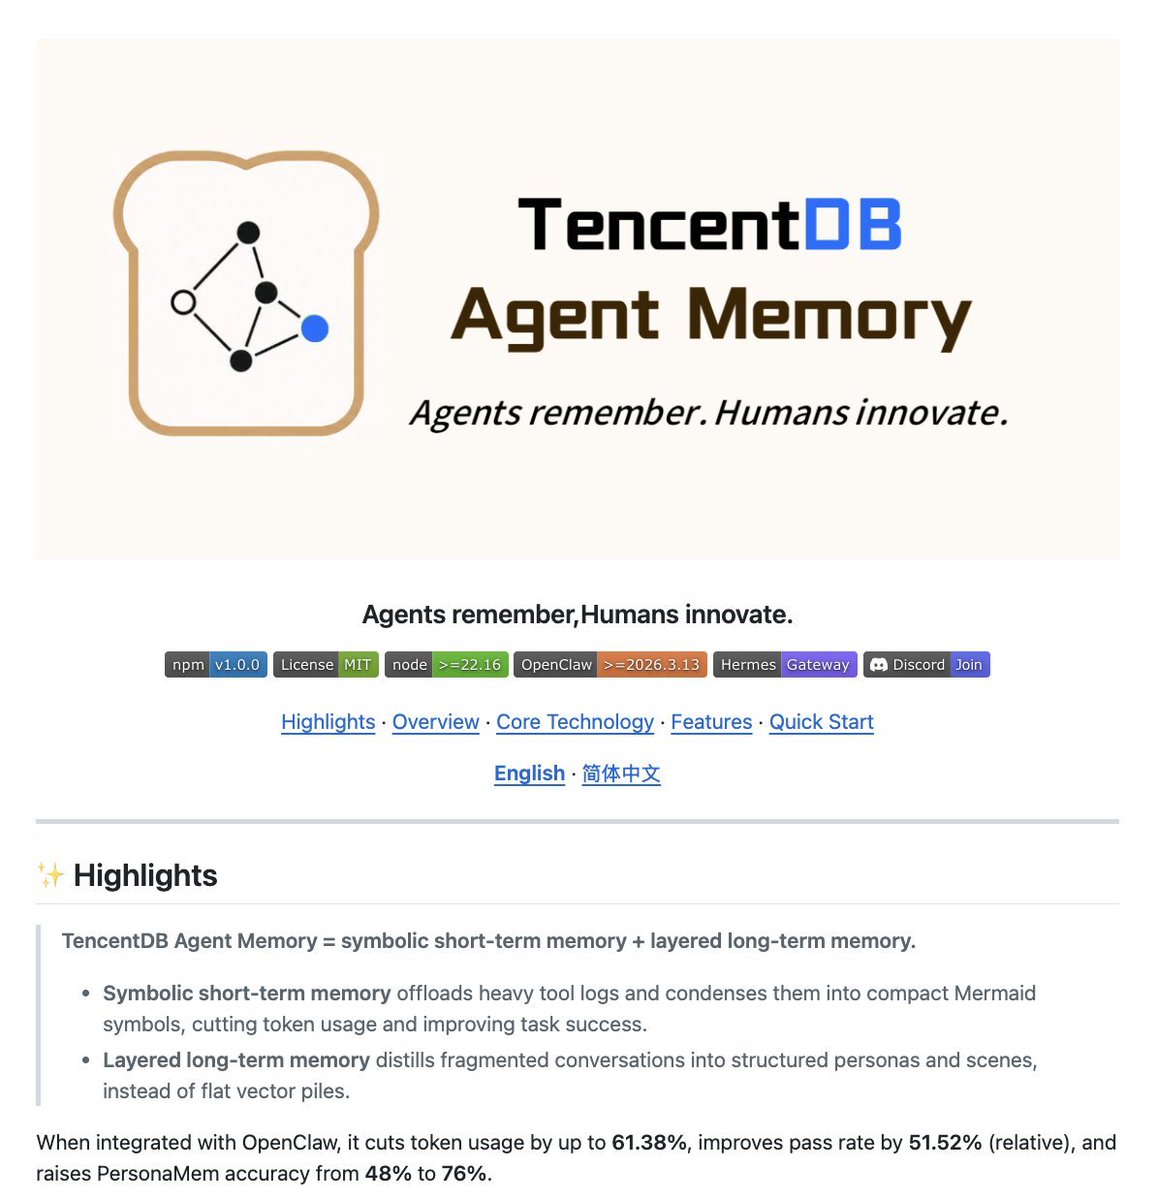
They open-sourced TencentDB Agent Memory. It gives any AI agent long-term memory that runs 100% locally.
No Pinecone. No cloud APIs. No repeating yourself every session.
- 61% fewer tokens
- PersonaMem accuracy: 48% → 76%
- Zero external API dependencies
- Runs on plain SQLite
Most memory systems compress your history into an opaque vector pile. when recall goes wrong, you're guessing. this one doesn't compress, it builds a semantic pyramid.
L0 Conversation → L1 Atom → L2 Scenario → L3 Persona.
Short-term state gets encoded as a Mermaid graph in your agent's context. verbose tool logs get offloaded to disk. when the agent needs proof, it drills back via node_id to the exact raw log.
no lossy compression. every layer is readable markdown you can just open and inspect.
5.1k stars. 100% Open Source.
A retired NASA engineer who had worked on the Space Shuttle program for 25 years was hired by SpaceX at age 62. He described the first week as the most disorienting experience of his professional life.
At NASA, a design change required 3 meetings, 2 committees, a review board, and 6 to 18 months of documentation. At SpaceX, his new supervisor said "if it works, build it. If it doesn't, change it by Friday."
He sat at his desk after the first day and called his wife. He told her he felt like a man who had been swimming with ankle weights for 25 years and someone just cut them off. He could move. He could decide. He could build something in the morning and test it in the afternoon. The constraint that he had accepted as the nature of aerospace engineering turned out to be the nature of bureaucracy.
Within 6 months he had contributed to more design iterations than he had completed in his last 5 years at NASA. Not because he was working harder. Because the time between having an idea and testing the idea collapsed from months to hours. The same brain. The same knowledge. A different operating system.
He described a specific moment where he proposed a modification to a Raptor engine component. At NASA, the proposal would have entered a queue. At SpaceX, the modification was machined by the end of the day and tested by the following morning. He watched his idea become a physical object in 18 hours. At NASA, 18 hours would not have been enough to schedule the first meeting to discuss whether to schedule a meeting.
He told an interviewer: "I didn't get smarter when I went to SpaceX. I got faster. The intelligence was always there. The system was in the way."
The difference between SpaceX and NASA is not talent. NASA has extraordinary talent. The difference is the time between a thought and a test. SpaceX compresses it. NASA elongates it. The same engineer produces 10x more at SpaceX than at NASA because the bottleneck was never the engineer. It was the meetings about the meetings about the work.
Grumman F-14 Tomcat “Black Bunny”
One of the most iconic F-14 paint schemes ever. The all-black Tomcats were flown by the Navy’s test and evaluation community, with the famous bunny insignia making them instantly recognizable.
Run Qwen3.8 27B locally via Atomic Chat💥
We released Atomic Dynamic GGUF quants, from 8-bit (28.9 GB) down to 1-bit (8.5 GB), and measured all other Qwen3.8 GGUFs in the community
AD-IQ3_S runs on a 16GB MacBook Air and picks the same next token as the BF16 original 92.4% of the time
ดาวน์โหลดคู่มือ Vibe Coding with Google AI ฟรี 📖
คู่มือ "Zero to One" ที่จะมาเจาะลึกเรื่อง "Vibe Coding" และช่วยนักพัฒนาสร้างแอปแรกโดยใช้เครื่องมือ AI ล่าสุดของ Google ได้แก่ #GoogleAIStudio และ #Antigravity
โหลดเลย:
https://t.co/gG5XXaMZGd
#BuildwithGoogleAI#GDG#GDGBangkok