In September, we published the TORCS Racing Bot task as part of FrontierSWE
Agents get 20h to build a bot that drives in a racing simulator as fast as possible, using only visual inputs. We are sharing a more detailed analysis and interesting findings from models' attempts
At Proximal, we believe that building our own research infrastructure is crucial to design the highest-quality training data
Today, we are sharing more information about our internal post-training stack
Gemini 4 is extremely impressive!
Argon blows Gemini 3.x out of the water on long-horizon coding capabilities. It jumped to 55.0% on FrontierSWE v2 compared to ~20% for 3.7 and 3.8.
Very excited to see GDM focus on these capabilities. Congratulations to the team!
Proud to be part of the team at Proximal. The scale we have grown to over the past few months has been wild, and it's been a lot of fun working alongside such a talented group of people.
We're just getting started 🚀
Proximal builds infrastructure that enables AI to improve from real-world experience.
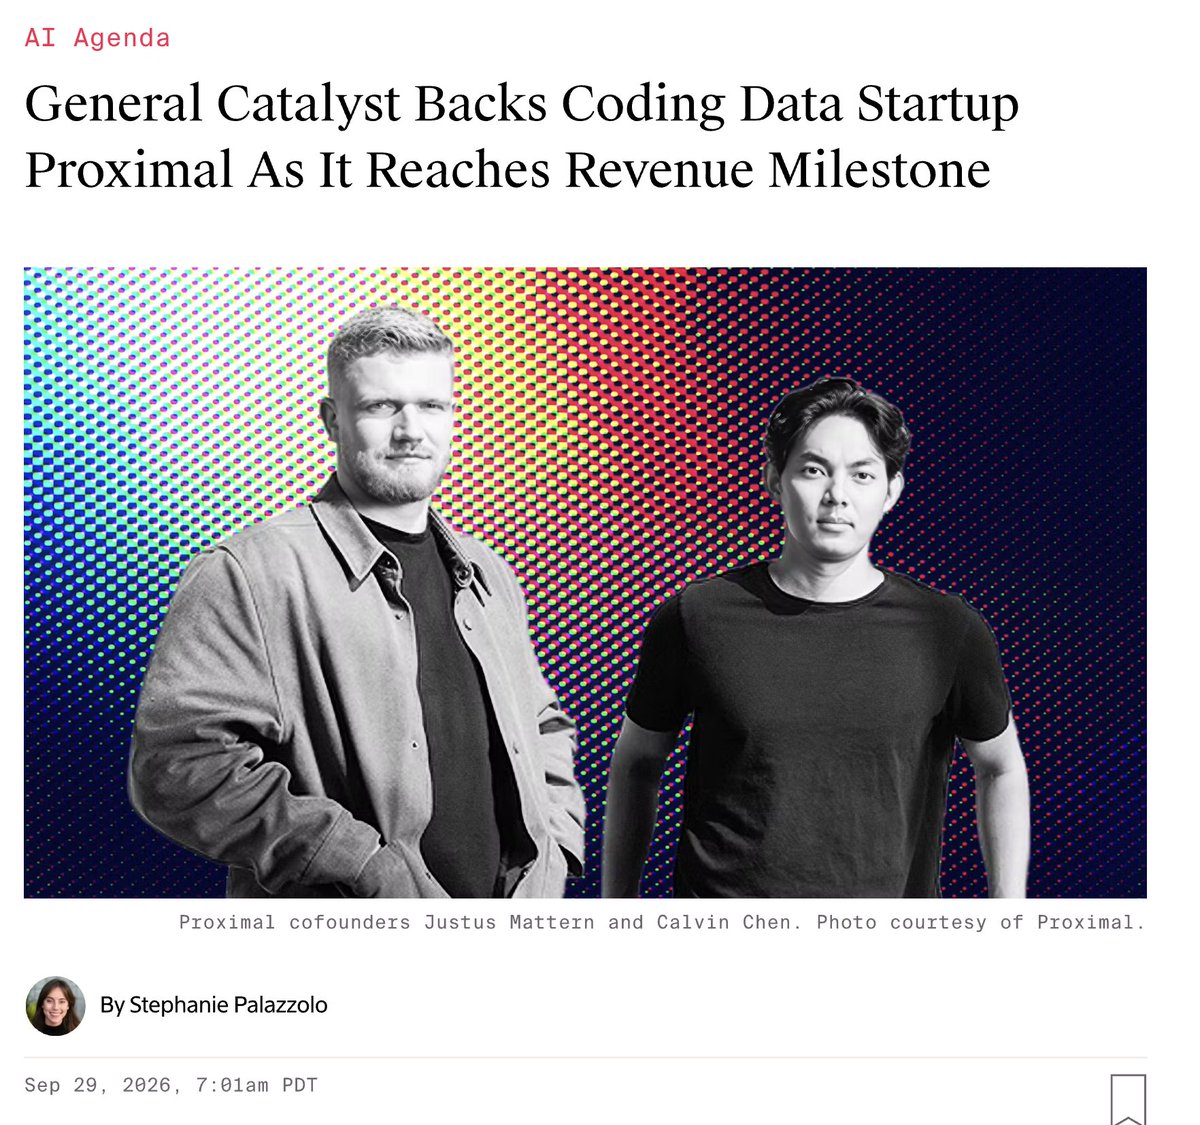
In the past year, we have grown to more than $200M in annualized revenue helping frontier labs and enterprises improve coding agents. Now, we are expanding beyond software engineering.
Recent progress in mathematics demonstrates what happens when models are trained in domains with massive amounts of public data and easy verifiability, making it easy to find weaknesses, generate training tasks, and iterate quickly.
We build infrastructure that enables this feedback loop in other domains: we are excited about a world in which AI systems design targeted drugs, accelerate chip design, and rewrite legacy software that still runs hospitals, power grids, governments, and other critical infrastructure.
Since starting, we have assembled a small team of researchers and engineers and built world-class infrastructure for post-training and synthetic data research to overcome the challenges of scaling manual data curation.
Our team comes from Cursor, Google DeepMind, Meta Superintelligence, Prime Intellect, Citadel, and Jane Street. More than half are former founders.
We’re fortunate to be backed by investors who share that vision, including @generalcatalyst who led our $15M Seed Round at a $300M valuation, as well as @chemistry, @svangel, @dvlamoen and individuals like @LiamFedus, @kevinweil, and @bernhardsson
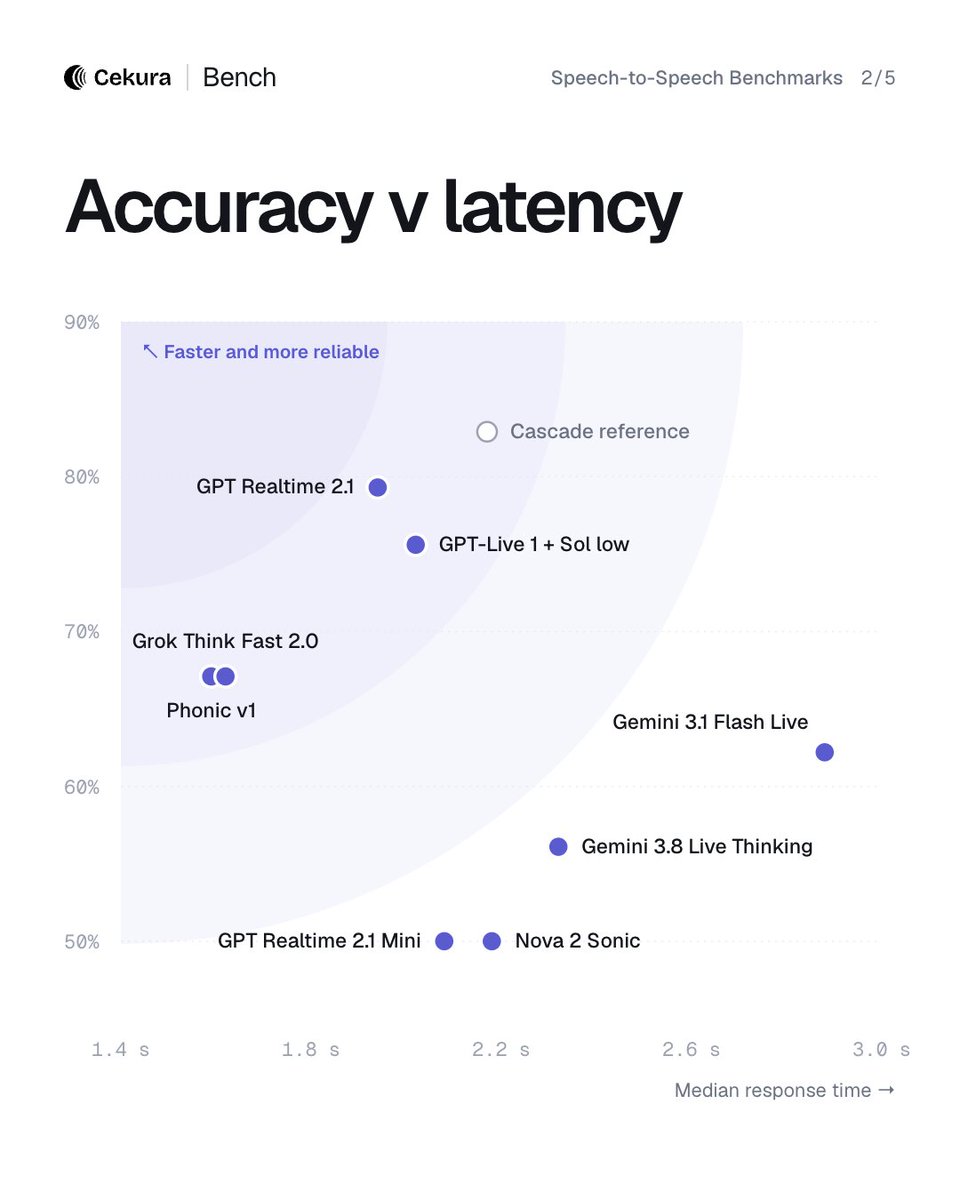
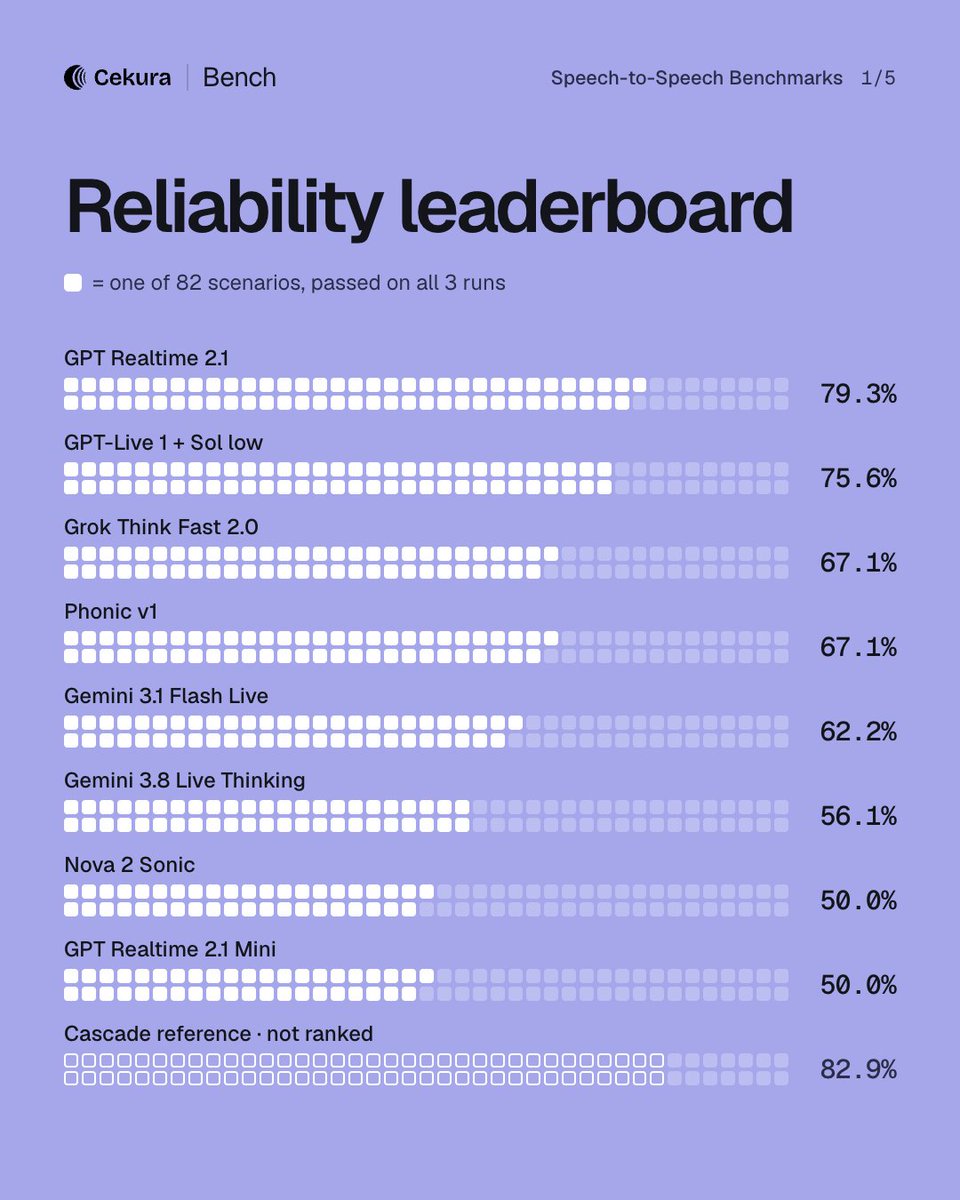
We’ve launched @cekuraAi's speech-to-speech benchmark, comparing eight realtime voice models across 82 scenarios and 2,214 live calls.
We tested models from @OpenAI, @Google, @xai, @amazon and @phonic_co. Every model ran on the same phone agent, with the same prompt, tools and phone line.
We also tested a cascade agent as a separate reference.
The calls covered two workflows: booking a clinic appointment and completing a longer Medicare intake. We ran each scenario three times and counted it as reliable only if the agent passed every time. It had to reach the right outcome and save the right information.
A few results stood out:
1. GPT Realtime 2.1 was the most reliable realtime model, passing 65 of 82 scenarios on all three runs. The separate cascade reference passed 68.
2. Phonic v1 was the fastest to respond, with a median response time of 1.59 seconds.
3. The type of call made a big difference. Five of the eight realtime models passed at least 85% of the shorter appointment scenarios. Only GPT Realtime 2.1 passed more than half of the longer Medicare scenarios on all three runs.
4. Amazon Nova 2 Sonic had the highest voice-quality score, but passed only 41 of 82 scenarios on all three runs. An agent can sound good while still missing a name or saving the wrong phone number.
We’ve published the results, methodology and call records so you can explore the comparisons yourself.
Take a look at the full benchmark here: https://t.co/UvHs1sceVD
We partnered with @FireworksAI_HQ to bring FrontierSWE v2 to the Specialized Intelligence Index
Evals are essential for improving and safely deploying AI. We're excited to support the initiative!
GPT-6 Astra is the best-performing model on FrontierSWE
Astra achieves a score of 65.5%, outperforming Fable 5.1 (56.3%) and its predecessor GPT-5.6 Sol (32.2%)
We are releasing FrontierSWE v2, our updated ultra-long horizon coding benchmark
V2 features an expanded task suite and improved methodology. We see large performance gaps between frontier models, with Claude Fable 5.1 leading by a wide margin
Everyone benchmarks the voice model.
Almost nobody benchmarks the stack around it.
So at @cekuraAi ran the same agent across 6 voice orchestration platforms:
Same prompt
Same tools
Same model
Same voice
59 scenarios X 3 runs each
The insights were equally powerful -
Fastest wasn’t most consistent.
Most consistent wasn’t best at interruptions.
Cheapest wasn’t always worst.
The right platform depends on your use case.
Full benchmark alongside the data is public - https://t.co/GWo3BoXVne
It is underdiscussed how essentially none of the public research around synthetic task generation is useful at the frontier
Current frontier models are so strong that none of the published synthetic data recipes yield tasks that are difficult enough to provide a learning signal
GLM 5.2 outperforms GPT-5.5 and on best@5 it only ranks below Claude Fable 5
Did not expect to see an open-weight model that is this good on FrontierSWE
Claude Fable 5 ranks #1 on FrontierSWE. This represents the biggest capability jump we have observed since releasing the benchmark
On many tasks, Fable 5 works productively for close to 20 hours and fully saturates tasks that were effectively out of reach for earlier models
We believe that better training data will come from creative research and engineering ideas, not from hiring annotators.
Here are some of the open problems we are working on:
Opus 4.8 fixes all the issues we observed with previous generations of Opus models.
It is much more token-efficient, better calibrated and it attempts to cheat much less than previous generations. Very impressive release!
GPT-5.5 is the best-performing model on FrontierSWE.
The model substantially outperforms Opus 4.7 in both mean@5 and best@5 rankings while working faster.