data center builders must design for the future of power-intensive racks if they want to capture AI demand
nvidia’s next rack (kyber) needs 600 kw, and data centers today are not built for this. the average rack in existing data centers gets about 8 kw. very difficult to increase power in a data center that's already built
the pattern is that each chip generation needs more power per rack.
- for nvidia, hopper was ~40 kw, blackwell at ~120 kw, and kyber will be at 600kw
the power shortage is more nuanced than the quantity of power. can power reach the racks that need it?
the biggest customers, like the labs, buy the newest chips first. to capture their demand, data centers should be designed differently
Excited to announce our collaboration with @Supermicro, the perfect partner to build and support inference racks powered by SambaNova SN50.
Our racks join Supermicro's Data Center Building Block Solutions portfolio. They fit the air-cooled data centers customers already run, next to the GPUs they already own. This first batch of SN50s is only phase one. Pumped for what comes next!
https://t.co/qTNaF3F3vF
Thank you @ClayMagouyrk for the shoutout at the Oracle AI World stage this morning!
We’re proud to bring fast, high-performance AI inference to @Oracle Cloud Infrastructure (OCI).
More on our partnership below ⬇️
LIVE from Oracle AI World!
SambaNova and @Oracle are collaborating to bring high-performance inference to Oracle Cloud Infrastructure (OCI).
“Our customers want the right infrastructure for every AI workload, and inference demand is growing fast. We plan to bring SambaNova’s RDU chips to OCI to give AI builders a high-performance, efficient way to run models at scale.” — @MThiagarajan_, President, OCI.
Full press release here: https://t.co/BEACDBXDwL
🚨 Big news today: We’ve raised $100M for our Series A! 🎉 🚀
We believe demand for fast inference is many times larger than demand for slow inference, and it’s about to go exponential.
Thanks to our co-leads @BlackbirdVC and @Abstractvc. Two visionary partners join our journey 🎉 🚀
Disaggregated inference is the future.
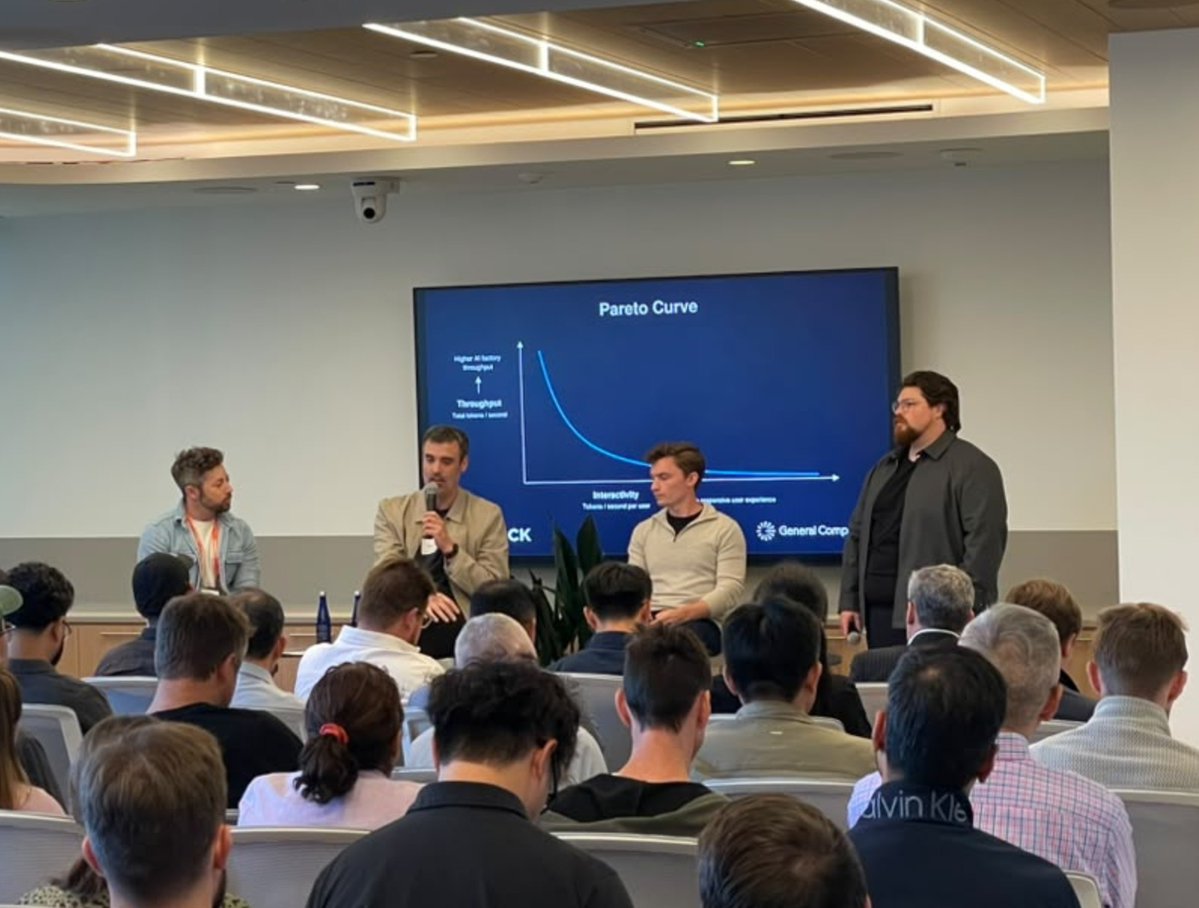
Great panel with @general_compute discussing their heterogenous compute cloud, the speciation of compute for disaggregated inference, and how thermo compute will fit in the picture
More coming soon. Stay tuned 😉
The primary reason for independence draft models falling out of favor was because they didn’t work well with GPUs because of launch overhead and verification cost. Both problems are being solved, the former through software and disaggregation, but latter through more flops relative to memory bandwidth in next gen GPUs. The only viable path to very long speculations windows is with all independent draft models. They will make a big come back.
A look under the hood of SN50.
@raghup17 took the stage at @hotchipsorg for a deep dive into the architecture behind our latest RDU and what it takes to scale dataflow for production inference.
Thanks to @RyanSmithAT for the great technical breakdown.
Read it here 👇
https://t.co/wbQmNWUolG
A look under the hood of SN50.
@raghup17 took the stage at @hotchipsorg for a deep dive into the architecture behind our latest RDU and what it takes to scale dataflow for production inference.
Thanks to @RyanSmithAT for the great technical breakdown.
Read it here 👇
https://t.co/wbQmNWUolG
@appenz@OpenAI Different models for draft and target decoding was how speculative decoding started and was literally the only technique used before DSv3 added MTP.
Come meet our awesome team after @hotchipsorg in Palo Alto!
📍 The Patio @ Rudy’s
*Hot Chips attendance NOT required
Register here: https://t.co/4PU9OZTObD
Many thoughts for @SambaNovaAI perspective...
Firstly, this is great validation that kernel-by-kernel execution models will never suffice for fast inference. CUDA is a kernel-by-kernel paradigm, so for fast inference, there is no CUDA moat.
Secondly, TileRT is dataflow emulation and use some of the same concepts we do in our compiler. However, doing this on hardware that has been built for kernel-by-kernel execution is inherently limited and this shows up in a few different ways. As described below:
1. Can they increase model parallelization to get faster? There is very little evidence of any GPU being able to scale tensor parallel beyond 8 GPUs, despite the fast that there is a 72-GPU scale-up domain readily available now. On InferenceX, no-high speed decoding use case uses more than 8 GPUs (data parallel doesn't count). In fact there is still a lot of HBM this is left unutilized in the TP8 mappings that TileRT has shown. Unless they can show an ability to saturate HBM bandwidth within a large model parallel domain, they will not keep up with true dataflow chips.
2. Can they batch without killing interactivity AND at long context length (truly Premium Inference)? TBD but my feeling is that this will be extremely difficult using dataflow emulation on GPUs, even on Rubins. On SN50, we will be able to reach the same speed with much higher batches per chip and at the 140K median context length that has become the default on InferenceX.
3. Can they generalize? The article rightly points out how hard it is to generalize - "a persistent engine kernel means the model is statically expanded ahead of time into one resident program". This is indeed extremely hard. We have been working on this problem for 9 years in our compiler. We haven't solved all these problems yet but are extremely well placed to be the first that does. We also have the right hardware target that makes the problem much easier than trying to retrofit GPUs to do this.
The most salient point in the article is the fungibility that this enables, but ultimately I think this will give buyers more reason to buy dataflow chips, as long as they do not over-specialize. i.e. if I am a AI inference provider and I buy some systems for prefill and high throughput decoding, and some systems to fast decoding, and my workloads change to require more fast decoding, I can reallocate my GPUs to service this demand with TileRT, albeit at a much higher cost per 1M tokens. Similarly, if the workloads move in the other direction and I need more high/medium throughput and low/medium interactivity, I should be able to reallocate my dataflow chips for this and offer good enough tokenomics. This is exactly how we think of the problem, as you need fungibility at the edges, not at the extremes, and you want to cover enough of the pareto curve to be able to adapt, but still enough specialization to differentiate.