this is pure f*cking gold for anyone running coding agents
Jev founder Diogo Amogo wrote a PDF on building a Jev harness
what it claims:
> 200x faster
> 400x cheaper
the model stopped being the bottleneck a while ago
the speed and the bill both live in the harness around it
• how to use it
> hand this PDF and the article below to Claude Code or Codex
> tell it to rebuild its own setup
one evening of Jev engineering
and next week your agent runs on a harness most teams haven't built yet 👇
I AM BACK!! In London to co-host the @DevinAI very first.... Devin Local cafe event — super excited to be having FOUR 3d printers for peeps to make their own keychains, and the best design will get their very own 3d printer!
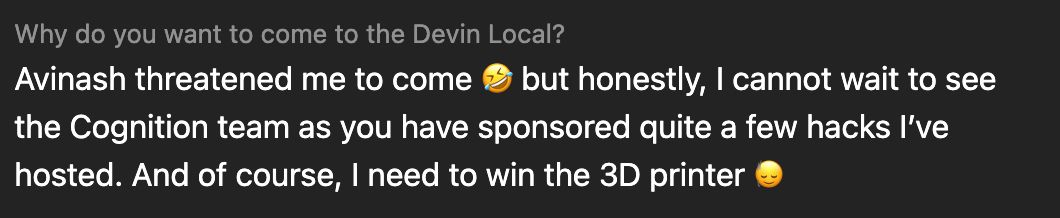
Btw, I saw this as @arukanism reason for coming; I promise I'm not threatening anyone....🙃😂 only a few days since announcing the event and we have had crazy interest! Can't wait to see my London peeps
https://t.co/oXRiUqnRYl
Next Systems club on the 12th of October. This is a room of 20-30 of the best engineers in London that care about systems, hardware, and performance.
Speakers ⬇️
- @kallyaleksiev from @inherent_labs - Presenting lessons from Faraday, the infrastructure built to train scientific intuition on top of coding agents and outperform leading models at research paper replication.
- @ismaeel_bashir_ from @ExpanseCompute - 538,000 production jobs on a national supercomputer say your users are over-reserving by 2–3x. Here's how to predict what they'll really need.
Link to register in the comments 🔗
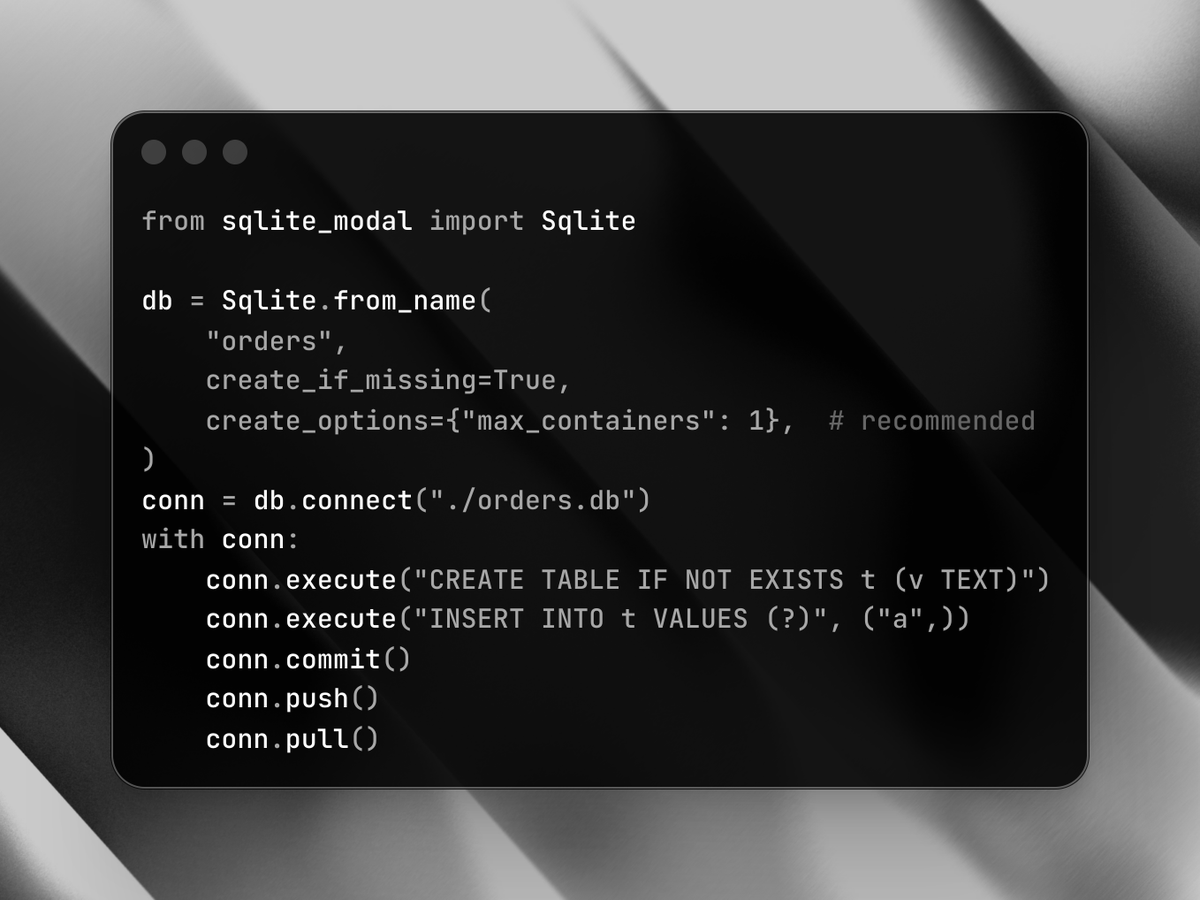
introducing sqlite-modal
i wanted a database primitive on Modal for a while, so I built this project!
sqlite-modal fixes this:
- push/pull sync.
- durable source of truth.
- no database server.
repo: https://t.co/iINA584vTn
cd /London Systems Club
NEWS: London Systems Club is back and this time with great speakers:
Jason Mancuso MTS, Research @modal :
Async RL rollouts eat 2-4x the compute of the trainer. Sparse delta compression makes weight sync cheap enough for rollout workers to scale independently from the training cluster.
Hamzah Chariwala Head of Compute Infra @CallosumAI:
Where Trainium2 actually wins and loses for LLM inference, and why workload shape and data layout decide which one you get.
@kennethnym MTS @PrimeIntellect :
Context as a variable: recursive language models, plus a live Prime Agent demo.
Luma Link: https://t.co/Sy4BepxXFy
Systems club next week on the 3rd in London. This is a room of 20-30 of the best engineers in London that care about systems, hardware, and performance.
Speakers ⬇️
- Jason Mancuso, @modal - Presenting Stitch, the version control plane for disaggregated reinforcement learning
- Hamzah Chariwala, @CallosumAI - A walkthrough of benchmarking accelerators to find out which chip is best suited to which workload shape
- @kennethnym , @PrimeIntellect - Diving into Prime Agent, which got ~96% on ARC-AGI 3
Link to register in the comments 🔗
hey folks,
we are back with anotha london systems club. might be our best one yet.
@kennethnym@PrimeIntellect on how they built Prime Agent (~96% ARC-AGI 3 🤯)
Hamzah Chariwala @CallosumAI on benchmarking accelerators across different workload shapes
@jvmncs@modal on Stitch, our versioned control plane for disaggregated RL.
https://t.co/gMsFXuHSyz