Training-free acceleration of Diffusion Transformers with dynamic sparsity and cross-step attention/MLP deltas--collaboration with @SohamGovande and @realDanFu!
⚡️ 3.7x faster video and 1.6x faster image generation while preserving quality!
🧵 Open-source code & CUDA kernels!
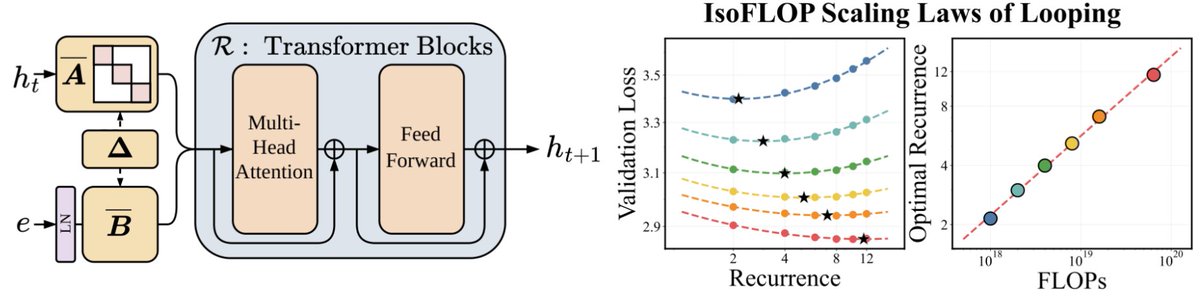
We’ve been thinking a lot about scaling laws, wondering if there is a more effective way to scale FLOPs without increasing parameters.
Turns out the answer is YES – by looping blocks of layers during training. We find that predictable scaling laws exist for layer looping, allowing us to use looping to achieve the quality of a Transformer twice the size.
Our scaling laws suggest that for a fixed parameter budget, data and looping should be increased in tandem!
🧵👇
AI is compute-hungry. While it has generally relied on a single hardware vendor in the past, AMD GPUs now offer competitive memory and compute throughput. Yet, the software stack is brittle.
So we ask: can the same DSL principles that simplified NVIDIA kernel dev translate to AMD? We’re excited to introduce the newest addition to the ThunderKittens cinematic universe of kernel DSLs: HipKittens (HK) 🚀for Fast and Furious AMD kernels.
Chipmunks can now hop across multiple GPU architectures (sm_80, sm_89, sm_90). You can get a 1.4-3x lossless speedup when generating videos on A100s, 4090s, and H100s!
Chipmunks also play with more open-source models: Mochi, Wan, & others (w/ tutorials for integration) 🐿️
Some updates to Chipmunk! 🐿️
Chipmunk now supports Wan 2.1, with up to 2.67x speedup - completely training-free!
The paper is up on arXiv - take a look to see more in-depth analysis of sparsity in video models. Only 5-25% of activations account for >90% of the output!
Training-free acceleration of Diffusion Transformers with dynamic sparsity and cross-step attention/MLP deltas--collaboration with @SohamGovande and @realDanFu!
⚡️ 3.7x faster video and 1.6x faster image generation while preserving quality!
🧵 Open-source code & CUDA kernels!
chipmunk is up on arxiv!
across HunyuanVideo and Flux.1-dev, 5-25% of the intermediate activation values in attention and MLPs account for 70-90% of the change in activations across steps
caching + sparsity speeds up generation by only recomputing fast changing activations
excited to keep pushing on dynamic compute allocation in DiTs!
potential for non-uniform step distillation with training-aware chipmunk, and autoregressive/streaming use cases with caching along video’s spatial/temporal dimensions https://t.co/RZFq3bMRZY
Training-free acceleration of Diffusion Transformers with dynamic sparsity and cross-step attention/MLP deltas--collaboration with @SohamGovande and @realDanFu!
⚡️ 3.7x faster video and 1.6x faster image generation while preserving quality!
🧵 Open-source code & CUDA kernels!
introducing chipmunk—a training-free algorithm making ai video generation 3.7x & image gen 1.6x faster! ⚡️
our kernels for column-sparse attention are 9.3x faster than FlashAttention-3 and column-sparse GEMM is 2.5x faster vs. cuBLAS
a thread on the GPU kernel optimizations 🧵
Super excited to share Chipmunk 🐿️- training-free acceleration of diffusion transformers (video, image generation) with dynamic attention & MLP sparsity!
Led by @austinsilveria, @SohamGovande - 3.7x faster video gen, 1.6x faster image gen. Kernels written in TK ⚡️🐱 1/
Our latest joint work w/ SandyResearch @ UCSD: training-free acceleration of Diffusion Transformers w/ dynamic sparsity, led by @austinsilveria@SohamGovande!
⚡️ 3.7x faster video and 1.6x faster image generation while preserving quality!
🧵 Open-source code & CUDA kernels!
Our latest joint work w/ SandyResearch @ UCSD: training-free acceleration of Diffusion Transformers w/ dynamic sparsity, led by @austinsilveria@SohamGovande!
⚡️ 3.7x faster video and 1.6x faster image generation while preserving quality!
🧵 Open-source code & CUDA kernels!
7/ Check out the blog and open-source code for all the technical details!
📚 Blog: https://t.co/rfzXJ9keAJ
📚 In-depth: https://t.co/XFYXtUgduu
⭐ Github: https://t.co/Q5JX2GsntH