@rdesh26 That makes sense. Feels similar to recent RL work on full-duplex spoken dialogue models, where RL is learning an interaction policy (when to speak, wait, yield, repair) rather than just minimizing latency. Reward design here seems really tricky.
Ref: https://t.co/Oi3OJYs5YF
ChatGPT and Gemini voice modes still inherit text-style optimization. They try to say everything in one turn, while voice works better across multiple short turns.
Starting to share more thoughts on AI, especially voice LLMs.
I’ve spent a lot of time thinking about realtime voice models, evals, and post-training, and I want to start writing down the small lessons I’m noticing.
I will be presenting my poster at ICML 2024! Join me on Tuesday in Hall C 4-9, poster #1316, to discuss my latest research paper titled "From Inverse Optimization to Feasibility to ERM." This work is done in collaboration with @sharan_vaswani and Anant Raj.
See you there!
Is it possible to achieve improvements by LLMs on synthetic multilingual data without affecting the performance on std LLM benchmarks?
We take a stab at this problem by proposing sPhinX: Sample Efficient Multilingual Instruction Fine-Tuning Through N-shot Guided Prompting to (1/n
# CUDA/C++ origins of Deep Learning
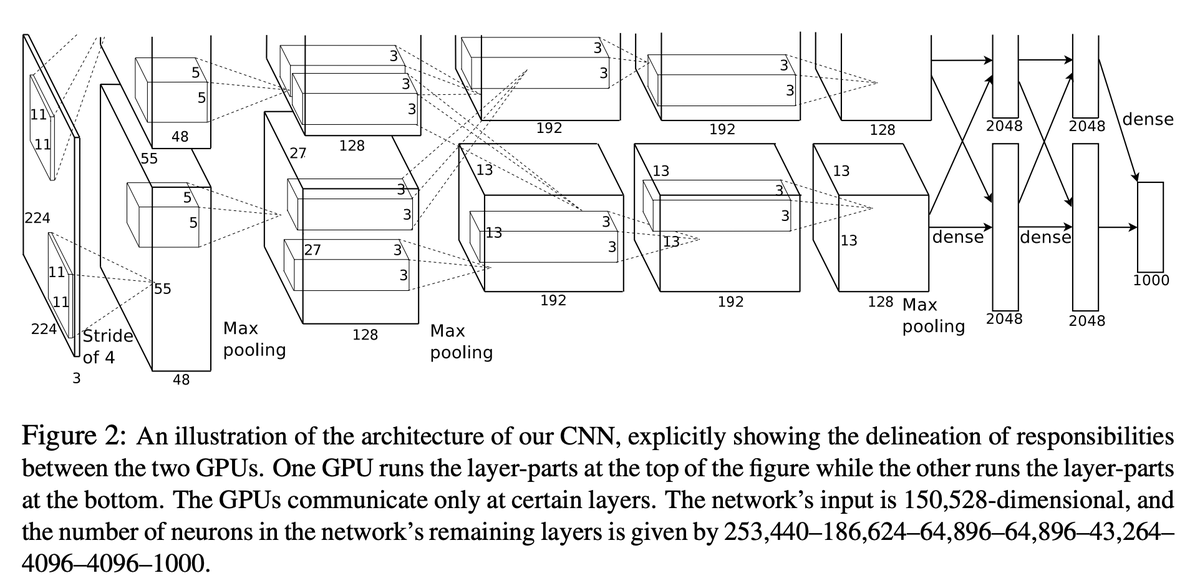
Fun fact many people might have heard about the ImageNet / AlexNet moment of 2012, and the deep learning revolution it started.
https://t.co/2xjLWODMOf
What's maybe a bit less known is that the code backing this winning submission to the contest was written from scratch, manually in CUDA/C++ by Alex Krizhevsky. The repo was called cuda-convnet and it was here on Google Code:
https://t.co/ch137VSYZ4
I think Google Code was shut down (?), but I found some forks of it on GitHub now, e.g.:
https://t.co/zYhzdUxoEN
This was among the first high-profile applications of CUDA for Deep Learning, and it is the scale that doing so afforded that allowed this network to get such a strong performance in the ImageNet benchmark. Actually this was a fairly sophisticated multi-GPU application too, and e.g. included model-parallelism, where the two parallel convolution streams were split across two GPUs.
You have to also appreciate that at this time in 2012 (~12 years ago), the majority of deep learning was done in Matlab, on CPU, in toy settings, iterating on all kinds of learning algorithms, architectures and optimization ideas. So it was quite novel and unexpected to see Alex, Ilya and Geoff say: forget all the algorithms work, just take a fairly standard ConvNet, make it very big, train it on a big dataset (ImageNet), and just implement the whole thing in CUDA/C++. And it's in this way that deep learning as a field got a big spark. I recall reading through cuda-convnet around that time like... what is this :S
Now of course, there were already hints of a shift in direction towards scaling, e.g. Matlab had its initial support for GPUs, and much of the work in Andrew Ng's lab at Stanford around this time (where I rotated as a 1st year PhD student) was moving in the direction of GPUs for deep learning at scale, among a number of parallel efforts.
But I just thought it was amusing, while writing all this C/C++ code and CUDA kernels, that it feels a bit like coming back around to that moment, to something that looks a bit like cuda-convnet.
@united Wth is happening. My flight got canceled and got automatically rebooked to a random origin and destination ! I'm unable to even change my flight or cancel my flight! Please show some kindness and pick up the customer service calls and resolve this asap!
Information is only bad when:
- You have too much
- You don’t write with it
- You don’t build with it
The right information, when understood, helps you make better decisions.
And that’s all success is, the right sequence of good decisions.
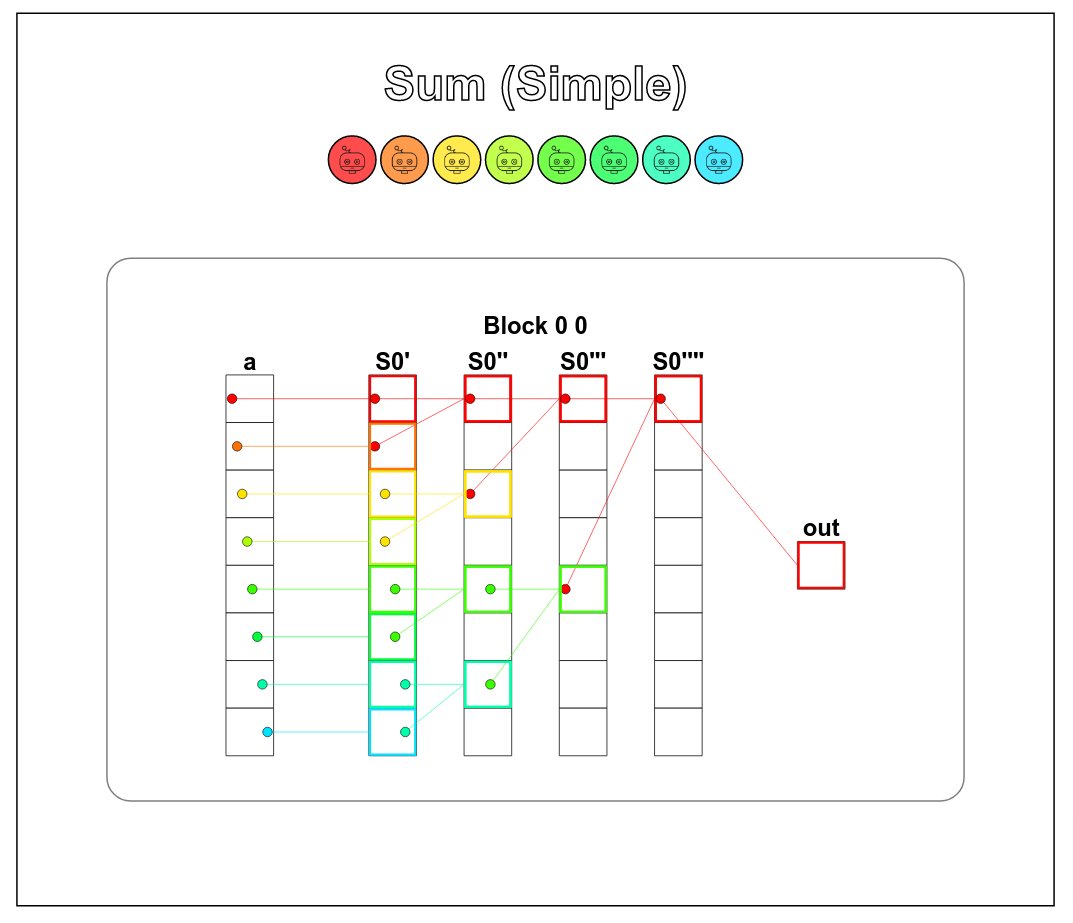
You use GPUs everyday, but do you (actually) know how they work?
GPU-Puzzles (v0.1) - 14 short puzzles in Python with a visual debugger. No background required. Do puzzles, learn CUDA.
Link: https://t.co/Yk1lWRqilN