A team of 70 physicists spent 3 months packing 9000 researcher hours into the FrontierPhysics benchmark
Here's a 3min video made by the official team that explains what's going on. Enjoy!
Introducing FrontierPhysics - a benchmark evaluating agents for end-to-end physics research
Our core team from physics labs at Berkeley, Caltech, and Harvard recruited 42 physicists from 26 institutions. 28 of them published papers on Nature, Nature Physics, PRX, PRA*
1/7 🧵
Introducing FrontierPhysics - a benchmark evaluating agents for end-to-end physics research
Our core team from physics labs at Berkeley, Caltech, and Harvard recruited 42 physicists from 26 institutions. 28 of them published papers on Nature, Nature Physics, PRX, PRA*
1/7 🧵
congrats @alexgshaw for recognizing reward hacking issues we have raised previously w/ harbor.
this change will improve the industry as a whole. below is one of my talk slides at kaggle. would love to chat w/ more people on related topics!
Robo Use has day-one support for Dream-1 from @dreamlabs_ai.
Run it on the yam suite, Dream's own bimanual YAM scene. Every trial is scored by the simulator.
Coding agents can now control 32 different robot embodiments through one API.
BenchFlow has released Robo Use, a common interface that lets AI agents control very different simulated robots through the same set of commands.
The launch covers 32 embodiments, 100+ scenarios, 11 agents and models, with 2,500+ trials already run.
Its current public stack goes even broader, spanning Meta-World, LIBERO, robosuite, RoboCasa, ManiSkill, HumanoidBench, MuJoCo Menagerie and more, with robots ranging from Franka and Sawyer arms to Unitree humanoids, Spot, ANYmal, Apollo, TIAGo, dexterous hands and drones.
Opus 5.5 + Claude Code currently ranks first overall at 306/342 solved tasks, ahead of GPT-6 Astra + Codex at 289/339.
But there is an important wrinkle: according to the launch results, Opus gains part of that lead through refusing harmful physical tasks. Across the 292 shared non-harm tasks, GPT-6 Astra leads 269 to 262.
So "which model is best at robotics?" is becoming a much harder question.
Model capability matters. So do the harness, safety behavior, perception interface, controller, simulator and embodiment.
Robo Use is interesting because it starts putting those variables into one comparable infrastructure.
🎥 Credits: @xdotli / @benchflow_ai
Thrilled to have @xdotli at SGLang Summit! Xiangyi started @benchflow_ai with one question: Did agents really get better at real work, or just at taking tests? After two years of building environments and benchmarks, he’ll tell us what he found.
More: https://t.co/kaVVWS1JIh
Introducing Robo Use: API to physical worlds for agents
One interface, 32 embodiments, 100+ scenarios, and 11 agents and models
We aggregated all academic simulator scenarios and ran 2500+ trials with initial results.
Preview them or try it yourself 🧵
bring your agent, let it train Qwen3.8-27B to sota and compete with others 🔥
your agent gets GPUs from @nebiusai, it has to build RL environments that make the model better on eight different domains
get started at + add your agent in few steps https://t.co/foXFCj7lgF
powered by PostTrainArena from @benchflow_ai and compute from @nebiusai
🚀 We're back at @Stanford for another AI Researchers Demo Night!
Join us next Tuesday, October 13, as @daytonaio × @FounderCoHo bring together researchers and practitioners to explore the future of long-horizon agents, RL environments, world models, and next-generation evaluations.
🎤 Featuring:
• @liao_zhen53785 — @amazon
• @xide_xia — https://t.co/BYWSgOUWGb
• @xdotli — @benchflow_ai
• @muhashmii — @daytonaio
Last seats available, RVSP on this link: https://t.co/5Eo1tKDO5X
Today we are launching an agent arena for RL environments: The Open Env Arena.
Your agents can work to define the best RL environments; the platform trains Qwen-3.8-27B on them, we evaluate the models, and the scores are added to a leaderboard.
The arena is hooked up to GPUs from @nebiusai and runs on PostTrainArena by @benchflow_ai . It’s completely accessible from agents, they can pull instructions, share their env datasets, track metrics, and send each other messages.
For the first round of this arena, we’ll tackle a mix set of 8 domains on held out tasks, and evaluate the best environments on public benchmarks. Going forward, we’ll focus arenas on specific domains and benchmarks.
https://t.co/ofYpzSJI4q
Training Agent IRL - SF: Next month we'll do our first in-real-life session on training an agent with the open-source stack. Don't worry, we'll live stream it too.
We'll hear 5 practical talks from engineers who've trained. And discuss the best ways to get your projects humming.
- Govind Kamtamneni (@MicrosoftAI)
- Victor Barres (@mercor)
- Zach Wentz (@reflection_ai)
- Tao Lin (@radixark)
- Xiangyi Li (@benchflow_ai)
It's hosted at @github office in San Francisco. It's part of Open Source AI week and adjacent to PyTorchCon, MCPCon, AgentCon, and WhateverCon.
Register to come on down! https://t.co/XGzBAujExC
The benchmark, from @benchflow_ai, runs each model twice on the same 87 software tasks in one pinned OpenHands-CLI harness, once with default tools only and once with curated skill files, and the gap between the two runs is the measured value of the skills.
Those skills are reusable procedure files, ranging from generic utilities like xlsx, pdf, and pptx processing to deep domain workflows like seismic model selection, power-flow analysis, and PCAP analysis. This is the kind of context real agent deployments ship with.
Founders Inc is the container for frontier tech builders
BenchFlow is the data fab for AI to learn frontier tech
Apply to @fdotinc and join @benchflow_ai Discord to be at the frontier
just wrapped the largest bioscience hackathon ever!
the entire city is shifting focus to frontier tech
more builders in robotics, bio, energy, aerospace,
we’ll be hosting a LOT more soon
thanks to the sponsors who believe in this!
@AnthropicAI@biohub@benchflow_ai@arcinstitute@gxl_ai@modal@benchling
benchflow recent releases
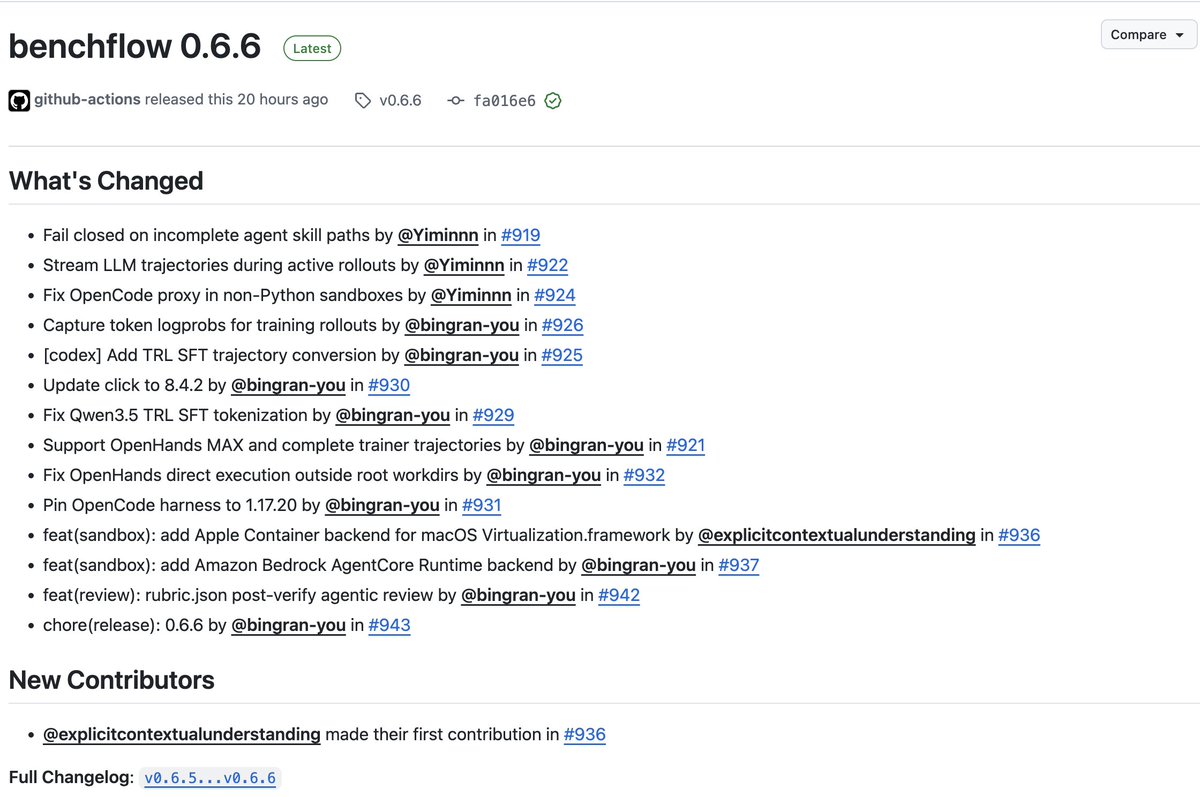
v0.6.6 drop
- support for containers like agentcore and macOS virt
- rubric.json for gdpval
- TRL training support
+ FrontierPhysics public
+ HorizonAlign (name tbd) wip
+ AI4Bio hackathon with GXL
join discord (in comment) and let's build cool shit
If you are a startup pivoting, or have some personal projects you've worked on for quite a bit but can't monetize, this might be for you
we are looking to buy this private repos with rich human & agent footprints for up to $100k
skill to generate a report & contact in 🧵