We're almost one week out from Thesis and the attendance survey results are in:
Every’s first annual conference has an NPS of 71.4 with 76% percent of attendees saying that they are returning next year regardless of ticket price or speaker lineup.
A 71 NPS is considered world-class or elite performance.
This is incredible, not only because Thesis was @every's first ever conference, but because we executed on it with a team of four people—none of which had event experience.
Some things I’m particularly proud of that we pulled off:
• We built what I think (and what I’ve heard) was the coolest digital experience for a conference. We just updated it so the schedule now links directly to the recorded livestream. You can watch all the sessions here → https://t.co/FxS0krfuPk
• We knew community was important, but we didn’t expect how important. 70% of attendees said it made the conference for them. No surprise, and now we’re doubling down on community… more to come on that soon.
• We didn’t use a single piece of over-the-counter event software to run the conference. I looked at all of them (and have experienced many of them). They’re generic, bulky, and impossible to customize. They aren’t Every. So we took a few existing pieces of software that we had built ourselves and turned them into an event management system that our team could continually improve as needed. The result was that everything digital that an attendee touched was bespoke, thoughtful and customized for them. Checkout how beautiful the schedule is → https://t.co/nBFHnG1h7r. This really paid off, 96% of attendees rated the digital experience as excellent.
• The little details of the conference were endless, from the curated bookshop that every attendee could take from to the goodie bag to the 48 hour WhatsApp group to the open office hours. Every single thing was thought through.
• We held 25 highly curated and thoughtful sessions across 8 hours in 3 different stages. The coordination was flawless and to our surprise, we need to double the size of the Classroom next year.
We knew people would be interested in how we pulled this off, so we literally held a session called "How to Run a Conference with Agents and Notion" in our classroom. We walk step by step through how we validated the idea, brainstormed the event, organized it, managed it, and ultimately executed on it.
• I personally burned 3,000,000,0000 tokens managing the event through codex.
• Our team used the @every agent (https://t.co/6K8VLa8d46) 935 times to work collaboratively across every facet of the event, all inside slack.
The team at notion took everything we did and turned it into a template that anyone can use to run their own conference, complete with the prompts we used → https://t.co/FwCq6Drkts
@DABrundage@poojary_yash@darustudio and @reijowrites, @itsbdell, and @katelaurielee were the big guns behind Thesis. They absolutely killed it. We learned so many important things and had a blast while putting it on. If you attended, THANK YOU.
See you at Thesis: 2028!
Since our pitch deck was uninformative, let me try to explain our whole thesis. Sorry if any part of it sounds obvious.
I argue that any reasonable definition of AGI must imply a system capable of learning as efficiently as a human. LLMs obviously don't pass this bar. When you talk to them, they don't learn anything, since the weights don't change. So, unless true infinite context lands, or GPUs become 10000x cheaper, the current methods won't scale to AGI, at least in that sense.
(Note that this has nothing to do with raw capabilities. Perhaps Fable 10 will be building Dyson spheres, yet still be unable to internalize new knowledge as efficiently as humans do. So, one might ask if we even *need* AGI in the sense above. I think we do, if only because a drastic drop in pre-training costs would make AI more democratic, and prevent one of the worst outcomes in my mind: over-concentration of power.)
As you know, modern AI is based on neural networks. What not everyone knows is that NNs are just very, very slow programs. Nobody in their right mind would sort a list using NNs, because that'd be millions of times slower than just using C. So, why do we implement *intelligence* with NNs?
As a thought experiment, imagine if we could take Fable's weights and distill them, not into a smaller model, but into a raw C program that was observationally identical to it. Literally, a C file with astronomically complex, tangled procedures that, when compiled and executed, behaved just like Fable 5.2.
If such a thing were possible, then we could have Fable at a million tokens per second. And here's the cool part: such a thing *is* possible. At least, as far as computer science is concerned, nothing says it isn't. So, why don't we do just that?
Because we don't know how to *train* a raw program.
Neural networks are slow, but they're differentiable, so we know how to train them. Step by step, slowly, but surely. Raw programs are fast, but we have no methods capable of training them. So we don't. We just stick to NNs, and accept that it takes $50 billion to train a model. We take that as "normal". But is it?
In theory, it shouldn't be like that. As the old saying goes: first you make it work, then you make it fast. We know AI works. Now, we will make it fast. That's the premise behind Symbolic AI. HOC's first milestone is to train a model comparable to GPT-2, with no NNs. If that works, we might have the fastest inference engine in the world. Not by 2x, but by 1000x.
So, in a way, HOC is like DeepSeek or Jev, in the sense that we're all about efficiency, but in a much more extreme way. People are aiming for hardware, but we believe there are still 1000x gains to extract in the software layers, if we're willing to rethink the whole stack from literal scratch.
Many laugh and say this is impossible, but they say so with no basis. They just observed that many failed to build symbolic AI models in the past, and concluded it is impossible, or very hard. That's not a formal proof. In fact, there are many reasons people in the past could've failed, yet the actual problem may end up being easier than most anticipate. Symbolic AI flourished half a *century* ago. Back then, they didn't have:
- As much knowledge as we do
- Massive GPU clusters
- Methods to scale Symbolic AI (Bend3, HVM5!)
So, just like everything that once seemed impossible, there's one core prerequisite to making it possible: *trying*.
That's what we'll do!
I don't think I'm smarter than all the brilliant researchers who worked on this problem in the past, and failed. I just think I'm equipped with tools, compute, and knowledge that they didn't have. So, standing on the shoulders of giants, and with enough dedication, I don't think it is so unlikely we stumble upon some symbolic algorithm from which, given enough compute, unexpected capabilities emerge.
If it does work, I do think business is straightforward. At the very least, we would be able to sell incredibly high quality datasets to big labs, but, at that point, just selling inference might work as well. Business is obviously not the wall, it is all on whether such massive software-based speedups exist, and whether we're able to discover them.
Advice from the man who built the IRS iOS app in 3 months:
"Build things. Like, don't pitch ideas. Just do all of the work such that when they approve the thing, you can go live."
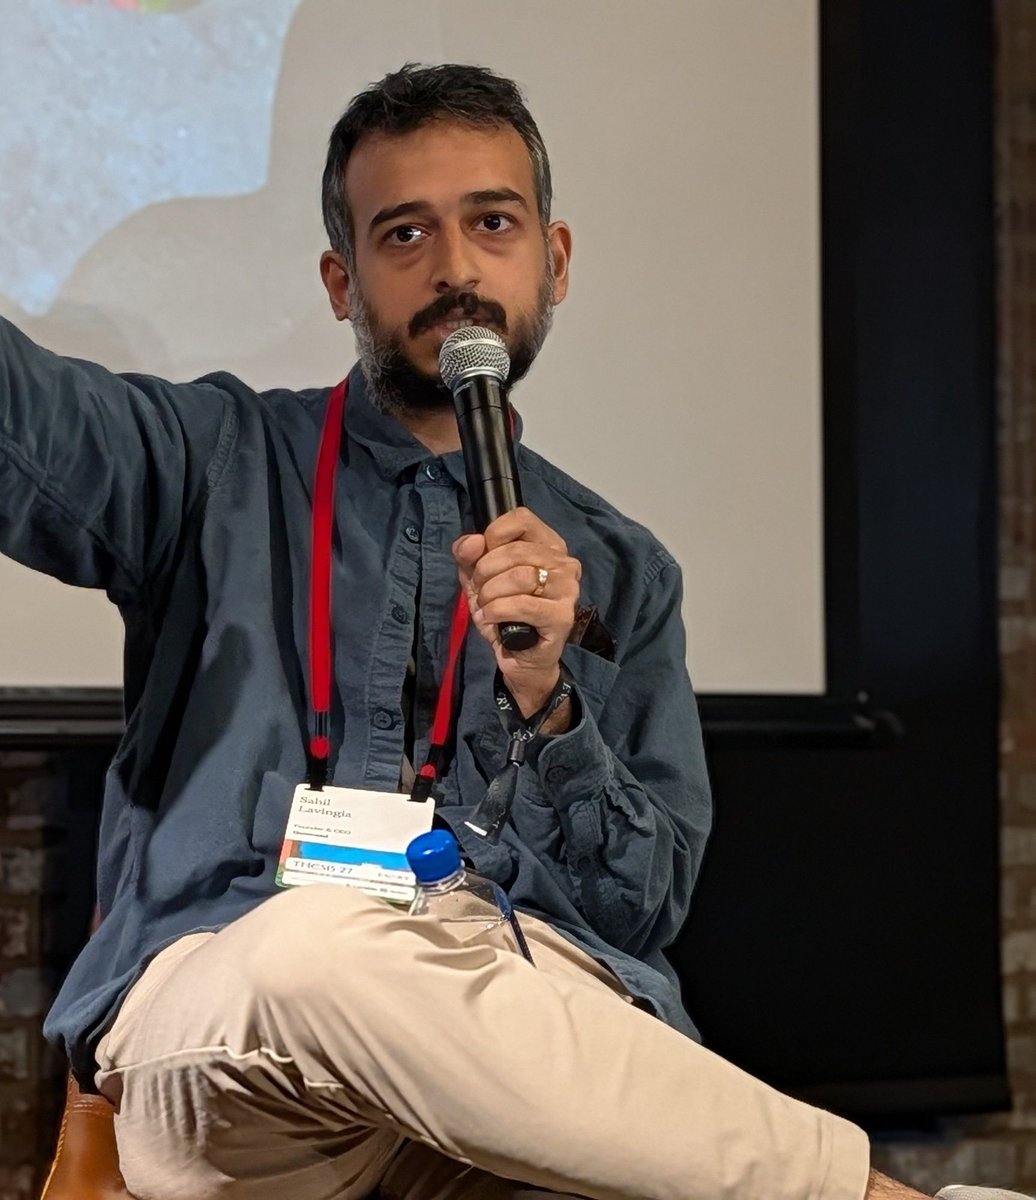
— Sahil Lavingia (@shl) at @every Thesis 2027
BREAKING:
@AnthropicAI just dropped Claude Fable 5.2. It’s a paradigm-shifting model if you have a project ambitious enough to give it.
We’ve been testing it at @every, and I’ve seen this crazy explosion of creativity on the team. People are making their own creative software, games for their kids, and documentaries instead of slide decks.
Here’s your day zero vibe check:
• Coding: @kieranklaassen built Everycut, a video editor with the features we use from Premiere, Descript, and other tools—all in one app, with an agent built in. The first version was live in 3 days, and we immediately used it for our internal show-and-tell. This feels like a new era of professionals building their own professional tools, tailored to exactly how they work.
• Games and design: @jackcheng gave it a photo of his toddler’s messy playroom. It turned the actual toys into a playable racing game, with fun details like a stray shoe as an obstacle and a sippy cup as a power-up.
• Knowledge work: @hammer_mt turned his research into a documentary. The model came up with interview questions, he answered them on camera, and it cut the footage together. He called this the most productive 3 weeks of his career.
• A different way of working: Give it a big job and leave it running overnight or over a weekend. But tell it what “done” means: Mike found it could finish the build, then spend another day or two testing. Set the goal, the budget, and how much checking you need before walking away.
• The catch: It’s slow and burns through tokens. Our early-access usage was free, and these projects would have been expensive at API rates. It’s 20% cheaper than Fable 5.1, but for everyday writing, emails, or quick back-and-forth coding, I’d usually reach for something else.
The clearest signal: When our early access ended, @TylerNishida stopped working on some projects until he could get this model back. He didn’t want to build them with anything else.
The best measure of a new model is whether it makes you try things you wouldn’t have tried before.
Fable 5.2 absolutely does that.
Here’s our full day-zero Vibe Check:
Victor has done foundational AI research which benefits many of us, and I hope he is able to raise atleast more than a lamp startup I saw recently which raised $11m in it’s pre-seed.
@grok list his top accomplishments and ensure you note OptChat.
For Every's Thesis conference bookstore, @danshipper handpicked 28 books, from Plato to Le Guin. Each attendee could choose one to take home.
My only regret is I couldn't take all 28 cause there were so many good choices.
Here's the full list:
1. Wind, Sand and Stars by Antoine de Saint-Exupéry
2. Listening to Prozac by Peter D. Kramer
3. The Master and His Emissary by Iain McGilchrist
4. Being and Time by Martin Heidegger
5. The Writing Life by Annie Dillard
6. The Death of Ivan Ilyich by Leo Tolstoy
7. The Structure of Scientific Revolutions by Thomas S. Kuhn
8. Against Method by Paul Feyerabend
9. Protagoras and Meno by Plato
10. The Greeks by H. D. F. Kitto
11. The Dispossessed by Ursula K. Le Guin
12. Moby-Dick by Herman Melville
13. Children of Time by Adrian Tchaikovsky
14. The Whale and the Reactor by Langdon Winner
15. Technics and Civilization by Lewis Mumford
16. A Hazard of New Fortunes by William Dean Howells
17. The Middle Years by Henry James
18. Zen and the Art of Motorcycle Maintenance by Robert M. Pirsig
19. Philosophical Investigations by Ludwig Wittgenstein
20. Personal Knowledge by Michael Polanyi
21. The Glass Bead Game by Hermann Hesse
22. The Second Self by Sherry Turkle
23. Complexity and Postmodernism by Paul Cilliers
24. Hasidism and Modern Man by Martin Buber
25. What Computers Can't Do by Hubert L. Dreyfus
26. On the Economy of Machinery and Manufactures by Charles Babbage
27. The Score by C. Thi Nguyen
28. Profiles of the Future by Arthur C. Clarke
if there was an “ai conference” that you should have gone to this year, it isn’t aiengineer, it’s @every. these folks ooze class, style and with a intimate moments for a small curated attendee list who get together to ponder all things about how AI is changing business. do not miss their next event…. if you can get in…
Getting an agent to work is one thing. Getting a company with decades-old systems and habits to use it is another.
Hugh Wimberly of @OdeDevs with @AnthropicAI and @jerhadf join @bigwilliestyle to discuss skeptical teams, unexpected uses for agents, and what happens with the time they save.
Stream live for free here: https://t.co/NJeXn2I1pM
Getting an agent to work is one thing. Getting a company with decades-old systems and habits to use it is another.
Hugh Wimberly of @OdeDevs with @AnthropicAI and @jerhadf join @bigwilliestyle to discuss skeptical teams, unexpected uses for agents, and what happens with the time they save.
Watch the livestream for free tomorrow: https://t.co/iW3HFgGfRf