@cmuratori@trashh_dev@thestanduppod Cheesy gordita crunch, quesarito, cheesy fiesta potatoes, crunchwrap supreme. One for each major form factor (taco, burrito, cup, hexagon). Load up on all the sauce packet types. Don't be afraid of diablo; it's not that hot.
@MT_6226 Underrated strat for ethnics, play against type. Darius in sweater and glasses in a cocktail bar, Arjun shirtless and ripped on a boat. Jack will get the most swipes but Mateo is a dark horse for most enthusiastic messages
@TheGingerBill@KelseyTuoc@allie__voss `1 - (1-p)^n` computes P(at least one sentence flagged | human doc) but you saying "being flagged as 100% AI" implies you're talking about P(all sentences flagged | human doc).
@TheGingerBill@KelseyTuoc@allie__voss FYI my post earlier was false _discovery_ rate, false positive rate is out of 10K human docs one is wrongly marked ai
@TheGingerBill@KelseyTuoc@allie__voss Just so we're on the same page which FPR do you think Pangram is claiming and which is relevant?
A: For any single human doc, <0.01% of its sentences get flagged
B: Across all human docs, <0.01% of sentences get flagged
C: Across all human docs, <0.01% get flagged
@TheGingerBill@KelseyTuoc@allie__voss Again to have some idea of what the "real" false positive rate is you must have something more rigorous than it marked my asm in odin post wrong therefore it's extremely high. I would bet it's well below 1% but my N is not high enough to distinguish below that.
@TheGingerBill@KelseyTuoc@allie__voss You're saying off by 3% should be counted the same as off by 100%? I don't think that's sensible. But suppose one character in the whole document being misclassified is too much error, what do you think is the *real* false positive, what would be false positive rate is "good"
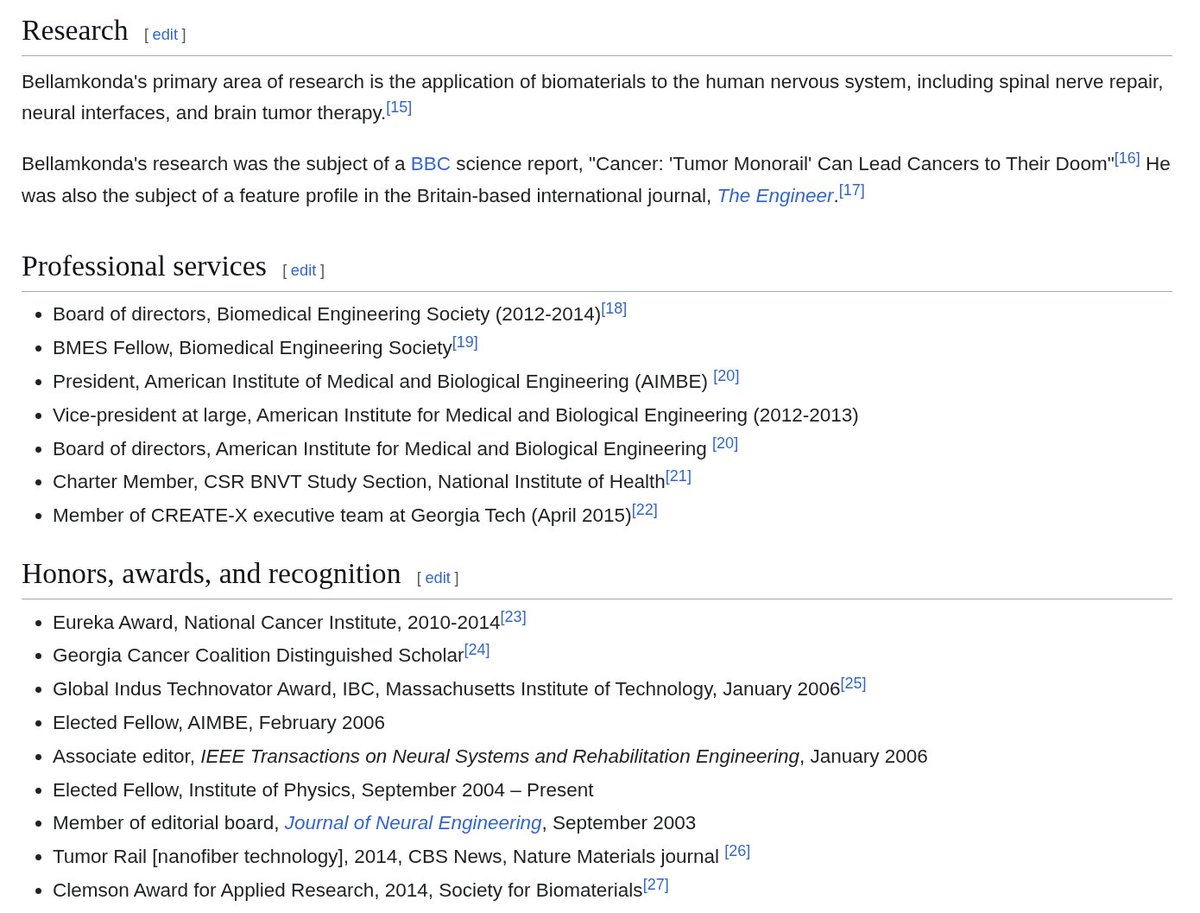
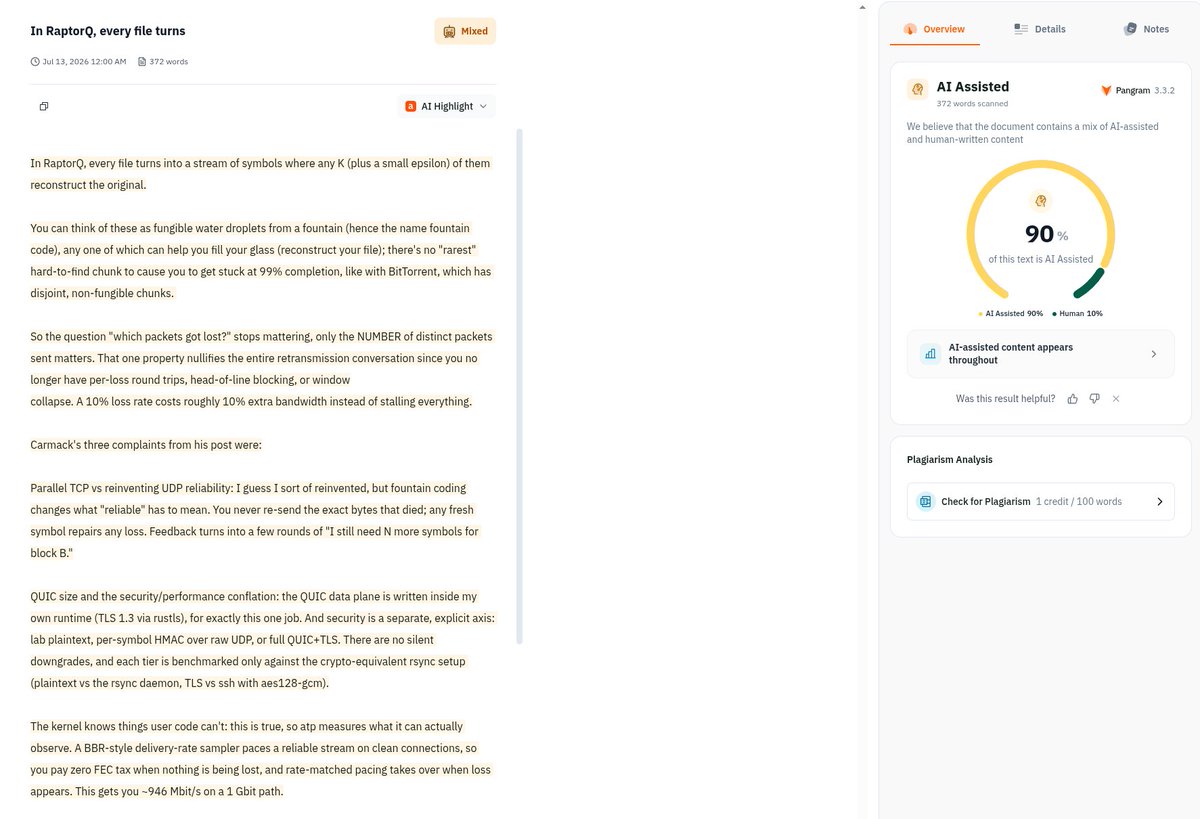
@TheGingerBill@KelseyTuoc@allie__voss My point is this, the false positive rate is low in practice. The mixed case is rare and is a cue for any sensible person to do further digging. In the first example the cutover is obvious in hindsight, in the second it was enough for me to dig around the guy's bio.
@TheGingerBill@KelseyTuoc@allie__voss And here's a technical one https://t.co/2PYyEB9LGb, only one I've personally encountered that's "ai assisted". You might be inclined to give him the benefit of the doubt but look at his website: https://t.co/UgkQkfyac0. False positive or deep in the throes of slop-psychosis?
This is all possible because of the genius of RaptorQ fountain codes (RFC 6330), which I've written about before here:
https://t.co/7kCSDJHX7N
In RaptorQ, every file turns into a stream of symbols where any K (plus a small epsilon) of them reconstruct the original.
You can think of these as fungible water droplets from a fountain (hence the name fountain code), any one of which can help you fill your glass (reconstruct your file); there's no "rarest" hard-to-find chunk to cause you to get stuck at 99% completion, like with BitTorrent, which has disjoint, non-fungible chunks.
So the question "which packets got lost?" stops mattering, only the NUMBER of distinct packets sent matters. That one property nullifies the entire retransmission conversation since you no longer have per-loss round trips, head-of-line blocking, or window
collapse. A 10% loss rate costs roughly 10% extra bandwidth instead of stalling everything.
Carmack's three complaints from his post were:
Parallel TCP vs reinventing UDP reliability: I guess I sort of reinvented, but fountain coding changes what "reliable" has to mean. You never re-send the exact bytes that died; any fresh symbol repairs any loss. Feedback turns into a few rounds of "I still need N more symbols for block B."
QUIC size and the security/performance conflation: the QUIC data plane is written inside my own runtime (TLS 1.3 via rustls), for exactly this one job. And security is a separate, explicit axis: lab plaintext, per-symbol HMAC over raw UDP, or full QUIC+TLS. There are no silent downgrades, and each tier is benchmarked only against the crypto-equivalent rsync setup (plaintext vs the rsync daemon, TLS vs ssh with aes128-gcm).
The kernel knows things user code can't: this is true, so atp measures what it can actually observe. A BBR-style delivery-rate sampler paces a reliable stream on clean connections, so you pay zero FEC tax when nothing is being lost, and rate-matched pacing takes over when loss appears. This gets you ~946 Mbit/s on a 1 Gbit path.
I spent an enormous amount of energy building a test and benchmark harness for atp to compare it against rsync in a way that's maximally fair to rsync. In this harness, a false win is structurally impossible because of all the precautions: hermetic network namespaces, netem rate+delay+jitter+loss applied on both ends, SHA-256 verification of every single transfer, medians of 3 to 5 reps.
The results of all this testing are as follows:
500 KB transfers run 2.9 to 4.8x faster than tuned rsync in every link regime. The toughest test cell (10% loss, 5% reorder, 200 ms RTT) comes out around 1.9x faster than rsync.
On a clean 1 Gbit, 500 MB file: 4.52 s vs 5.13 s.
Where rsync still wins (huge single encrypted files on pristine links, sender RAM under heavy loss), the README prints it in the same table.
All 230+ numbered experiments exist in an append-only evidence ledger, including every optimization hypothesis that failed (my negative evidence ledger concept that I've written about before in my FrankenSQLite post).
And there's a feature that a single TCP stream can't do at all: bonding. Machines that hold the same file can all feed one receiver at once, each spraying a disjoint slice of the same fountain. Duplicates are impossible by construction, and if a donor dies mid-transfer, its repair windows get reassigned to the survivors.
If you move a lot of files around between machines, both within the same local network or over the internet, you should seriously check atp out, because it's better.
And you don't even have to spend time figuring out how to use it yourself, because the installer offers to (optionally) include a highly agent-intuitive and agent-ergonomic skill for you that teaches your agents how to use atp most effectively, including how to install it to all your ssh accessible machines you already have set up, since it needs to be installed on both ends, and how to use it with bonding.
You can install it on Linux and Mac with this one-liner (there's another one given in the README for Windows):
curl -fsSL https://t.co/e6rufFhDWt | bash