We hired a CS grad last month who genuinely thought writing clean algorithms from scratch was what got you promoted.
He spent 3 days writing a custom parser. I showed him how to do it in 20 seconds with claude, wrapped in an API, and told him to go hit the gym
He looked like his childhood was ruined.
Computer science degrees are officially liberal arts degrees now. Modern tech is just plumbing.
NEVER thought i would hear this from jeff dean
he thinks we can compress chip design from 2 years to 3 months with RL + new EDA tooling
essentially just by a specialized auto research loop for hardware!
super smash bros melee is fully decompiled, this project started in july 2020, so it took over 6 years. the progress was hugely accelerated by llms and finished off with astra. it's a very large game with 3.88mb of compiled code.
https://t.co/RKmrtwYZWl
Sending lots of love to the Apple community on my last day as CEO. My title changes tomorrow, but the love I have for the Apple community never will. Thank you for being a constant source of inspiration. My gratitude is endless, and I’m excited for the next chapter!
Excited to share what @sheldenshi , @potatoparser, and I have been building: @GiniAgent, a model agnostic proactive AI coworker that lives inside of Slack AI coworker that lives in Slack.
Backed by @ycombinator
i just found out my bestfriend broke up with her sf boyfriend over the weekend
i asked what happened
she goes "i found out he had an ai agent managing the relationship"
turns out the thoughtful texts, the check-ins, the good morning messages, the conflict resolution, dinner date plans...all automated
my friend was emotionally attached to a cron job
Ex-Berkeley PhD who leads SGLang at xAI explained how they serve Grok on 100K GPUs in 23 minutes - better than $2000 inference-at-scale courses.
split prefill and decode -> shard experts across GPUs -> route tokens per expert -> overlap comm and compute -> serve at DeepSeek-API-killing prices.
That loop is why xAI runs Grok on SGLang and third parties beat DeepSeek's own API by 5x on cost.
SGLang + prefill-decode disaggregation + expert parallelism + AMD MI300 - that's the stack.
Watch and save it, then read the article below.
Fast, efficient local AI with open-source models just got easier.
Qwen3.6-27B-NVFP4 is now on @HuggingFace!
It's optimized for NVIDIA Blackwell GPUs & inference ready with @vllm_project.
The checkpoint reduces GPU memory requirements by approximately 2.5x for powerful 27B-parameter inference on your own hardware.
Update: I've joined @AnthropicAI and taken leave from the university. Excited to work with many talented, mission-driven people on the defining technology of our time.
On-device speech→text on Apple Core AI — fully offline on iPhone 17 Pro.
Whisper large-v3-turbo (100 languages, auto-detect) or Qwen3-ASR-1.7B. Nothing leaves the phone.
Usable now if you want it:
🤗 https://t.co/gAOcYJiMLY
⚙️ https://t.co/etaWWaaN0c
Fable isn't the first.
In 1999 the department of defense blocked exports of the PowerMac G4 for crossing the 1 gigaflop threshold.
Steve Jobs turned it into an ad.
fun fact: tijdens de keynote hakt Apple een stukje 3k, 4k, 5k en 6kHz eruit wanneer ze "Siri" zeggen, zodat niet iedereens HomePods terug beginnen te praten 🗣️🚫
China: a 10-year-old casually gets a Mac Studio for “raising lobsters,” aka letting multiple AI agents work together like a tiny digital crew.
“The world of the future belongs to those who understand Tokens.”
Meet the AI-native children.
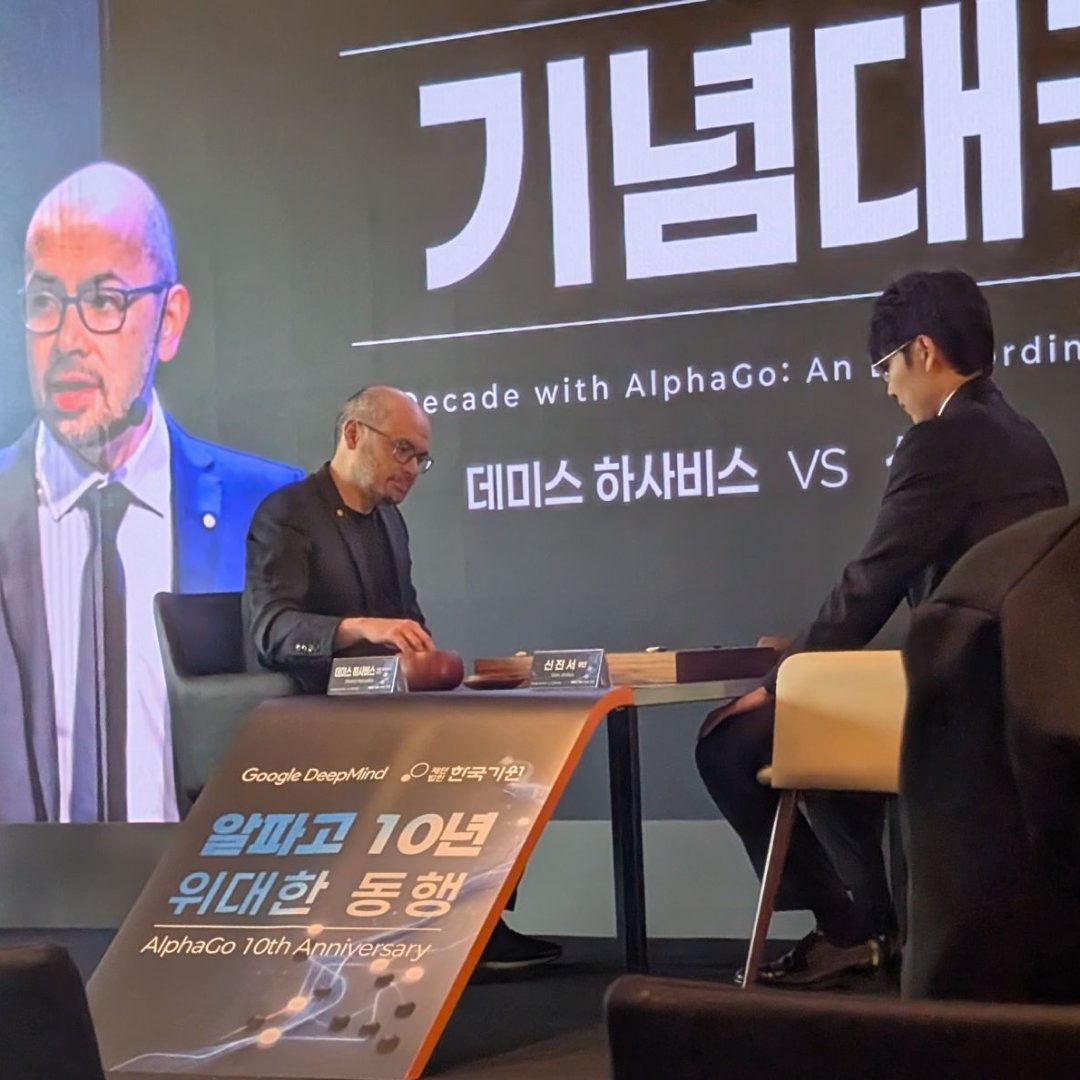
Hard to believe it’s been 10 years since AlphaGo! It was wonderful to catch up with Lee Sae Dol last week in Korea and join Shin Jin-seo for a special Go match. Great to reminisce about AlphaGo & super interesting to hear how it changed the way players approach the game of Go!