I build AI agents that hold up in production: evidence-grounded workflows, agent memory, K8s-native runtimes. 15 yrs running large-scale systems. Here I share what breaks in real AI deployments: agents, infra, GPU economics. Follow if you ship AI to production.
@RealNickMugalli The tier that matters for agents is the middle one.
Long sessions pause on tool calls and human approvals, and that idle KV is too warm to drop but too expensive to park in HBM.
Whoever makes reloading from CXL/SSD cheaper than recomputing the prefill wins on cost per task.😂
Reportedly Meta's 816B open-weight model runs on two high-memory Mac Studios. "Inference cost is going to zero"?
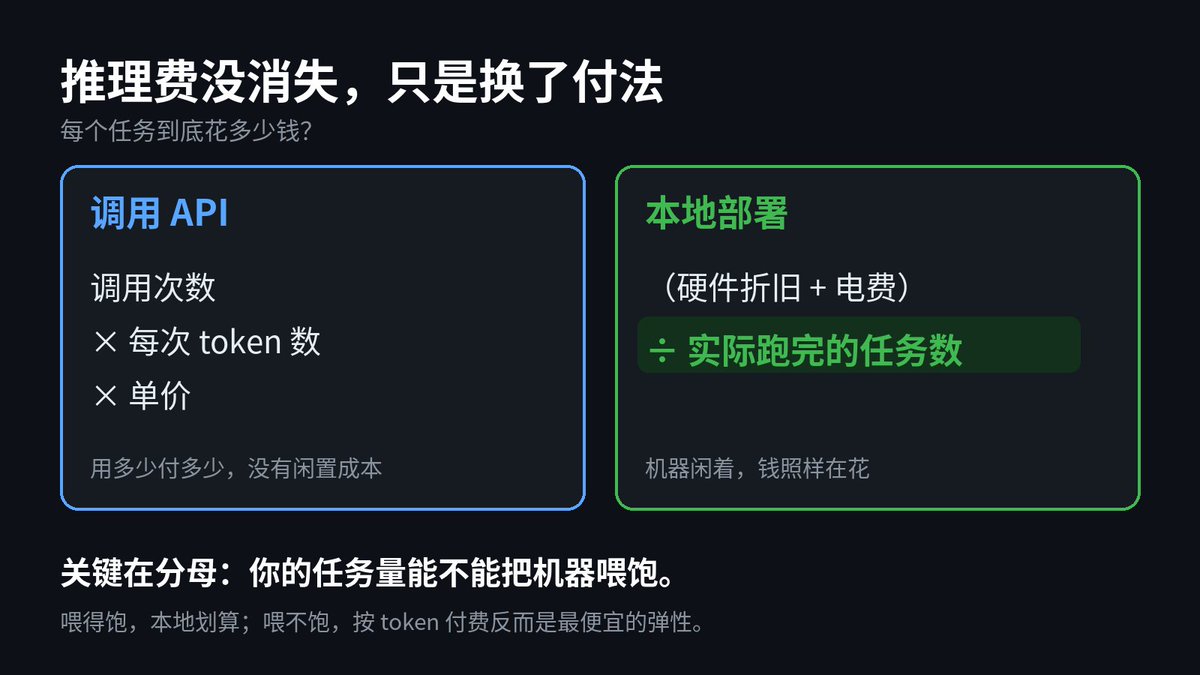
Not quite. It just changes how you pay:
API: cost/task = calls × tokens × price
Local: cost/task = (depreciation + power) ÷ tasks actually completed
The denominator decides it. Light workloads make local pricier than API, and long-context agents hit KV-cache memory limits before they saturate compute. If you can't keep the box busy, pay-per-token is the cheapest elasticity you'll get.
@pauliusztin_@zenml_io Caching tool outputs is what makes replay safe. I'd key the cache on the exact tool-call arguments, so when a fix changes what the agent asks for, you get a visible cache miss instead of silently replaying an old answer.
@OfficialINDIAai@IndianCERT The "agents under evaluation" part is the sharp one. Eval runs often get broader access than production because nobody treats them as real users. Short-lived, task-scoped credentials per eval run, plus a log of every tool call, closes most of that gap.
@Sanemavcil Fewer tokens at the same solve rate is the right metric. The thing I'd check is index freshness: if the agent edits files mid-task and the index lags, it pulls stale code with full confidence.
@Mr_Salio Per-token price is only half the story. For agent work I'd compare cost per completed task: a model that's 30x cheaper per token still wins big, but retries and longer outputs eat into that gap faster than the headline suggests.
Useful FAQ.
One nuance from the MOFCOM Q&A: on-prem deployment of a restricted model overseas counts as an export, while API/SaaS serving doesn't.
So for builders abroad, the practical question is less "can I still call Qwen" and more "will a vendor be allowed to ship private on-prem weights of the next release."
The peak/off-peak split is the underrated part. Batch agent work (evals, backfills, overnight refactors) can be scheduled into the cheap window, so effective cost depends on when you run as much as on which model. For long agent loops, the cached-input price will matter even more than the headline numbers.