Open-source business management software engineered to operate at scale. Built on a robust microservice architecture. Designed to evolve with your enterprise.
Introducing Frostbite: a new class of CPU built around interaction nets.
Given only interaction net theory, our agents co-designed the ISA and chip architecture from scratch, running large swarms to design, verify, and optimize the CPU down to the final GDS.
On our first set of target workloads, Frostbite is 4.6x more performant per watt than modern traditional CPUs at similar area.
Phew.. in before GTA 6. It was a close one.
In all seriousness. Thank you everyone who was involved or inspired this project. When I started I never pictured it getting here. It's been a privilege to be part of turning a concept into a paradigm that has shaped how we build UIs.
Orleans is a classic paper worth revisiting, from before most modern durable execution frameworks.
I think virtual actors/durable objects are in some sense the object-oriented cousins of durable workflows. Both make applications reliable, but they focus on different abstractions: durable state and identity vs. durable execution progress.
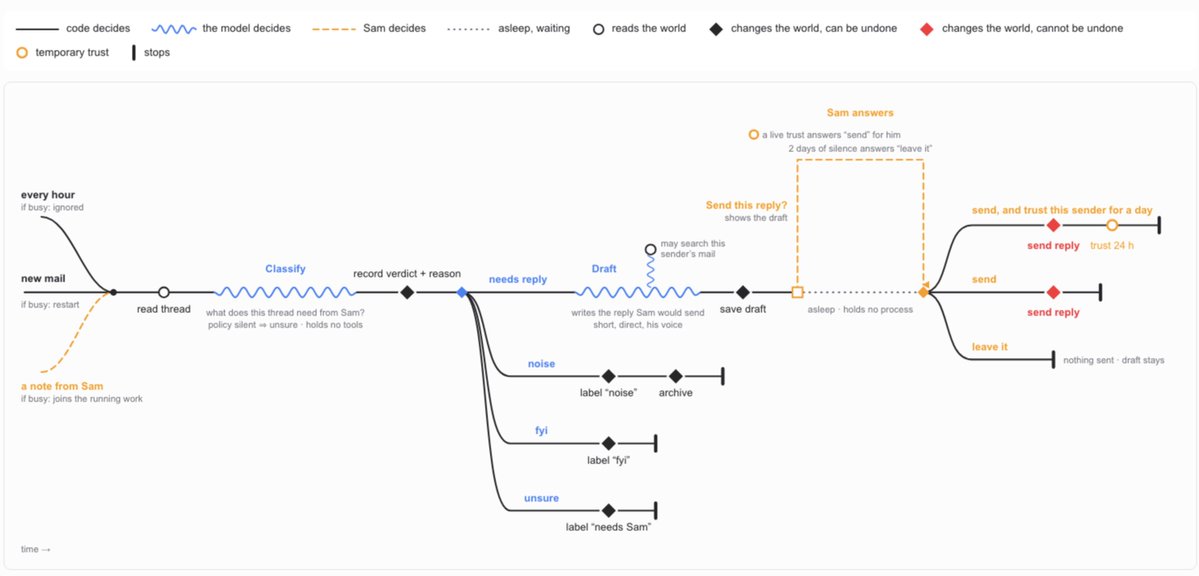
It seems promising to apply Feynman Diagram concept to describing agent workflows/loops.
This is projecting a simple Pi Durable agent into a diagram to visually review its workflow logic.
Curious to understand how this scales to bigger agentic systems and real life usage.
Anyone know who is exploring this that I could chat with/read?
For the past month, I've been creating a language for building UI with AI that provides Solid's runtime guarantees at compiler time. Solid's unbeaten performance written in a way that is hard for agents to get wrong.
https://t.co/8fCDeW6Luo
I may be biased but Kubernetes team at Google is one of the most solid teams in the industry. We are driving a lot of work for the future of agentic systems and agentic compute. This is a rare opportunity.
If you're interested in Deterministic Simulation Testing, but a little confused by it - could I run an article draft by you?
I firmly believe is widely applicable and not just for database writers , so I want to write something broadly understandable.
DM me or comment.
Check out my talk at Cloudflare Connect on celld.
celld let’s you self-host workers, durable objects, queues, and workflows using only an object store bucket as a backend.
We’re in the process of merging the ideas in celld into the open source workerd. More to come on the new workerd soon!
https://t.co/z9ovyhAEiV
Fun fact of the day:
Postgres started as a successor to Ingres Project, short for Post-Ingres.
And Ingres was the short for Interactive Graphics & Reterival System.
The first version of Postgres didn't even use SQL, it used Post(Quel), short for Query Language.
The project was forked by 2 grad students in 1994 & renamed to Postgres95, but was renamed to PostgreSQL a year later by community maintainers.
when you find yourself making visualizations of your psycho-bespoke merge process to deal with CI bottlenecks caused by the sheer magnitude of robo-commits, you're probably about to design your own programming language.
Just released documentation for my skills.
Each of the 17 skills now has a before and after of the same UI, example prompts, when to reach for it, and which skills pair well with it.
An improvement over a plain README on GitHub, with more coming soon.
https://t.co/wSHp04XjT0
Did some reading on formal verification this weekend:
https://t.co/rP80c2LBG7
https://t.co/Zftj8u11OE
https://t.co/P73BX5TM29
Absolutely worth reading. Especially vitalik's post if you want spark notes version. FV is hot these days, and it's not just empty hype.
New skill: /gestures
Helps you build beautiful, intuitive gestures for your app.
Adds rubber banding, velocity support for dragging, drags that carry momentum, everything I learned from building Sonner and Vaul, and more.
I’ve been using it a lot recently, you’ll love it.
We invented a recursive megakernel generator called Hyperkernel, the most complete solution to megakernels and GPU efficiency.
Hyperkernel-generated megakernels achieve state of the art performance on 11 different domains: inference (DeepSeek, Kimi and GLM), pretraining (Qwen), hardware fault recovery, robotics (π₀-FAST, ACT) diffusion and real time world models (Matrix-Game), full self driving (OpenPilot), voice models (Moshi), genomics (Evo 2) and protein folding (ESMFold).
All of this in a single kernel launch.
For context, Hyperkernel generated fully optimized megakernels for robotics, genomics and voice in under 50 minutes, and doubled the efficiency for >5 models generally using only about 60-100 lines of code per megakernel. This speaks to the unparalleled standard for code quality in the automated generations.
Our first release today open sources the megakernels themselves. Over the next couple weeks, we will release the entire Hyperkernel stack, along with the complete serving stack for Kimi and GLM (20-30% inference efficiency gains across all concurrencies).
Out of the box GPU machinery performs terribly for unorthodox research. We built Hyperkernel only 20 days ago for internal use; but given its multi-modality, we have decided to open source it.
Creative research should not be bottlenecked by the lack of dedicated infra teams. Hyperkernels offer a one stop shop infra stack for all research. We would love for the open source community to add to it :)
GitHub repo: https://t.co/sfPt4S4BJN
NOTE: We primarily use NVIDIA B300s, but our kernel generation extends to other hardware (B200s, AMD, TPUs).
1/9
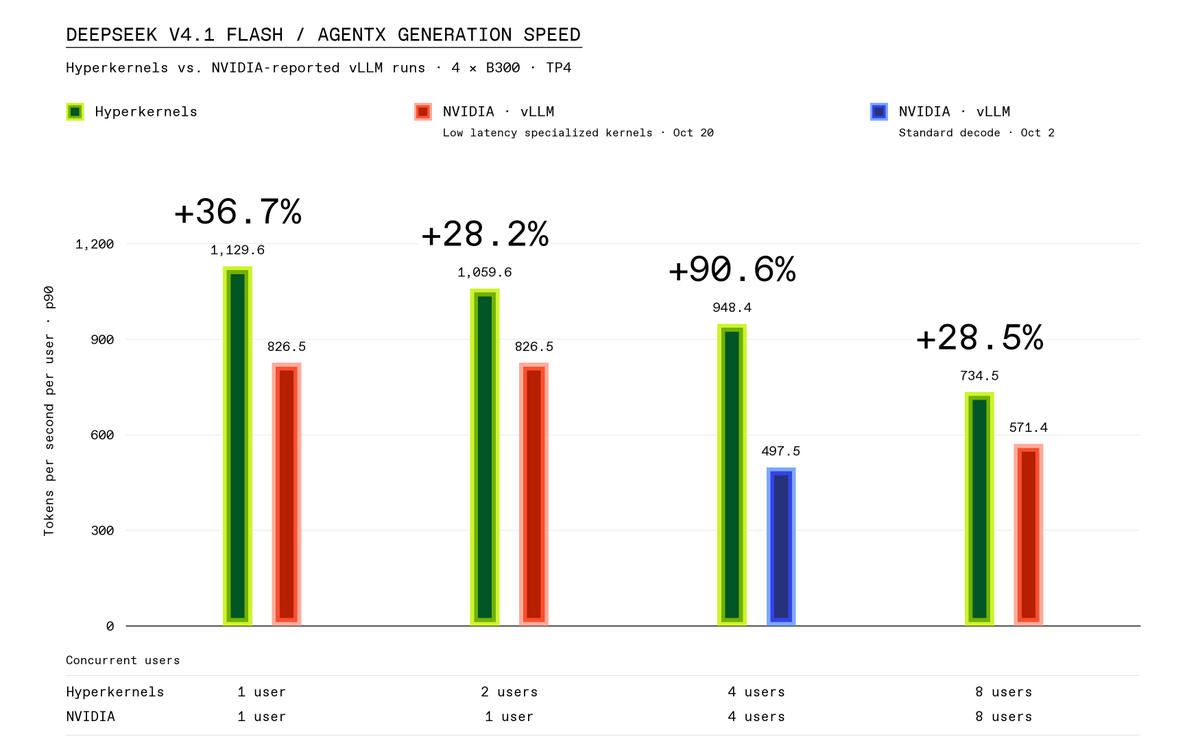
We absolutely crush NVIDIA and achieve the best low latency inference for DeepSeek v4.1 Flash.
Compared with NVIDIA’s published vLLM results, Hyperkernel delivers:
• 36.7% higher per-user generation speed at concurrency 1.
• 28.2% higher per-user speed while serving two users, versus NVIDIA serving one.
• 15% higher per user speed while serving four users, versus NVIDIA serving one.
• 90.6% higher per-user generation speed at concurrency 4, compared with the highest published C4 AgentX interactivity for TP4 B300s.
• 28.5% higher per-user generation speed at concurrency 8, compared with NVIDIA's published result.
• 36% faster median per-request decode speed.
Memory is what allows Claude to learn from experience. In a new Engineering Blog post, we share how “dreaming” helps Claude organize what it’s learned, correct its mistakes, and find what it needs more easily the next time. https://t.co/uUEN4bNkr9