Tinkering with robots & AI to shape a smarter world. Curious about autonomy, perception, and the future of human-machine synergy. Always learning, coding, build
Debugging an agent run is harder than reading a 500 error. This repo gives you the map.
Awesome Agent Observability is a curated GitHub list of tools, standards, and platforms for tracing, evaluating, and governing LLM and AI-agent applications.
It helps you turn a scattered observability search into a practical stack shortlist by grouping standards, tracing backends, evaluation tools, guardrails, gateways, and MCP tooling in one scan-friendly index.
Key features:
• Standards and instrumentation – links to OpenTelemetry GenAI conventions and instrumentation projects for LLM applications
• Tracing platforms – surfaces options such as Langfuse, Phoenix, Opik, and MLflow Tracing
• Evaluation and testing – collects frameworks for evals, test-set generation, red-teaming, and tool-use tasks
• Guardrails and security – points to validators, vulnerability scanners, PII tooling, and MCP security scanners
• MCP and agent frameworks – covers MCP resources plus frameworks with built-in tracing
It’s open-source (CC0-1.0 license).
Link in the reply 👇
As owning your intelligence stack matters more than ever, reliable access to AI infrastructure and agent compute is key to realising that vision.
I’d like to see more of that capacity easily available to builders running experiments and post-training. That’s what interests me about @shadeformai’s Flex VMs announcement.
Congrats @edsgoode and team!
Text-to-Speech that speaks 5 languages:
❯ English
❯ French
❯ German
❯ Spanish
❯ Portuguese
102 built-in voices. Single model. On your device.
❯ GitHub ➟ https://t.co/Vu1zEoxmg9
Spanish demo ↓
Even your Smart TV can be vulnerable! Insecure apps, weak home Wi-Fi, and exposed cameras/mics can put your privacy at risk. Plugging in the Deeper Connect, with 7-layer firewall, protects your network and encrypts data, keeping your Smart TV secure and protected.
Home robots need taste too. Personalized agents are a super interesting new trend I am bullish on.
If a robot is going to live in my home, I want one I like having around. @roboticscorp is building robots for that.
The first 999 units are numbered and open for reservation today.
Interesting how AI is changing not just how we build products, but how people discover them.
The idea that AI agents are becoming part of your audience is pretty fascinating.
Lots of good insights here, especially for founders and developers. 👀
@Dipanshu_AI Dude, I totally agree that Andrew Ng's course is a game-changer for anyone who wants to get into Al agentic engineering without wasting time!.
Featured on today's agenda: Powering the Enterprise - executive sessions and workshops with @RedHat, @nvidia and @IBM focused on scaling enterprise AI
#PyTorchCon
The AI Automation Agency Standard — Complete Professional System for High-Value Clients, Production-Grade AI Agents, Proven ROI, Recurring Revenue, and Founder Independence: https://t.co/9Vkm4jBrSf
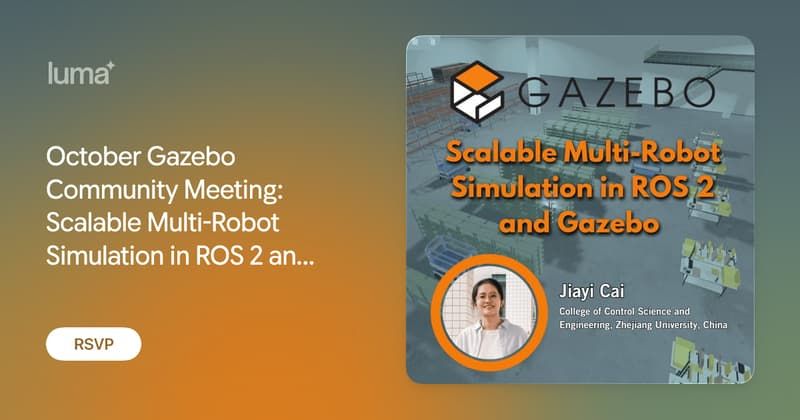
Join us this Wed, Oct 21st, at 7pm PT for our monthly Gazebo Community Meeting.
Our guest speaker will be Jiayi Cai, our Google Summer of Code student who will discuss building scalable multi-robot simulations using #ROS 2 and #Gazebo.
RSVP on Luma:
https://t.co/UxhmIHUyrw
I do tech art for a mid-size team and on weekends I've been building shader tests with generated textures.
Chroma's Feb 1 cutoff means the summer stuff counts, didn't expect that.
Most personal RAG pipelines and AI memory systems rot within weeks because a single agent is allowed to ingest, summarize, and overwrite state in the same pass.
What makes this three-agent implementation of Karpathy's LLM wiki actually work in production is strict separation of concerns—essentially Event Sourcing applied to knowledge management:
1. Immutable Ingestion (The Reader): Treating the raw/ directory as an append-only source of truth guarantees you never lose original context to a bad summarization pass.
2. Materialized State (The Librarian): Compiling synthesis pages into wiki/ keeps retrieval fast without mutating the underlying evidence.
3. Asynchronous Reconciliation (The Checker): Flagging contradictions and 30-day staleness overnight instead of silently overwriting old claims prevents hallucination drift.
When you architect long-term memory for multi-agent systems in Python today, do you still rely on flat vector database chunks, or maintain a structured Markdown knowledge graph with immutable source logs?