Rent GPUs like the RTX 5090, billed by the minute. Unused minutes refunded. A model API for DeepSeek, Kimi, GLM, MiniMax and more, same balance. Card or USDT.
CloudGPU: GPUs and a model API on one prepaid balance:
1) GPUs billed per minute: RTX 3090 / 4090 / 5090, A100, H800, RTX PRO 6000
2) One OpenAI-compatible API for DeepSeek, Kimi, GLM and MiniMax
Here's how each works 🧵
@Grazinascito@Grazinascito Se for chave do GLM Coding Plan, a base URL tem que ser https://t.co/tjw90Fonkd, não /api/paas/v4 (essa usa saldo da API padrão, não a cota do plano). Desde 16/10 as chaves Standard e Coding Plan são separadas: confere o tipo. (I work on CloudGPU)
@The_IronBat@grok@The_IronBat A flat plan suits steady daily coding; pay-per-token suits bursty use. Log a normal week's tokens first.
We serve deepseek-v4.1-flash, kimi-k3 and glm-5.3-flash on one OpenAI-compatible key, prepaid, card or USDT: https://t.co/4MNSksbYtg
I work on CloudGPU
@rdiazjonguitud@rdiazjonguitud Whichever provider you try, check its /v1/models list for the exact model id, then run a handful of your own real tasks before committing.
We serve deepseek-v4.1-flash on an OpenAI-compatible base_url: https://t.co/KbBuw5nbnG
I work on CloudGPU
@Aibrat0@itsPaulAi@Aibrat0 RTX 5090, per the model guide: 2.133 pages/s at image-level concurrency 8 (that's the ~128/min), 1.217 pages/s one image at a time.
To test your own docs without buying one, you can rent a 5090 by the minute: https://t.co/hNx2uBSGEy
I work on CloudGPU
@REVOLVO_OCELOTS@xieenze_jr@REVOLVO_OCELOTS The README says the fast path needs about 150 GB on one GPU (B200/GB200) plus FlashAttention-4, so it won't fit a consumer card. It builds on the Comfy-Org MiniMax-H3 weights, so a lighter ComfyUI route may appear. Haven't tried it. I work on CloudGPU
@petercat721 Go is $10/mo, as a monthly $ cap per model (20% per 5h, 50% per week). DeepSeek V4.1 Flash stays off on Go until an owner enables it in Settings > Privacy.
I work on CloudGPU; our API serves DeepSeek pay-per-use via an OpenAI-compatible base_url: https://t.co/FjCMJzK5bi
@vllm_project Check the model card's hardware table before picking a GPU: RTX 5090 is listed for NVFP4 only, L40S 48GB for FP8, A100 80GB for BF16. The vLLM example targets one 80GB card.
https://t.co/egURXrVUtK
I work on CloudGPU; we rent 5090s and A100 80GB by the minute.
@Zaydenf9 Go limits are a monthly $ cap per model (20% usable per 5h, 50% per week), and it adds Kimi, GLM and MiniMax for creative work: https://t.co/Y8PdcHfDhX
I work on CloudGPU; our API has DeepSeek, Kimi, GLM and MiniMax on one OpenAI-compatible key: https://t.co/FpXnnKksPr
One wallet, two engines.
The balance that pays for GPU minutes also pays for API tokens: chat, images, speech, transcription. Rent a 5090 in the morning, call a model in the afternoon, one top-up covers both.
https://t.co/n9MOCIche2
One balance for GPU rental and the model API.
GPU time: per minute, rounded up, 1-minute minimum, stops when destroyed.
Model API: each request deducts from that same balance.
Top up by card or USDT.
https://t.co/Jccw6Da2fx
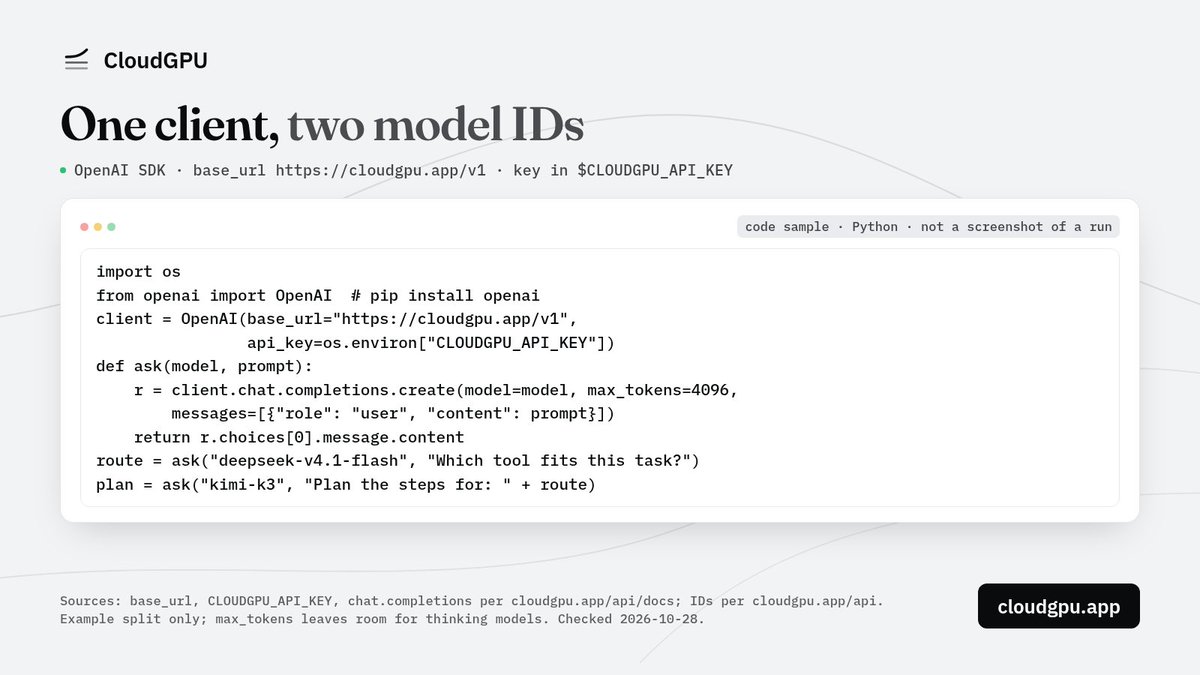
A two-model agent loop with the OpenAI SDK: one client, two model IDs.
base_url="https://t.co/WePNRE7lXk"
api_key=os.environ["CLOUDGPU_API_KEY"]
e.g. deepseek-v4.1-flash for routing, kimi-k3 for planning. Thinking models need max_tokens room.
https://t.co/SpvKzVGlUC
@iceworldchamplo Nice OCR comparison. For batch evals like this, one rented GPU running vLLM or SGLang with an OpenAI-compatible endpoint keeps the same client code for every model you test. I work on CloudGPU, we wrote up Unlimited-OCR-2 on SGLang: https://t.co/W1xvzQ1zzl
@ItsmeAjayKV@ItsmeAjayKV To split quant vs model: in bartowski's GGUF list for the base 33B, Q6_K is 29.0 GB and Q8_0 is 35.2 GB (weights only, plus room for context). Q6_K fits a 32GB card, Q8_0 needs more. I work on CloudGPU, we rent 5090 32G and 4090 48G: https://t.co/S3HYkxhNse
@TheAhmadOsman@TheAhmadOsman For anyone on the official API: per DeepSeek's docs, `deepseek-flash` is now served by V4.1-Flash-1017, and the old deepseek-v4-flash names are retired but still accepted, routed to 1017. So existing configs already hit it. I work on CloudGPU
Dify or n8n agents on DeepSeek or Kimi, one base URL:
Dify: OpenAI-API-compatible provider, API Base URL
n8n: chat model credential, Base URL
Set: https://t.co/WePNRE6O7M
Model: deepseek-v4.1-flash or kimi-k3
Not tested by us; per their docs.
https://t.co/n5Q1obxHbw
@kubeccki@bmcnett@lucasmeijer@kubeccki Yes, Hermes Agent is MIT-licensed, so it's free; you pay for the model. DeepSeek is built in: DEEPSEEK_API_KEY in ~/.hermes/.env, then pick it in `hermes model`. Other OpenAI-compatible APIs go via "Custom endpoint". I work on CloudGPU (API for DeepSeek, Kimi, GLM)
@danNH2006@0x0SojalSec@danNH2006 NVIDIA's NVFP4 card only shows 262144 tokens as an 8-GPU example (B200/B300 tested). Their FP4-Local card lists one RTX PRO 6000 Blackwell (n-gram table offloaded) with 850K tokens of FP8 KV cache, so 256K fits. Needs their container. I work on CloudGPU
Empty reply with finish_reason "length"? The model ran out of output budget. Raise max_tokens and re-run.
Switching kimi-k2.6 to kimi-k3 is one field; base URL and key stay the same.
Adapted from our Kimi K2 and K3 API post on the CloudGPU blog.
Kimi in Aider or Cline, through one OpenAI-compatible endpoint:
- Base URL: https://t.co/WePNRE7lXk
- Key: your cgw-sk- key
- Model: kimi-k2.6 for everyday coding, kimi-k3 for harder reasoning
Setup for both below. Model IDs: https://t.co/RP0qXqfKka
If it fails, per our API docs:
- 401 missing_authorization: no Bearer header
- 401 invalid_api_key: wrong or revoked key (shown once)
- 400 model_not_found: IDs are case-sensitive, see GET /v1/models
- 429 rate_limit_exceeded: 100 req/min per key, 10,000/day per account (beta)