Most machine learning models learn correlations. Causal inference tries to go further and learn what actually causes what.
A normal model can tell you that ice cream sales and drowning incidents both rise in summer. It cannot tell you that ice cream doesn’t cause drowning. Causal methods try to answer questions like “what would happen if we changed this?” instead of just “what usually happens together?”
Representation learning is about turning raw data into useful features. When you combine the two, the goal is to learn representations that capture the underlying causal structure, not just surface-level patterns.
Why this matters:
- Models that only learn correlations often fail when the world changes.
- Causal representations can be more robust and more interpretable.
- They help with questions like “if we intervene on X, what happens to Y?”
It’s still an active research area, but the basic idea is simple: stop only asking what predicts what, and start asking what causes what.
Hot take: All these companies laying off employees in huge numbers will crawl back to them in a few months and hire them at twice the current salaries.
Self-supervised learning is a way for models to learn useful patterns from data without human labels.
Instead of giving the model correct answers, you create a task from the data itself. The model has to solve that task, and in the process it learns representations that are useful for real problems later.
A few common approaches:
- Predict the missing part. Hide some words in a sentence or some patches in an image and train the model to fill them in.
- Contrastive learning. Show the model two versions of the same thing (e.g. two crops of the same image) and teach it that they should be similar, while different things should be dissimilar.
- Predict the next token or next frame. This is how most large language models and some video models are pretrained.
Why it matters: labeling data is expensive and slow. Self-supervised learning lets you use huge amounts of raw text, images, or audio. The representations it learns often transfer well to downstream tasks with only a little labeled data.
It’s one of the main reasons modern models can be trained at such large scale.
A Bloom filter is a space-efficient way to check whether an item is probably in a set.
It can tell you two things:
- definitely not in the set
- maybe in the set
It never says “definitely yes.” There’s a small chance of false positives, but no false negatives. In exchange, it uses far less memory than storing the actual items.
How it works:
You run the item through a few hash functions and flip some bits in a bit array. To check later, you look at those same bits. If any are unset, the item was never added. If all are set, it might have been added (or other items set those bits).
Where they’re used:
- databases (Cassandra, PostgreSQL, etc.) to skip expensive disk lookups
- CDNs and caches to quickly check if something is probably stored
- browsers (Chrome’s Safe Browsing used them) to check bad URLs
- distributed systems to avoid unnecessary network calls
- spell checkers and network routers
It’s a classic tradeoff: accept a tiny bit of uncertainty to save a lot of memory and speed.
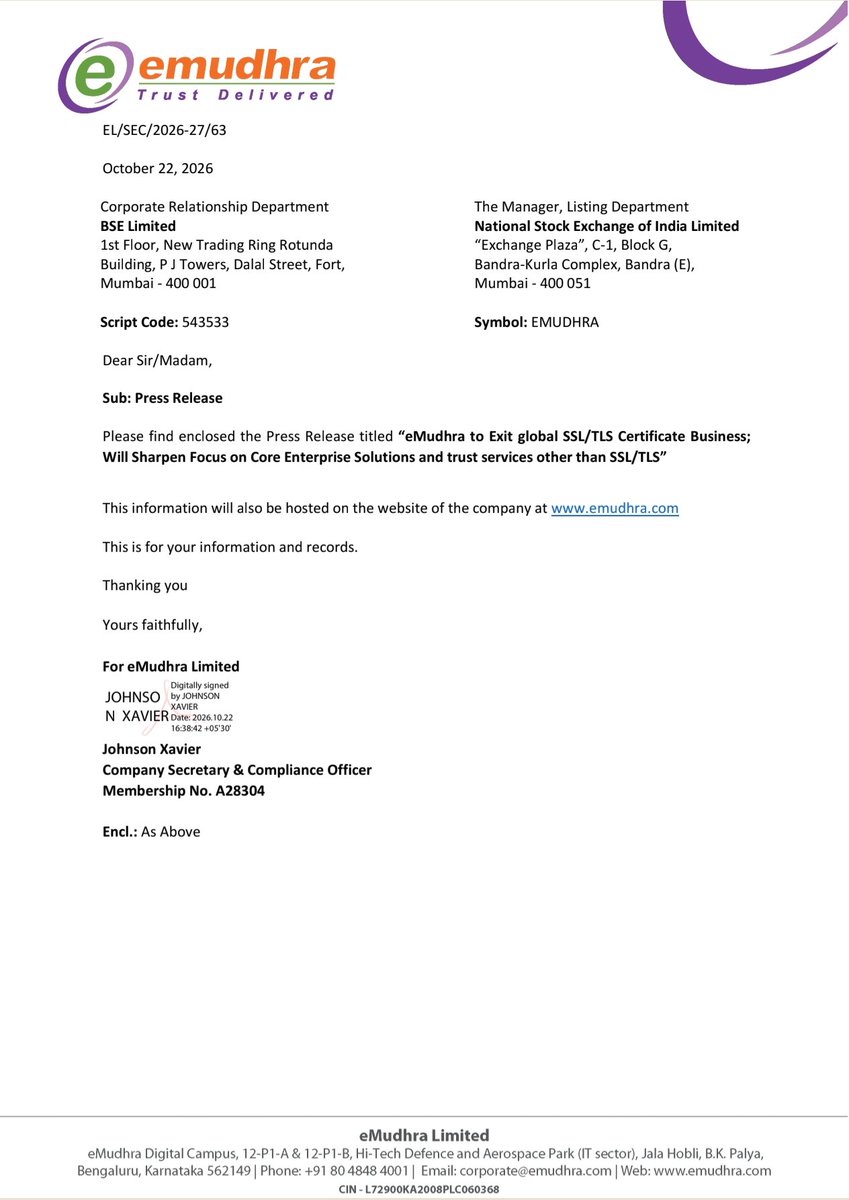
Python users: eMudhra CA weak-key incident can MITM your PyPI package downloads. Update pip/certifi now!
A recent certificate-authority failure at eMudhra (emSign) left eight intermediate CA certificates with catastrophically weak private keys. These are P-384 elliptic-curve keys whose private scalars are all under 256 (one is literally `d=4`). Anyone can recover them in milliseconds and forge TLS certificates for any domain.
Why this matters for Python packages on PyPI:
Tools that download packages from PyPI (and talk to https://t.co/XJ2RfS7Eeu) rely on HTTPS. Many of them ship their own CA bundles that still trusted the compromised eMudhra material:
- The popular certifi package bundled the affected root/intermediates.
- pip always loads its vendored copy of certifi in addition to the system trust store. There is no supported way to turn this off in older pip. Updating only your OS certificates is not enough.
- The same pattern affects uv, sigstore, and other packaging/security tools.
Result: an attacker on the network path can intercept package installs and serve malicious wheels while the connection still looks valid. The risk is especially high in virtual environments, Docker/CI images, and any automated pipeline that still uses pre-26.2.2 pip.
How to mitigate:
Upgrade at least these packages (recommended floors as of the official Python guidance):
- certifi ≥ 2026.10.19
- pip ≥ 26.2.2
- uv ≥ 0.13.4
- (also sigstore ≥ 4.5.1 if you use it)
Because an old pip can itself be MITM’d during the upgrade, prefer the hash-pinned wheel install:
bash:
python -m pip install "pip @ https://t.co/LXtov6xihI"
Then use the new pip to upgrade the rest:
bash:
python -m pip install --upgrade "certifi>=2026.10.19" "uv>=0.13.4"
Do this inside every virtual environment. Rebuild container images with caching disabled so they pick up updated system CA stores. Fresh Python 3.15.1 / 3.14.9 / 3.13.17 installers already ship the fixed pip and certifi.
Full official guidance:
https://t.co/VsKYmwL6Ri
This is not a malicious package on PyPI itself. It’s a trust-store problem that can undermine the TLS protection around package downloads. Update the tools that fetch them and you’re protected.
@AsreSalim17@IndianTechGuide The average is higher than that. The median income is around 15K. And that is so sad. Majority in this country is just surviving, not living.
@IndianTechGuide Qualcomm is one place where employees have very poor work life "balance". Sad that after all the hard work they will be booted out in the name of "bad performance". Very poor leadership.
SCOOP: Major U.S. banks are detecting unauthorized third-party AI agents inside customer accounts, including some attempting to take actions that appear to be independent of user instructions, sources told Axios.
The findings have alarmed banking executives, who are racing to restrict access to their systems as AI moves at a velocity faster than financial institutions can respond, multiple industry and bank executives told Axios.
Several banks are now preparing for worst-case and even “day after” scenarios, including how to rapidly secure or restore customer accounts if things go wrong, the people said.
Several bank executives told Axios they're struggling to distinguish between human users and AI agents. One executive said banks also struggle to determine whether agents are authorized by customers or potentially operating without their permission, more akin to rogue agent behavior.
Read my latest for Axios here: https://t.co/Q3bda5In8q