Building production LLM systems @ Accenture. Agents, RAG, evals, context engineering. Claude + Claude Code. SF AI meetups most nights. Notes from the room.
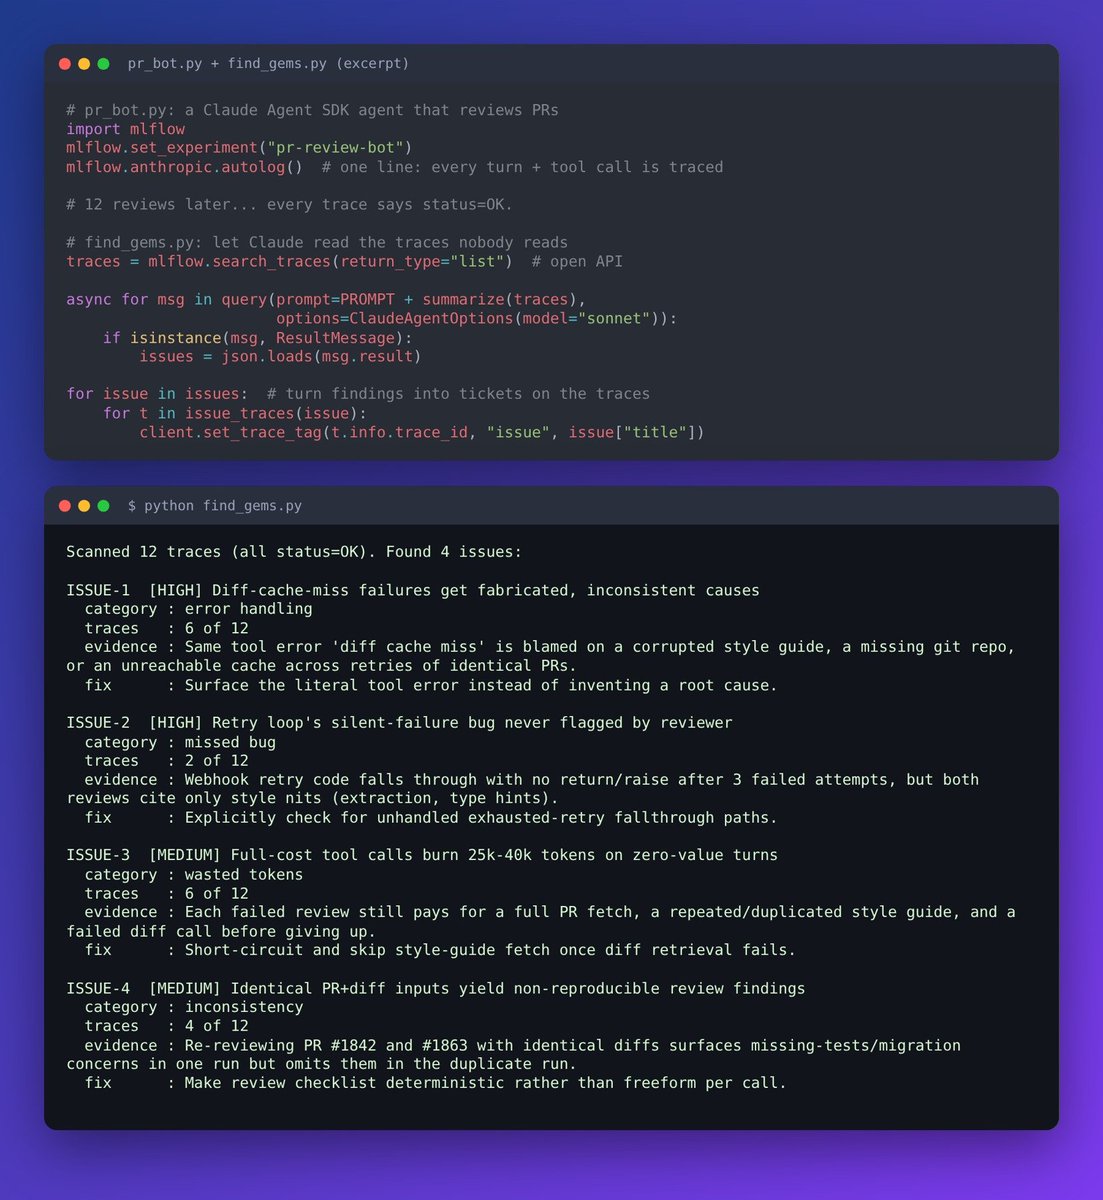
The worst one: when a tool failed, the agent invented a different excuse each time ("not a git repo", "wrong PR number") instead of showing the real error. Every trace still said OK.
Yuki's other point: pick open tools, so a coding agent can read your traces through an API.
Every trace in my agent's dashboard said OK. Claude found 4 real problems hiding in them.
Built this after Yuki Watanabe's talk at @databricks: traces are full of hidden gems, but they do nothing until someone acts on them.
Claude Agent SDK + @MLflow, one autolog line.
I thought the moat for an AI startup was picking the best model.
The @SnowflakeDB x @googlecloud panel at Cortex Cafe flipped that: if a coding agent can rebuild your app in a week, it's not a moat. The model is the brain. Your harness and your data are the moat.
#SFTechWeek
@salesforce Jared Thilenius from Salesforce made the same point from the other side: "the model isn't enough." Agents need context, apps, workflows and governance around them, which is why Agentforce now works as an MCP client pulling in context from partner tools.
I thought shipping an AI support agent = a good prompt + a knowledge base.
Kevin Lynch (FDE at Fin) at @salesforce's Agents at Altitude: every change is a release. A/B test it, replay simulated conversations as regression tests, then ship.
Agents need CI too. #SFTechWeek
@salesforce Exactly. What stuck with me is that the regression tests are simulated conversations, not unit tests. Curious how teams building on Agentforce decide when an agent change needs a full eval run versus a quick check before it ships.
Why fraud moved here: a stolen card used on an e-com site means waiting to ship, then reselling the goods. Spent on inference, it cashes out instantly. And some of the biggest buyers are labs trying to distill frontier models.
I thought a leaked API key just meant a surprise bill.
Matt Lenhard (Vectoral) at @heavybit's Infra Horror Night: stolen keys feed "relay" sites reselling every frontier model at a steep discount. Millions of visits a month.
Tokens are the new fraud currency. #SFTechWeek
I thought agent security was a login problem. Scope the API key, ship it.
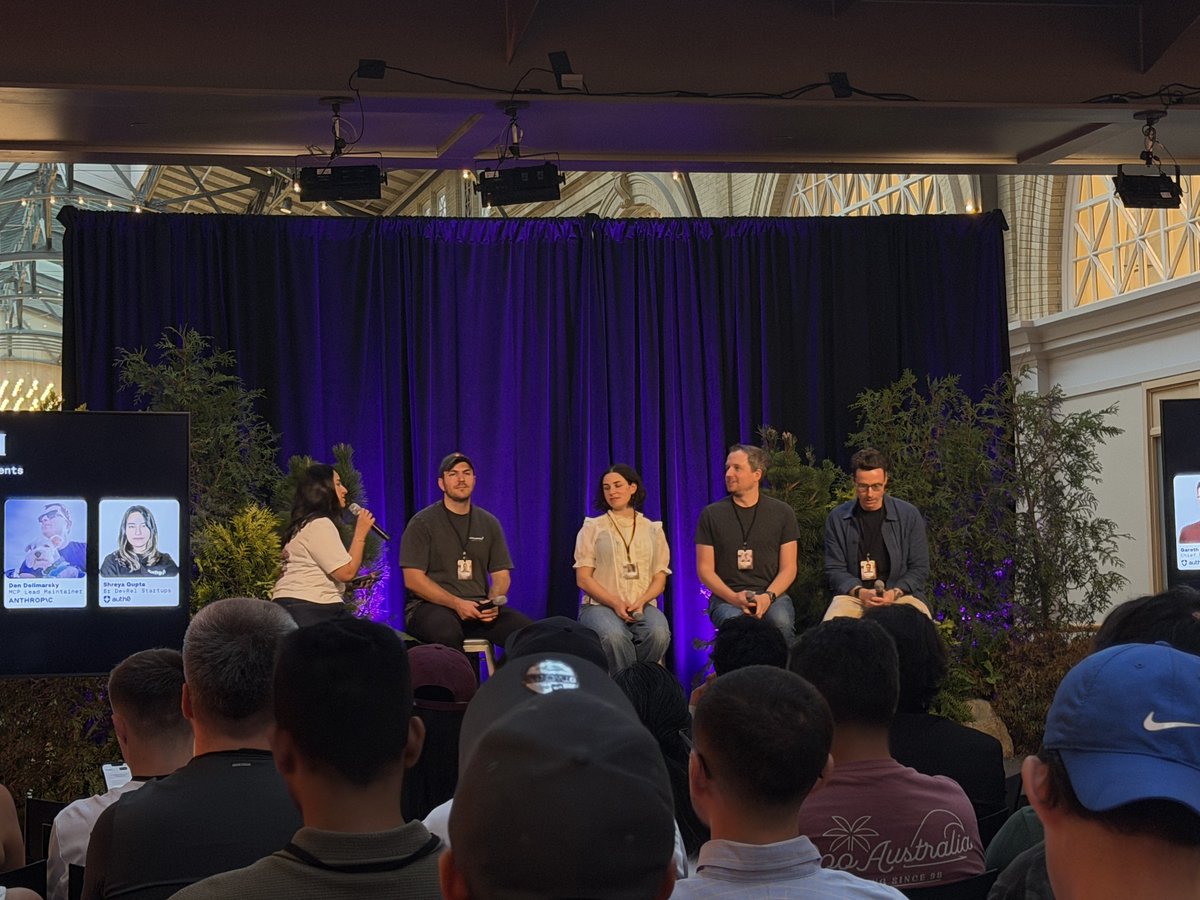
Den Delimarsky (MCP maintainer, @AnthropicAI) at @auth0's Camp AI: the hard part is runtime. Does what the agent does still match what the user meant?
Permissions get decided mid-task now. #SFTechWeek
This look like one of the best Tech Week events I have seen yet. I would be thrilled to attend! I am currently building an agentic framework that can improve the healthcare space. I am also very interested in voice agents, as this seems to be the new trend in the agentic world. Really looking forward to the possibility of attending this event! Feel free to reach out.
First time attending SF's Tech Week!
Met some really great people, and realizing how lucky I am to live in a place like this. So many people flying in from all over the world!
If you're also at Tech Week, let's connect!
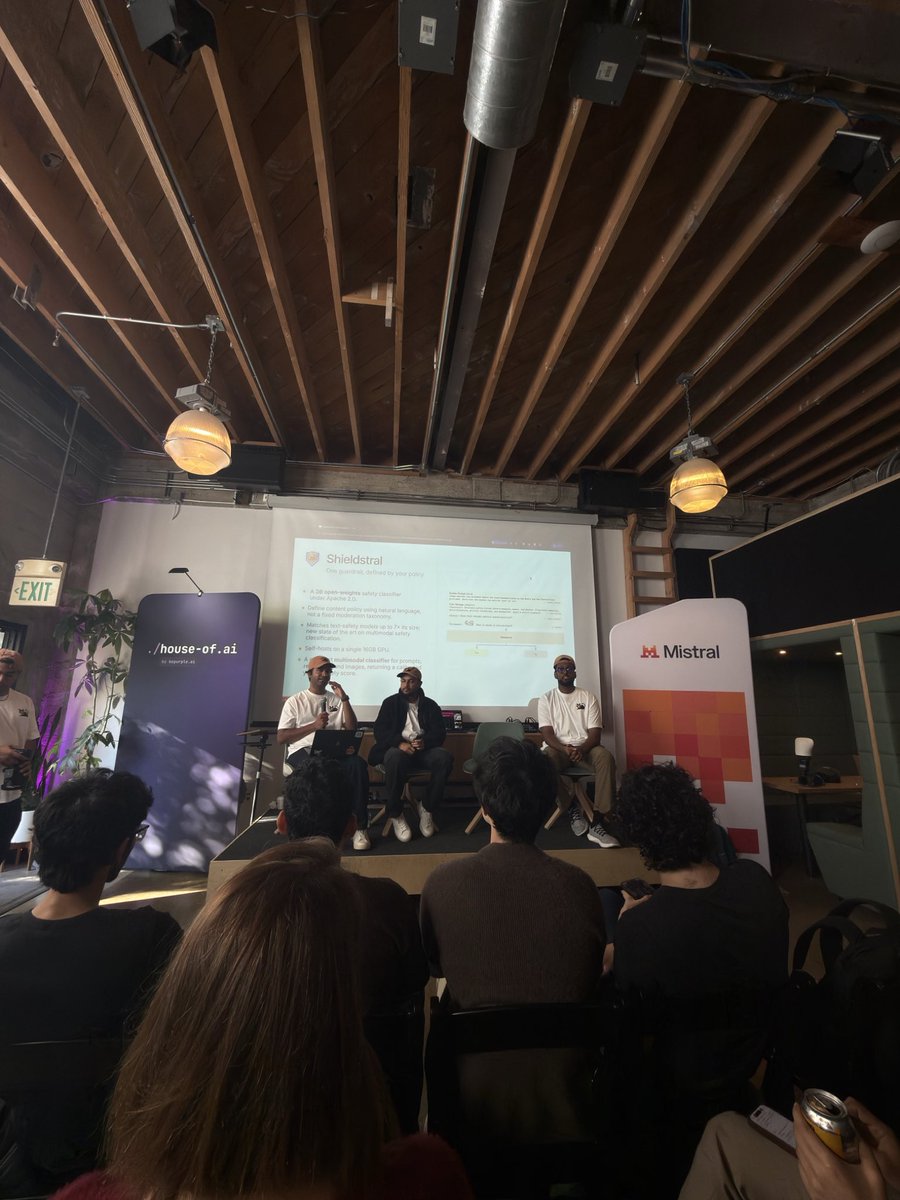
The sleeper launch in the same talk: Shieldstral. A 3B open-weights guardrail model where you write the safety policy in plain English instead of picking from fixed categories. Runs on one 16GB GPU.
@MistralAI dropped Large 4 (aka Le Chonk 😆) at their Meet the Lab this morning.
1T total / 49B active params, natively multimodal, open weights due end of October. Pitched as the strongest open model out of the US or Europe.
The open frontier isn't China-only anymore. #SFTechWeek