If you’re new to Temu and looking for affordable stuff for your home, gifts, or just everyday shopping, have a look at this.
👍 I found some nice Temu prices here:
https://t.co/CUim5JRJWU
You can also search alv135634 in the Temu App.
#TemuShopping
Know someone who’s always looking for a good bargain? 👀
Send them this one.
New app users can check out these Temu special prices here → https://t.co/CUim5JRJWU
Search alv135634 in the app to take a look.
#TemuDeals#Deals
🔥 TEMU DEAL ALERT!
New to the app? Don’t scroll past this one 👀
🎁 ₡ 50,000 coupon bundle → https://t.co/rxpWwJegx9
Looking for 30% OFF? Search alv248453 in the Temu App! 💥
#Deals#TemuDiscountCodes
Our engineers recently visited one of our speech restoration study participants for a 72-hour hackathon.
The goal: rapidly prototype as many features as possible to enhance the experience of using Neuralink to communicate with thought.
Here are some of the things we built 🧵
Kimi's CEO Zhilin Yang:
"everyone's trying to build one smarter agent
many agent hits a wall fast, so instead of making it smarter we just made more - one boss, a thousand workers."
in a 39-minute talk he explains why one agent won't get you to real work.
agent swarms + long context + RL on every sub-agent - that's the fix.
bookmark this ↓
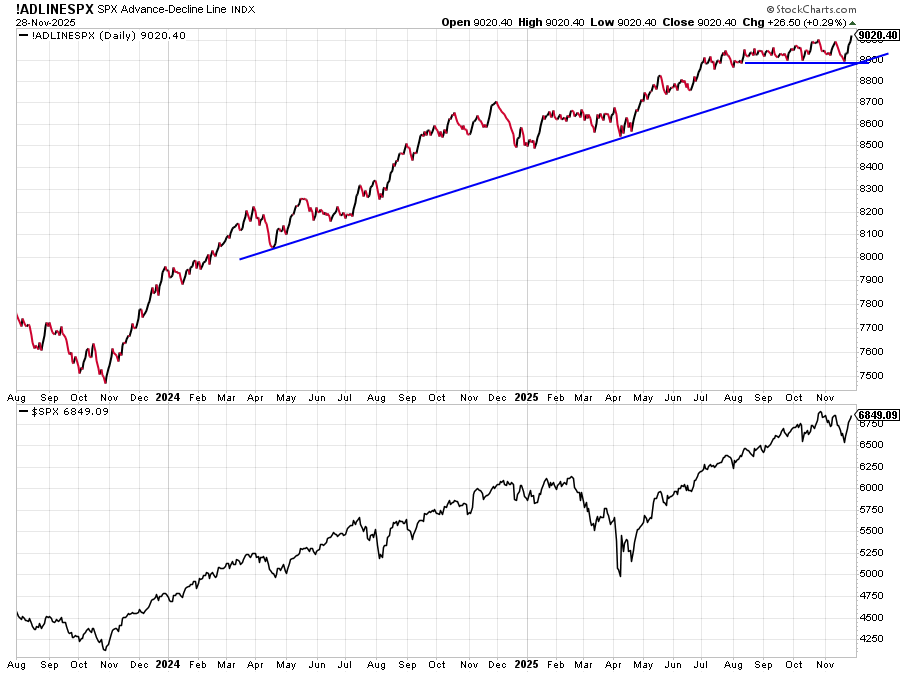
New all-time high in the S&P 500 advance/decline line.
Few things are more bullish than breadth making new highs.
As we said all November, new highs are still coming in 2025 and this does little to change that view.
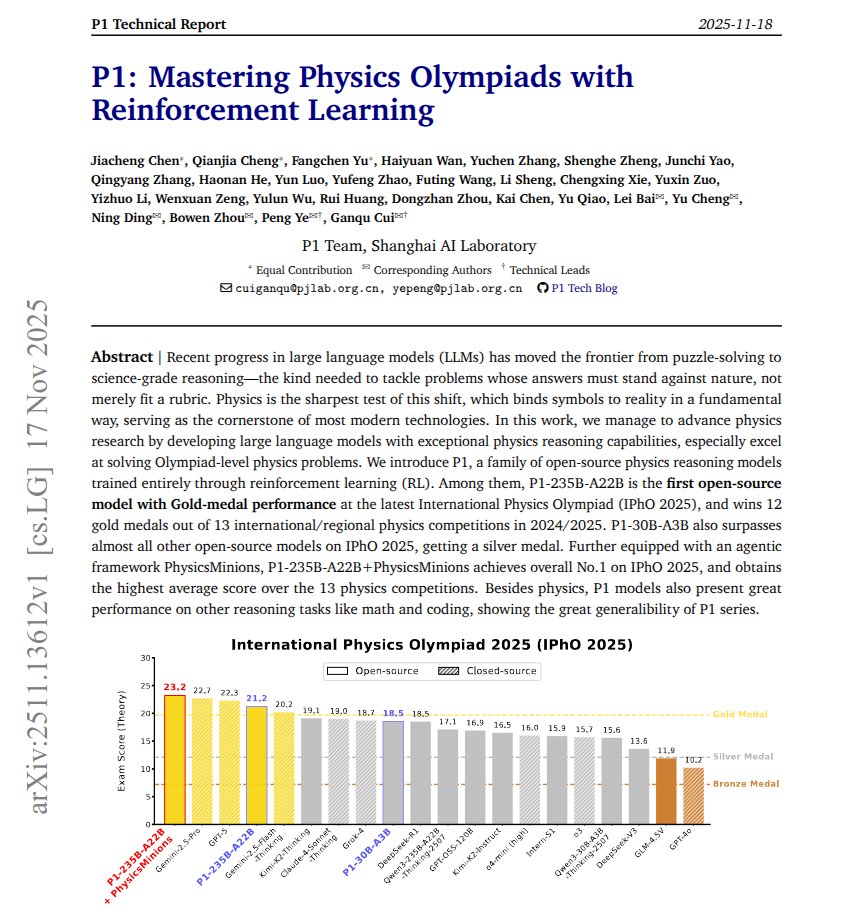
This paper trains an open-source model with reinforcement learning to solve very hard Olympiad physics at medal level.
The authors build a dataset of Olympiad physics questions with clear final answers and solutions, so the model can get automatic correct-or-wrong rewards.
They fine tune the base model by sampling attempts per problem, dropping impossible or trivial items, and gradually allowing more attempts and longer reasoning.
To keep training stable, they rely on strict rule-based answer checking and correct for mismatch between the fast rollout engine and the training engine.
At test time, they plug the model into PhysicsMinions, where one part solves, others review and verify, and this lifts scores across 13 Olympiads and helps math and coding.
----
Paper – arxiv. org/abs/2511.13612
Paper Title: "P1: Mastering Physics Olympiads with Reinforcement Learning"
Google just dropped "Attention is all you need (V2)"
This paper could solve AI's biggest problem:
Catastrophic forgetting.
When AI models learn something new, they tend to forget what they previously learned. Humans don't work this way, and now Google Research has a solution.
Nested Learning.
This is a new machine learning paradigm that treats models as a system of interconnected optimization problems running at different speeds - just like how our brain processes information.
Here's why this matters:
LLMs don't learn from experiences; they remain limited to what they learned during training. They can't learn or improve over time without losing previous knowledge.
Nested Learning changes this by viewing the model's architecture and training algorithm as the same thing - just different "levels" of optimization.
The paper introduces Hope, a proof-of-concept architecture that demonstrates this approach:
↳ Hope outperforms modern recurrent models on language modeling tasks
↳ It handles long-context memory better than state-of-the-art models
↳ It achieves this through "continuum memory systems" that update at different frequencies
This is similar to how our brain manages short-term and long-term memory simultaneously.
We might finally be closing the gap between AI and the human brain's ability to continually learn.
I've shared link to the paper in the next tweet!